Thus you can study Databricks Certified-Data-Engineer-Professional on your preferred smart device such as your smartphone or in hard copy format. Once downloaded from the website, you can easily study from the Databricks Certified-Data-Engineer-Professional Exam Questions compiled by our highly experienced professionals as directed by the Databricks exam syllabus.
| Section | Weight | Objectives |
|---|---|---|
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
>> Certified-Data-Engineer-Professional Book Free <<
We have installed the most advanced operation system in our company which can assure you the fastest delivery speed, to be specific, you can get immediately our Certified-Data-Engineer-Professional training materials only within five to ten minutes after purchase after payment. At the same time, your personal information will be encrypted automatically by our operation system as soon as you pressed the payment button, that is to say, there is really no need for you to worry about your personal information if you choose to buy the Certified-Data-Engineer-Professional Exam Practice from our company. We aim to leave no misgivings to our customers so that they are able to devote themselves fully to their studies on Certified-Data-Engineer-Professional guide materials: Databricks Certified Data Engineer Professional and they will find no distraction from us. I suggest that you strike while the iron is hot since time waits for no one.
NEW QUESTION # 13
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
Answer: B
Explanation:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
NEW QUESTION # 14
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
Answer: C
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 15
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.address THEN UPDATE SET current = false, end_date = staged_updates.effective_date WHEN NOT MATCHED THEN INSERT (customer_id, address, current, effective_date, end_date) VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
Answer: C
Explanation:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context. In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.
NEW QUESTION # 16
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")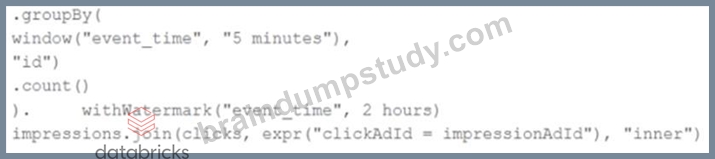
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
Answer: B
NEW QUESTION # 17
A data engineer is performing a join operation to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
Answer: D
Explanation:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support-matrix-for-joins-in-streaming-queries
NEW QUESTION # 18
......
We have livechat to wipe out your doubts about our Certified-Data-Engineer-Professional exam materials. You can ask any question about our Databricks Certified Data Engineer Professional study materials. All of our online workers are going through special training. They are familiar with all details of Certified-Data-Engineer-Professional practice guide. Also, you have easy access to Databricks Certified Data Engineer Professional free demo, and you are available for our free updated version of the Certified-Data-Engineer-Professional Real Exam. Whenever you have problems about our Certified-Data-Engineer-Professional study materials, you can contact our online workers via email. We warmly welcome you to experience our considerate service.
Certified-Data-Engineer-Professional Detail Explanation: https://www.braindumpstudy.com/Certified-Data-Engineer-Professional_braindumps.html