What's more, part of that PDFTorrent Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1RTx4z-4CFzcoxsuC_knhoaStWqrzSh9d
We are benefiting more and more candidates for our excellent Databricks-Generative-AI-Engineer-Associate exam materials which is compiled by the professional experts accurately and skillfully. We are called the best friend on the way with our customers to help pass their Databricks-Generative-AI-Engineer-Associate exam and help achieve their dreaming certification. The reason is that we not only provide our customers with valid and reliable Databricks-Generative-AI-Engineer-Associate study questions, but also offer best service online since we uphold the professional ethical.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Exam Price: | USD 200 |
| Exam Format: | Multiple choice, Multiple select |
| Available Languages: | English |
| Real Exam Qty: | 45-60 |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Generative-AI-Engineer-Associate Exam Torrent <<
We guarantee that after purchasing our Databricks-Generative-AI-Engineer-Associate exam torrent, we will deliver the product to you as soon as possible within ten minutes. So you don’t need to wait for a long time and worry about the delivery time or any delay. We will transfer our Databricks Certified Generative AI Engineer Associate prep torrent to you online immediately, and this service is also the reason why our Databricks-Generative-AI-Engineer-Associate Test Braindumps can win people’s heart and mind. Therefore, you are able to get hang of the essential points in a shorter time compared to those who are not willing to use our Databricks-Generative-AI-Engineer-Associate exam torrent.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 83
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: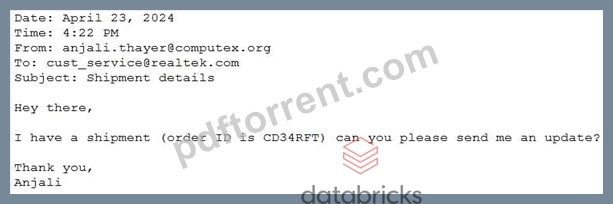
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: A
Explanation:
Problem Context : The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options :
* Option A : Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B : Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C : Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D : While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 84
A Generative AI Engineer is implementing a supervisor agent and two specialist agents in Databricks: a Sales Analyst for revenue questions and an HR Analyst for staff questions. Each specialist must retrieve data only from its own governed domain, and the engineer wants to preserve that separation using Databricks-native data access for each agent rather than building custom retrieval logic.
What should the engineer implement?
Answer: A
Explanation:
Separate Genie Spaces provide domain-specific access to structured business datasets through Databricks- native conversational querying. The Sales specialist calls the Sales Space, and the HR specialist calls the HR Space. Each Space should contain the appropriate datasets and business context, with Unity Catalog permissions enforcing access to its underlying resources. Separating Spaces makes domain boundaries explicit and avoids relying only on an LLM's routing instructions. Knowledge Assistants primarily support document-based knowledge retrieval, making Genie the better fit for structured business questions. A shared Space with distinct permissions can enforce security, but separate Spaces better express the requested domain separation. The video's phrase "HR Analyst for stock questions" appears inconsistent; "staff questions" is an inferred typing correction. Databricks documentation
NEW QUESTION # 85
A Generative Al Engineer is tasked with improving the RAG quality by addressing its inflammatory outputs.
Which action would be most effective in mitigating the problem of offensive text outputs?
Answer: A
Explanation:
Addressing offensive or inflammatory outputs in a Retrieval-Augmented Generation (RAG) system is critical for improving user experience and ensuring ethical AI deployment. Here's whyDis the most effective approach:
* Manual data curation: The root cause of offensive outputs often comes from the underlying data used to train the model or populate the retrieval system. By manually curating the upstream data and conducting thorough reviews before the data is fed into the RAG system, the engineer can filter out harmful, offensive, or inappropriate content.
* Improving data quality: Curating data ensures the system retrieves and generates responses from a high-quality, well-vetted dataset. This directly impacts the relevance and appropriateness of the outputs from the RAG system, preventing inflammatory content from being included in responses.
* Effectiveness: This strategy directly tackles the problem at its source (the data) rather than just mitigating the consequences (such as informing users or restricting access). It ensures that the system consistently provides non-offensive, relevant information.
Other options, such as increasing the frequency of data updates or informing users about behavior expectations, may not directly mitigate the generation of inflammatory outputs.
NEW QUESTION # 86
A Generative AI Engineer I using the code below to test setting up a vector store: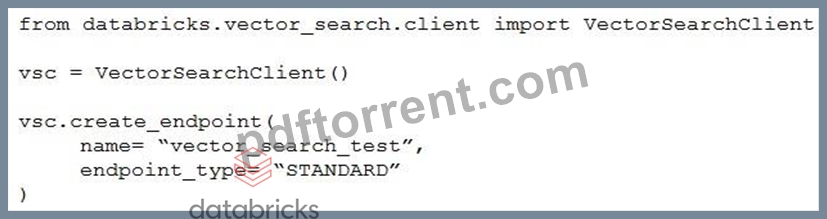
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 87
A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.
Which method should the engineer use to achieve this integration?
Answer: D
Explanation:
A Delta Sync index with managed embeddings supports the workflow described. The engineer identifies the source text column and configures the embedding model endpoint. Databricks computes embeddings as part of synchronization and maintains the corresponding searchable index. This removes the requirement to calculate vectors independently and write them into the source table before indexing. With self-managed embeddings, the application or upstream pipeline must already provide the embedding vectors. A Direct Vector Access index requires explicit updates through an API or SDK and does not automatically synchronize with the source Delta table. "Hybrid embedding computing" is not the relevant index configuration; hybrid search combines retrieval techniques. Managed embeddings and Delta synchronization therefore address both automatic vector generation and source-data integration. Databricks documentation
NEW QUESTION # 88
......
Cert Databricks-Generative-AI-Engineer-Associate Guide: https://www.pdftorrent.com/Databricks-Generative-AI-Engineer-Associate-exam-prep-dumps.html
BTW, DOWNLOAD part of PDFTorrent Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1RTx4z-4CFzcoxsuC_knhoaStWqrzSh9d