Databricks-Machine-Learning-Professional Updated CBT & Latest Databricks-Machine-Learning-Professional Exam Questions Vce

BTW, DOWNLOAD part of ActualtestPDF Databricks-Machine-Learning-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1xL3erS_UfLyhXMAVNAP908P6c7XePlPI
Desktop Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice exam software also keeps track of the earlier attempted Databricks Databricks-Machine-Learning-Professional practice test so you can know mistakes and overcome them at each and every step. The Desktop Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) practice exam software is created and updated in a timely by a team of experts in this field. If any problem arises, a support team is there to fix the issue.
| Topic | Details |
|---|
| Topic 1 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 2 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 3 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 4 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
>> Databricks-Machine-Learning-Professional Updated CBT <<
Latest Databricks-Machine-Learning-Professional Exam Questions Vce - Valid Exam Databricks-Machine-Learning-Professional Book
Success in the Databricks Databricks-Machine-Learning-Professional certification exam gives a huge boost to your career in the sector. You polish and validate your capabilities with the Databricks Databricks-Machine-Learning-Professional. However, certification test demands a thorough knowledge of Databricks Databricks-Machine-Learning-Professional Exam domains from credible preparation material, and this is the part where test takers lose hope.
Databricks Certified Machine Learning Professional Sample Questions (Q182-Q187):
NEW QUESTION # 182
A Machine Learning Engineer is working with a Spark DataFrame containing 100 million rows of retail transactions across thousands of stores. Each store requires its own demand forecasting model using the same scikit-learn pipeline. They want to train and apply these models in parallel for each store without collecting the data to the driver. Which approach will do this?
- A. Convert the DataFrame to a Pandas DataFrame using .toPandas() and loop through each store locally.
- B. Use groupBy("store_id").applyInPandas() to train and apply the model per group using a Pandas UDF.
- C. Use rdd.mapPartitions() to iterate through each store and apply the model logic in Python.
- D. Use pyspark.pandas to call .groupby("store_id").apply() and train the model on each group.
Answer: B
Explanation:
groupBy().applyInPandas() enables grouped Pandas UDFs that receive each store's data as a Pandas DataFrame on the executors. This allows training and applying a separate scikit-learn model per store in parallel without collecting data to the driver, making it the correct and scalable approach for large Spark DataFrames.
NEW QUESTION # 183
A Machine Learning Engineer is building a fraud detection model that needs to use both pre- computed features from a feature table and real-time calculated features based on user location data sent with each inference request. The engineer has created a Python UDF called calculate_distance in Unity Catalog at main.fraud_detection.calculate_distance that computes the distance between a transaction location and the user's current location. The feature table main.fraud_detection.user_features contains historical user spending patterns with primary key user_id.
The engineer has written the following code to implement this scenario:
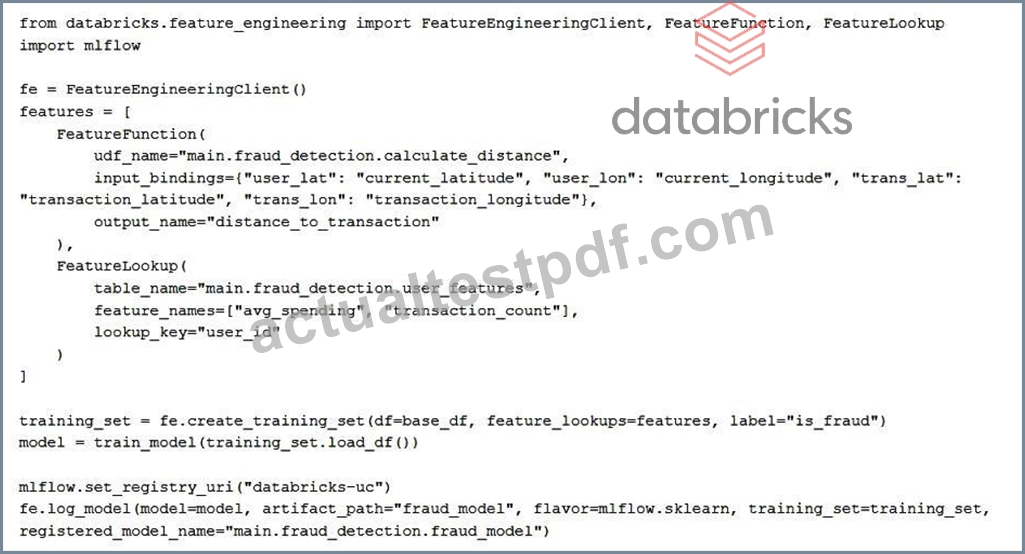
Which benefit of this implementation approach makes it suited to the real-time fraud detection use case?
- A. The FeatureLookup function avoids the need for joining the full table main.fraud_detection.user_features with training_set increasing efficiency.
- B. The model automatically performs feature lookup and computation during inference without additional serving code.
- C. The Unity Catalog registry automatically creates REST API endpoints for UDF functions used in feature computation.
- D. The FeatureFunction caches computed distance values in the online store to improve inference latency for location pairs.
Answer: B
Explanation:
By defining both FeatureLookup and FeatureFunction objects in the training set and logging the model with the FeatureEngineeringClient, the feature logic is packaged with the model. During inference, Databricks automatically performs feature lookups from the feature table and computes the on-demand distance feature using request-time inputs, without requiring any additional custom serving or feature-joining code. This makes the approach well suited for real-time fraud detection.
NEW QUESTION # 184
A machine learning engineering manager has asked all of the engineers on their team to add text descriptions to each of the model projects in the MLflow Model Registry. They are starting with the model project "model" and they'd like to add the text in the model_description variable.
The team is using the following line of code:
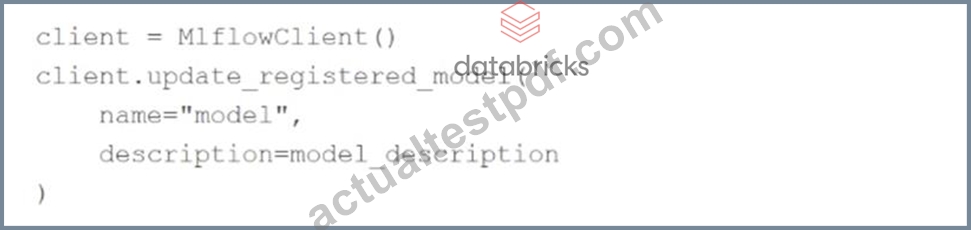
Which of the following changes does the team need to make to the above code block to accomplish the task?
- A. There no changes necessary
- B. Replace update_registered_model with update_model_version
- C. Replace client.update_registered_model with mlflow
- D. Replace description with artifact
- E. Add a Python model as an argument to update_registered_model
Answer: A
NEW QUESTION # 185
A Machine Learning Engineer has deployed a fraud detection model in Databricks Model Serving to detect fraudulent transactions. The engineer wants to compare the model's predictions with the actual fraud classifications from the Fraud Ops team to monitor model performance. The Fraud Ops team uses a unique transaction_id to investigate fraudulent activity and persist their findings to a fraud_findings table. The engineer enabled inference tables on the endpoint, but they are not sure how to map the models' predictions to the Fraud Ops team's classifications. How can the engineer uniquely join the models' prediction to the fraud_findings table with the fewest code changes?
- A. Store databricks_request_id returned from each model serving request and persist it to the fraud_findings table. Join the inference table with the fraud_findings table using databricks_request_id as the join key.
- B. Populate the client_request_id field with the transaction_id in the model serving request body.
Join the inference table with the fraud_findings table using client_request_id (which contains the transaction_id) as the join key. - C. Join the inference table with the fraud_findings table using timestamp_ms as the join key.
- D. Modify the model to include an additional input: transaction_id. Log, register and deploy the new model. In the model serving request body, add transaction_id as an additional input feature. Join the inference table with the fraud_findings table using transaction_id as the join key.
Answer: B
Explanation:
Databricks Model Serving inference tables automatically log the client_request_id field for each request. By populating this field with the existing transaction_id in the request body, the engineer can directly and uniquely join inference predictions with the fraud_findings table using the same identifier, achieving accurate performance monitoring with minimal code changes and no model retraining or redeployment.
NEW QUESTION # 186
A machine learning engineer wants to load the data from the very first version of a Delta table from location path. Which of the following lines of code can be used to accomplish this task?
- A. spark.read.format("delta").option("versionAsOf", 0).load(path)
- B. spark.read.format("delta").option("version", 1).load(path)
- C. spark.read.format("delta").option("versionAsOf", 1).load(path)
- D. spark.read.format("delta").option("version", 0).load(path)
Answer: C
Explanation:
In Delta Lake, the option("versionAsOf", <version_number>) parameter is used to load a specific version of a Delta table.
Since Delta table versions are 1-indexed (the first version is version 1), using .option("versionAsOf", 1) correctly loads the very first version of the table.
NEW QUESTION # 187
......
Our service tenet is to let the clients get the best user experiences and be satisfied. From the research, compiling, production to the sales, after-sale service, we try our best to provide the conveniences to the clients and make full use of our Databricks-Machine-Learning-Professional study materials. We organize the expert team to compile the Databricks-Machine-Learning-Professional Study Materials elaborately and constantly update them. To let the clients have a fundamental understanding of our Databricks-Machine-Learning-Professional study materials, we provide the free trials before their purchasing.
Latest Databricks-Machine-Learning-Professional Exam Questions Vce: https://www.actualtestpdf.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
- Exam Databricks-Machine-Learning-Professional Questions Answers 😛 Dumps Databricks-Machine-Learning-Professional Collection ☑ Test Databricks-Machine-Learning-Professional Simulator Free 🌻 Simply search for [ Databricks-Machine-Learning-Professional ] for free download on ➥ www.easy4engine.com 🡄 👘Practice Databricks-Machine-Learning-Professional Test
- New Exam Databricks-Machine-Learning-Professional Braindumps 🎇 Valid Databricks-Machine-Learning-Professional Exam Fee 🌽 Dumps Databricks-Machine-Learning-Professional Collection 🚦 Go to website ➥ www.pdfvce.com 🡄 open and search for ➤ Databricks-Machine-Learning-Professional ⮘ to download for free 🍂Databricks-Machine-Learning-Professional Practice Exam Fee
- Latest Databricks-Machine-Learning-Professional Dumps Ebook 👽 Valid Databricks-Machine-Learning-Professional Torrent ♥ Databricks-Machine-Learning-Professional Reliable Test Price 🍈 Download ⮆ Databricks-Machine-Learning-Professional ⮄ for free by simply searching on ➤ www.prep4away.com ⮘ 🐡Databricks-Machine-Learning-Professional Best Practice
- Pass Guaranteed Quiz 2026 Databricks Reliable Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Updated CBT 🏭 Open ➤ www.pdfvce.com ⮘ and search for ➠ Databricks-Machine-Learning-Professional 🠰 to download exam materials for free 🖼Databricks-Machine-Learning-Professional Reliable Test Testking
- Pass Guaranteed Quiz 2026 Databricks Valid Databricks-Machine-Learning-Professional Updated CBT 🐨 Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and obtain a free download on ☀ www.dumpsquestion.com ️☀️ 🚕Valid Databricks-Machine-Learning-Professional Torrent
- Three formats of the Databricks Databricks-Machine-Learning-Professional Exam Dumps 🕷 Download ( Databricks-Machine-Learning-Professional ) for free by simply searching on 【 www.pdfvce.com 】 🕢Databricks-Machine-Learning-Professional Reliable Test Price
- Pass Guaranteed Quiz 2026 Databricks Valid Databricks-Machine-Learning-Professional Updated CBT 🏯 Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and easily obtain a free download on ⇛ www.vce4dumps.com ⇚ 🌟New Exam Databricks-Machine-Learning-Professional Braindumps
- Databricks-Machine-Learning-Professional Reliable Test Blueprint 🐃 Valid Databricks-Machine-Learning-Professional Torrent 📬 Dumps Databricks-Machine-Learning-Professional Collection 🆔 Download ➥ Databricks-Machine-Learning-Professional 🡄 for free by simply searching on ▶ www.pdfvce.com ◀ 🌉Latest Databricks-Machine-Learning-Professional Dumps Ebook
- Databricks-Machine-Learning-Professional Reliable Test Testking 👼 Databricks-Machine-Learning-Professional Reliable Test Price 🕵 Databricks-Machine-Learning-Professional Best Practice 🥺 The page for free download of “ Databricks-Machine-Learning-Professional ” on { www.practicevce.com } will open immediately 👒Valid Databricks-Machine-Learning-Professional Study Materials
- Databricks-Machine-Learning-Professional Best Practice 🚋 Databricks-Machine-Learning-Professional Reliable Test Price 💃 Latest Databricks-Machine-Learning-Professional Exam Test 🩱 The page for free download of ⮆ Databricks-Machine-Learning-Professional ⮄ on ➡ www.pdfvce.com ️⬅️ will open immediately 🐹Latest Databricks-Machine-Learning-Professional Exam Test
- Pass Guaranteed Quiz 2026 Databricks Valid Databricks-Machine-Learning-Professional Updated CBT 🕓 Open ➠ www.troytecdumps.com 🠰 enter 【 Databricks-Machine-Learning-Professional 】 and obtain a free download 🔴Latest Databricks-Machine-Learning-Professional Exam Test
- telegra.ph, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that ActualtestPDF Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1xL3erS_UfLyhXMAVNAP908P6c7XePlPI