2026 Latest TestPassKing Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1tyhq9pXgHDKUl9yYJT7lEbx_zFpPOyQ6
Professional-Machine-Learning-Engineer exam dumps allow free trial downloads. You can get the information you want to know through the trial version. After downloading our study materials trial version, you can also easily select the version you like, as well as your favorite Professional-Machine-Learning-Engineer Exam Prep, based on which you can make targeted choices. Our study materials want every user to understand the product and be able to really get what they need.
| Section | Objectives |
|---|---|
| Topic 1: Data preparation and processing | - Feature engineering
|
| Topic 2: Designing ML solutions | - Framing ML problems
|
| Topic 3: Deployment and operations | - Model deployment
|
| Topic 4: ML model development | - Model training and tuning
|
| Topic 5: ML pipeline automation and orchestration | - Pipeline design
|
>> Exam Google Professional-Machine-Learning-Engineer Preview <<
TestPassKing ensure that the first time you take the exam will be able to pass the exam to obtain the exam certification. Because TestPassKing can provide to you the highest quality analog Google Professional-Machine-Learning-Engineer Exam will take you into the exam step by step. TestPassKing guarantee that Google Professional-Machine-Learning-Engineer exam questions and answers can help you to pass the exam successfully.
NEW QUESTION # 126
You recently used BigQuery ML to train an AutoML regression model. You shared results with your team and received positive feedback. You need to deploy your model for online prediction as quickly as possible.
What should you do?
Answer: B
Explanation:
BigQuery ML is a service that allows you to create and train ML models using SQL queries. You can use BigQuery ML to train an AutoML regression model, which is a type of model that automatically selects the best features and architecture for your data. You can also specify Vertex AI as the model registry, which is a service that allows you to store and manage your ML models. By using Vertex AI as the model registry, you can easily deploy your model to a Vertex AI endpoint, which is a service that allows you to serve your ML models online and scale them automatically. By using BigQuery ML, Vertex AI model registry, and Vertex AI endpoint, you can deploy your model for online prediction as quickly as possible, without having to export, import, or retrain your model. References:
* BigQuery ML documentation
* Vertex AI documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 127
A web-based company wants to improve its conversion rate on its landing page. Using a large historical dataset of customer visits, the company has repeatedly trained a multi-class deep learning network algorithm on Amazon SageMaker. However, there is an overfitting problem: training data shows 90% accuracy in predictions, while test data shows 70% accuracy only.
The company needs to boost the generalization of its model before deploying it into production to maximize conversions of visits to purchases.
Which action is recommended to provide the HIGHEST accuracy model for the company's test and validation data?
Answer: C
NEW QUESTION # 128
You are building an ML model to detect anomalies in real-time sensor data. You will use Pub/Sub to handle incoming requests. You want to store the results for analytics and visualization. How should you configure the pipeline?
Answer: B
Explanation:
* Dataflow is a fully managed service for executing Apache Beam pipelines that can process streaming or batch data1.
* Al Platform is a unified platform that enables you to build and run machine learning applications across Google Cloud2.
* BigQuery is a serverless, highly scalable, and cost-effective cloud data warehouse designed for business agility3.
These services are suitable for building an ML model to detect anomalies in real-time sensor data, as they can handle large-scale data ingestion, preprocessing, training, serving, storage, and visualization. The other options are not as suitable because:
* DataProc is a service for running Apache Spark and Apache Hadoop clusters, which are not optimized for streaming data processing4.
* AutoML is a suite of machine learning products that enables developers with limited machine learning expertise to train high-quality models specific to their business needs5. However, it does not support custom models or real-time predictions.
* Cloud Bigtable is a scalable, fully managed NoSQL database service for large analytical and operational workloads. However, it is not designed for ad hoc queries or interactive analysis.
* Cloud Functions is a serverless execution environment for building and connecting cloud services.
However, it is not suitable for storing or visualizing data.
* Cloud Storage is a service for storing and accessing data on Google Cloud. However, it is not a data warehouse and does not support SQL queries or visualization tools.
NEW QUESTION # 129
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?


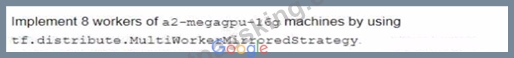

Answer: D
NEW QUESTION # 130
You work for a magazine distributor and need to build a model that predicts which customers will renew their subscriptions for the upcoming year. Using your company's historical data as your training set, you created a TensorFlow model and deployed it to AI Platform. You need to determine which customer attribute has the most predictive power for each prediction served by the model. What should you do?
Answer: D
Explanation:
* Option A is incorrect because using AI Platform notebooks to perform a Lasso regression analysis on your model, which will eliminate features that do not provide a strong signal, is not a suitable way to determine which customer attribute has the most predictive power for each prediction served by the model. Lasso regression is a method of feature selection that applies a penalty to the coefficients of the linear model, and shrinks them to zero for irrelevant features1. However, this method assumes that the model is linear and additive, which may not be the case for a TensorFlow model. Moreover, this method does not provide feature attributions for each prediction, but rather for the entire dataset.
* Option B is incorrect because streaming prediction results to BigQuery, and using BigQuery's CORR (X1, X2) function to calculate the Pearson correlation coefficient between each feature and the target variable, is not a valid way to determine which customer attribute has the most predictive power for each prediction served by the model. The Pearson correlation coefficient is a measure of the linear relationship between two variables, ranging from -1 to 12. However, this method does not account for the interactions between features or the non-linearity of the model. Moreover, this method does not provide feature attributions for each prediction, but rather for the entire dataset.
* Option C is correct because using the AI Explanations feature on AI Platform, and submitting each prediction request with the 'explain' keyword to retrieve feature attributions using the sampled Shapley method, is the best way to determine which customer attribute has the most predictive power for each prediction served by the model. AI Explanations is a service that allows you to get feature attributions for your deployed models on AI Platform3. Feature attributions are values that indicate how much each feature contributed to the prediction for a given instance4. The sampled Shapley method is a technique that uses the Shapley value, a game-theoretic concept, to measure the contribution of each feature to the prediction5. By using AI Explanations, you can get feature attributions for each prediction request, and identify the most important features for each customer.
* Option D is incorrect because using the What-If tool in Google Cloud to determine how your model will perform when individual features are excluded, and ranking the feature importance in order of those that caused the most significant performance drop when removed from the model, is not a practical way to determine which customer attribute has the most predictive power for each prediction served by the model. The What-If tool is a tool that allows you to visualize and analyze your ML models and datasets. However, this method requires manually editing or removing features for each instance, and observing the change in the prediction. This method is not scalable or efficient, and may not capture the interactions between features or the non-linearity of the model.
References:
* Lasso regression
* Pearson correlation coefficient
* AI Explanations overview
* Feature attributions
* Sampled Shapley method
* [What-If tool overview]
NEW QUESTION # 131
......
When we started offering Google Professional-Machine-Learning-Engineer exam questions and answers and exam simulator, we did not think that we will get such a big reputation. What we are doing now is incredible form of a guarantee. TestPassKing guarantee passing rate of 100%, you use your Google Professional-Machine-Learning-Engineer Exam to try our Google Professional-Machine-Learning-Engineer training products, this is correct, we can guarantee your success.
Exam Professional-Machine-Learning-Engineer Braindumps: https://www.testpassking.com/Professional-Machine-Learning-Engineer-exam-testking-pass.html
DOWNLOAD the newest TestPassKing Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1tyhq9pXgHDKUl9yYJT7lEbx_zFpPOyQ6