P.S. Free & New SPS-C01 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1eXYSN__GIRjYPOAaE_B8pG-yGiJm0zov
When we update the SPS-C01 preparation questions, we will take into account changes in society, and we will also draw user feedback. If you have any thoughts and opinions in using our SPS-C01 study materials, you can tell us. We hope to grow with you and the continuous improvement of SPS-C01 training engine is to give you the best quality experience. And you can get the according SPS-C01 certification as well.
| Section | Objectives |
|---|---|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
>> Snowflake SPS-C01 Pass4sure Study Materials <<
Top Rated Features of Snowflake SPS-C01 Practice Test Questions. The SurePassExams is committed to making the Snowflake SPS-C01 exam preparation journey simple, smart, and swift. To meet this objective the SurePassExams is offering SPS-C01 practice test questions with top-rated features. These features are updated and real Snowflake SPS-C01 Exam Questions, availability of Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 exam real questions in three easy-to-use and compatible formats, three months free updated Snowflake SPS-C01 exam questions download facility, affordable price and 100 percent Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 exam passing money back guarantee.
NEW QUESTION # 58
Consider the following Snowpark Python code snippet designed to calculate the moving average of sales data'. You've identified that the code is performing poorly and suspect the window function is a bottleneck. How can you optimize this code for better performance?
Answer: B,C
Explanation:
Caching the DataFrame allows reuse of the data and avoids recomputation, improving performance. Rewriting the logic with aggregation queries is a viable optimization. Partitioning by a cardinal column does not improve performance. Presorting the data before creating the DataFrame does not affect Window function performance. Range-based windows are not always a direct replacement and have specific use cases.
NEW QUESTION # 59
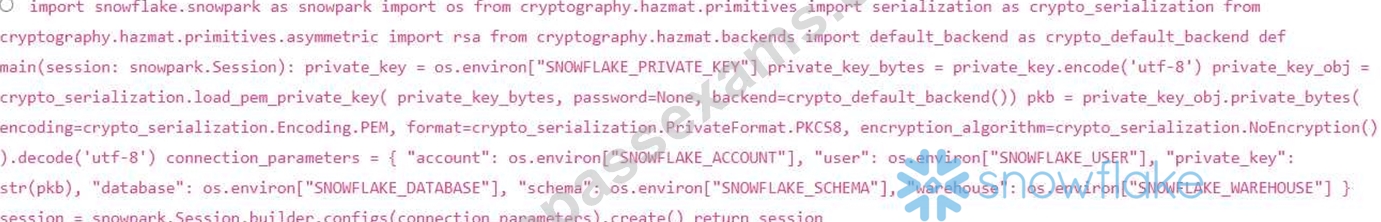
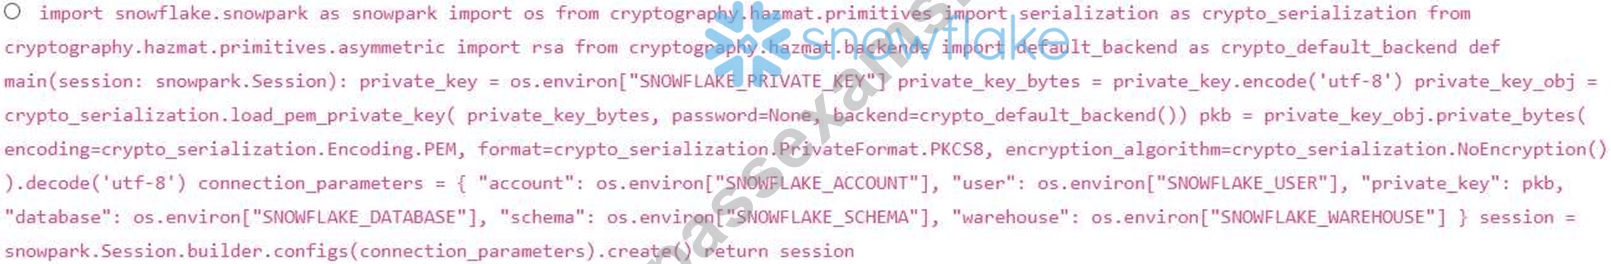
You are developing a Snowpark Python application that connects to Snowflake using key pair authentication. You have the private key stored securely in an environment variable named 'SNOWFLAKE PRIVATE KEY. Which of the following code snippets correctly establishes a Snowpark session using this method, assuming all other necessary connection parameters (account, user, database, schema, warehouse) are also set as environment variables?



Answer: E
Explanation:
Option D is correct because it properly retrieves the private key from the environment variable, decodes the PEM format, and passes it to the connection parameters after converting the key object to a string. It uses the cryptography library to handle the private key securely, which is required for key pair authentication. The code snippet decodes the private key using cryptography library and creates a string, which then is passed to the connection parameters to create a session. Option A fails to use the cryptography library and just passes the private key directly. Option B is incorrect because it doesn't use the 'configs' method, which is the correct way to pass all connection parameters at once. Option C doesn't encode the private key properly, and does not convert to string after decoding using cryptography. Option E does convert to string, but is not secure as the private key is directly passed without decoding it using the cryptography library.
NEW QUESTION # 60
You are tasked with building a data pipeline that uses Snowpark to process customer data in a table called 'CUSTOMERS'. The table contains sensitive information, and you need to ensure that any Personally Identifiable Information (PII) is removed from the table after 30 days. You decide to implement a mechanism to automatically delete records older than 30 days. Which of the following approaches would you consider when designing the deletion process with consideration of cost, performance and security?
Answer: A,C,D
Explanation:
Options B, C and E are viable and have tradeoffs. A and D will be less ideal. Option A : This approach can be very inefficient as it requires scanning the entire table daily to identify records for deletion. This can lead to high costs and performance issues. Option B : Using a Snowflake Task with a direct SQL DELETE statement is generally more efficient than reading the entire table in Snowpark, especially for large tables. Snowflake can optimize the DELETE operation internally. Option C : Encapsulating the deletion logic in a Snowpark Stored Procedure and scheduling it with a Snowflake Task allows you to leverage Snowpark's capabilities while benefiting from Snowflake's task scheduling and optimization. This can offer a good balance of flexibility and performance. Option D : This is an archive solution, not deletion; it's not as fast or space saving as truncating. Option E : Data masking is a secure alternative. It preserves the records while redacting sensitive data. No need to scan for old records, so its best on performance, cost, and security.
NEW QUESTION # 61
A Snowpark application frequently experiences performance degradation during peak hours. You suspect that resource contention on the virtual warehouse is the primary cause. Which of the following actions, when implemented together, would BEST address this issue and ensure consistent performance?
Answer: B,C
Explanation:
Workload management rules (A) allow you to prioritize Snowpark workloads, ensuring they receive preferential access to resources during peak hours. Creating separate virtual warehouses (C) isolates different workloads, preventing resource contention and allowing you to apply resource monitors for cost control. Shortening AUTO SUSPEND (B) may lead to frequent warehouse starts, increasing costs. Query acceleration (D) can help, but it might not be the most cost-effective solution for all queries. Converting DataFrames to views (E) doesn't directly address resource contention.
NEW QUESTION # 62
You have a Snowpark DataFrame 'df containing customer data with columns 'customer_id', 'signup_date' (TIMESTAMP NTZ), and 'country'. You need to create a new DataFrame that calculates the number of days since each customer signed up, but only for customers in 'USA' and 'Canada'. Furthermore, you want to filter out records where the signup was more than 365 days ago. Which of the following Snowpark code snippets will achieve this most efficiently?





Answer: E
Explanation:
Option E is the most efficient. It first filters the DataFrame by country using 'isin' , which is optimized for multiple values. Then, it calculates 'days_since_signup' using 'datediff and finally filters based on the number of days. Option A is correct but not as efficient as using 'isin-. Option B calculates 'days_since_signup' before filtering, which is less efficient. Option C uses 'to_number' which would result in the difference being represented in milliseconds and would require further conversion. Also using 'to_number' may lead to data loss. Option D has incorrect operator precedence in the 'where' clause, making it functionally wrong.
NEW QUESTION # 63
......
SurePassExams is a trusted platform that is committed to helping Snowflake SPS-C01 exam candidates in exam preparation. The Snowflake SPS-C01 exam questions are real and updated and will repeat in the upcoming Snowflake SPS-C01 Exam Dumps. By practicing again and again you will become an expert to solve all the Snowflake SPS-C01 exam questions completely and before the exam time.
Valid SPS-C01 Test Cost: https://www.surepassexams.com/SPS-C01-exam-bootcamp.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1eXYSN__GIRjYPOAaE_B8pG-yGiJm0zov