Our DP-750 study guide design three different versions for all customers. These three different versions include PDF version, software version and online version, they can help customers solve any problems in use, meet all their needs. Although the three major versions of our DP-750 exam dumps provide a demo of the same content for all customers, they will meet different unique requirements from a variety of users based on specific functionality. The most important feature of the online version of our DP-750 Learning Materials are practicality. The online version is open to all electronic devices, which will allow your device to have common browser functionality so that you can open our products. At the same time, our online version of the DP-750 study guide can also be implemented offline, which is a big advantage that many of the same educational products are not able to do on the market at present.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Relevant DP-750 Exam Dumps <<
Today is the right time to advance your career. Yes, you can do this easily. Just need to pass the DP-750 certification exam. Are you ready for this? If yes then get registered in Microsoft DP-750 certification exam and start preparation with top-notch Real4test DP-750 Exam Practice questions today. These Microsoft DP-750 questions are available at Real4test with up to 1 year of free updates.
NEW QUESTION # 24
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 25
Hotspot Question
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2.
You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running.
How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.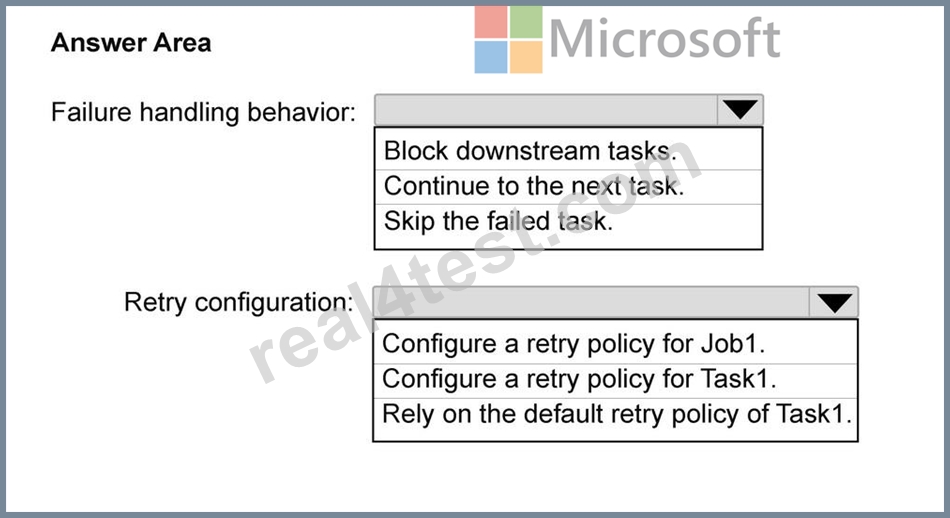
Answer:
Explanation: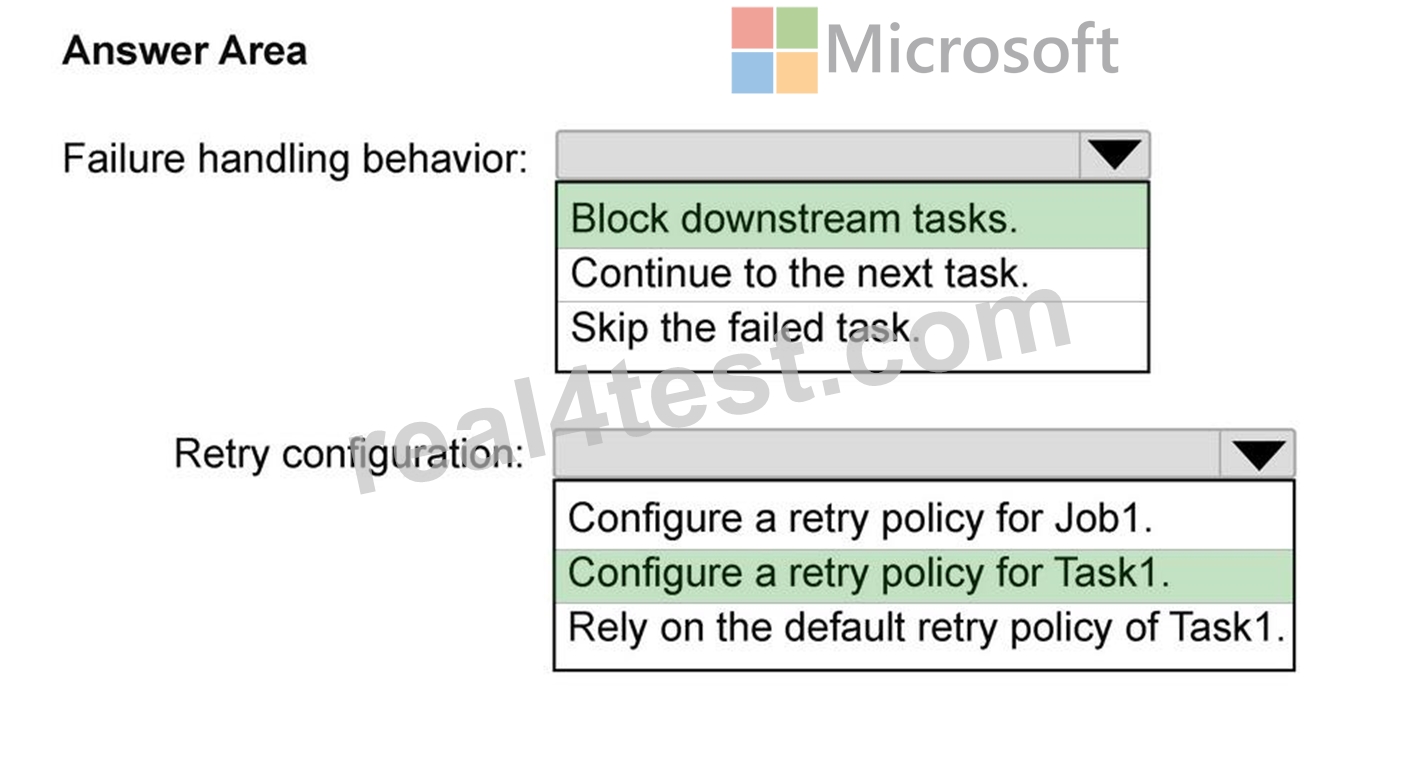
NEW QUESTION # 26
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.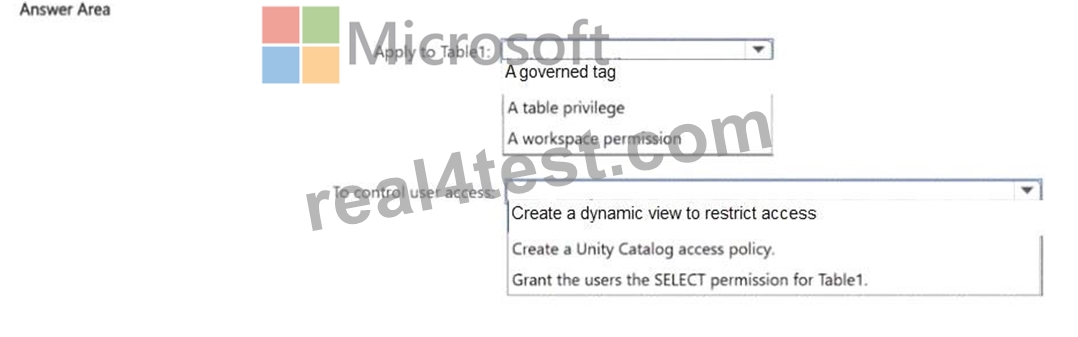
Answer:
Explanation: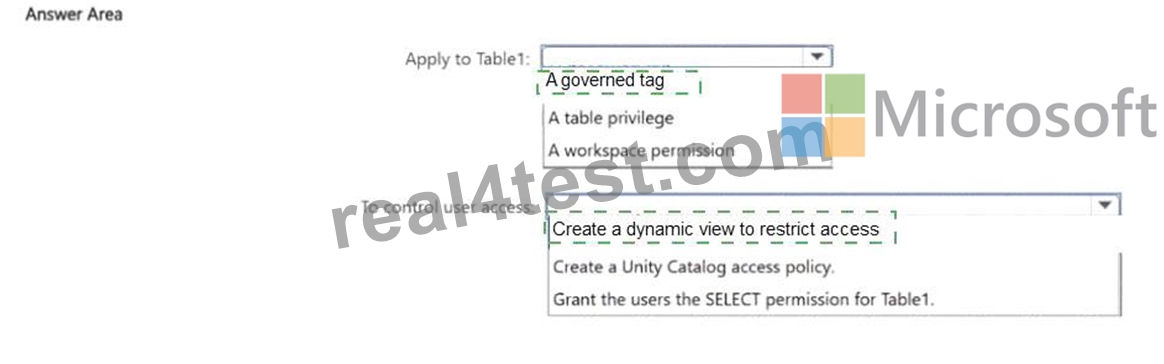
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 27
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluster1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: C
Explanation:
The best action is uploading the libraries to the workspace and installing the libraries on the cluster (or ideally uploading them to Unity Catalog volumes).
Unity Catalog Compatibility: When using Unity Catalog for access control, compute clusters are typically configured with Standard (Shared) access mode. In this mode, traditional cluster init scripts [Not B.] face strict execution restrictions or are completely blocked to maintain secure user isolation.
Governance: Uploading your packages as Workspace Files or to Unity Catalog volumes allows administrators to manage access permissions directly and add them to an allowlist if needed.
Cluster-Wide Availability: Installing the libraries via the cluster's Libraries tab ensures that the required ingestion packages are automatically pre-installed and available across all nodes and notebooks running on that cluster.
Incorrect:
[Not A]
Running pip3 install manually on a cluster terminal or inside a notebook only applies to the specific notebook session (notebook-scoped). It does not natively persist across cluster restarts or handle cross-node execution effectively for data ingestion pipelines.
[Not B]
Running a custom script or a legacy init script to modify system-level paths introduces security risks and is generally incompatible with Unity Catalog's strict execution isolation policies for shared compute.
Reference:
https://docs.databricks.com/aws/en/libraries/
NEW QUESTION # 28
Which tool is best for continuous ingestion of files landing in Azure Data Lake?
Answer: D
Explanation:
Auto Loader is optimized for incremental and continuous ingestion from cloud storage. It detects new files automatically and scales efficiently. Databricks Jobs schedule tasks but do not handle file detection. Logic Apps are workflow tools. ADF is batch-oriented.
NEW QUESTION # 29
......
Questions remain unsuccessful in the DP-750 test and lose their resources. That's why Real4test is offering real Microsoft DP-750 Questions that are real and can save you from wasting time and money. Hundreds of applicants have studied successfully from our DP-750 latest questions in one go. We have launched our DP-750 Practice Test after consulting with experts who have years of experience in this field. People who have used our DP-750 exam preparation material rated it as the best option to study for the DP-750 exam in a short time.
Exam DP-750 Tutorials: https://www.real4test.com/DP-750_real-exam.html