2026 Latest Pass4Leader NCP-AII PDF Dumps and NCP-AII Exam Engine Free Share: https://drive.google.com/open?id=1rYMDXZ7exvDLqlarwP0pOEvthMo2PfNb
Our NVIDIA NCP-AII practice test software is the most distinguished source for the NVIDIA NCP-AII exam all over the world because it facilitates your practice in the practical form of the NVIDIA AI Infrastructure certification exam. Moreover, you do not need an active internet connection to utilize NVIDIA NCP-AII Practice Exam software. It works without the internet after software installation on Windows computers.
| Certification Vendor: | NVIDIA |
|---|---|
| Exam Name: | NVIDIA Certified Professional – AI Infrastructure |
| Exam Number: | NCP-AII |
| Passing Score: | 700 (scale of 0-1000) |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Select, Multiple Choice |
| Related Certifications: | NCP-AI NCP-DES |
| Exam Duration: | 90 minutes |
| Available Languages: | English |
| Real Exam Qty: | 50 |
| Exam Price: | $195 USD |
| Sample Questions: | NVIDIA NCP-AII Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: hands-on experience with NVIDIA AI infrastructure products; basic knowledge of Linux, networking, and data center operations |
| Official Syllabus URL: | https://www.nvidia.com/en-us/certifications/ncp-ai-infra/ |
NCP-AII certification can demonstrate your mastery of certain areas of knowledge, which is internationally recognized and accepted by the general public as a certification. NCP-AIIcertification is so high that it is not easy to obtain it. It requires you to invest time and energy. If you are not sure whether you can strictly request yourself, our NCP-AII test materials can help you. With high pass rate of our NCP-AII exam questons as more than 98%, you will find that the NCP-AII exam is easy to pass.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 40
You're configuring a RoCEv2 network for your AI infrastructure. Which UDP port number range is commonly used for RoCEv2 traffic, and why is it important to be aware of this?
Answer: B
Explanation:
RoCEv2 commonly uses the dynamic/private port range (49152-65535). This avoids potential conflicts with well-known or registered ports used by other services. Knowing this range is crucial for configuring firewalls and network policies to allow RoCEv2 traffic to flow freely.
NEW QUESTION # 41
You are running a Docker container with GPU support using 'nvidia-docker run'. The containerized application unexpectedly fails to detect the GPU. What is the most likely cause?
Answer: B
Explanation:
When running containers that need GPU access, it's essential to explicitly request the GPU resources. The '-gpus all' or '-gpus device=..: flag passed to 'docker run' with the NVIDIA runtime allows the container access to the available GPUs. Without this flag, the container operates as if no GPUs are available. Options A, B, C and D, while potentially problematic, are not the most likely cause if 'nvidia-docker run' was used previously.
NEW QUESTION # 42
After upgrading to HPL-AI 2.0 on a DGX A100 cluster, a 2x performance gain is observed. Which optimization is primarily responsible for this improvement?
Answer: D
Explanation:
HPL-AI (High-Performance Linpack for AI) differs from traditional HPL by utilizing lower-precision arithmetic (FP16/BF16/TF32) while maintaining FP64 accuracy through iterative refinement. The significant jump in performance seen in version 2.0 and above is largely attributed to advancements in the communication layer. In multi-node DGX clusters, the CPU often becomes a bottleneck when managing MPI (Message Passing Interface) ranks and coordinating data transfers between GPUs across the InfiniBand fabric.
By implementingMPI-aware GPU communication(and leveraging technologies like SharpV3 or NCCL integration), the benchmark significantly reduces the "GPU Idle Time" spent waiting for the CPU to orchestrate the next computation block. This optimization ensures that the GPUs remain at near 100% utilization during the intensive matrix multiplication phases. By offloading collective operations and using GPUDirect RDMA, the system bypasses the host memory and CPU, effectively doubling the effective throughput of the benchmark compared to older, CPU-heavy coordination methods.
NEW QUESTION # 43
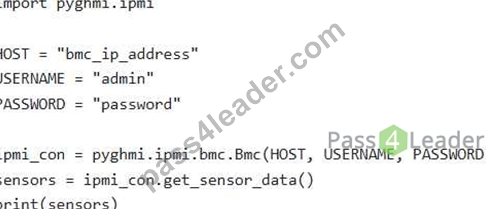
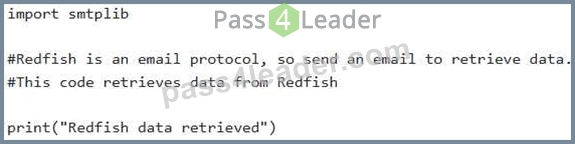
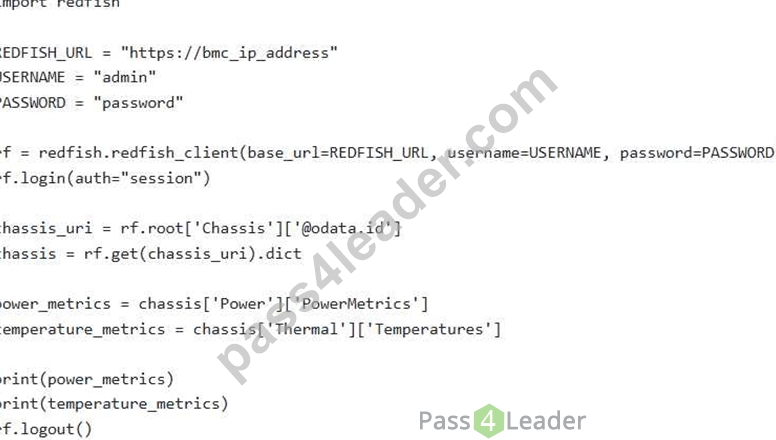
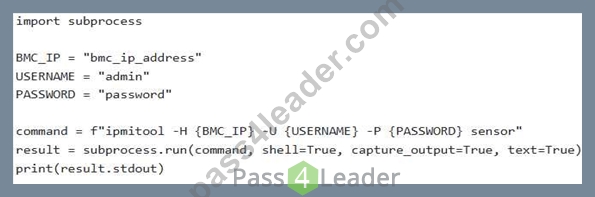
You are tasked with implementing a monitoring solution for power consumption and thermal performance in an NVIDIA-powered Ai cluster. You want to collect data from the Baseboard Management Controllers (BMCs) of the servers using Redfish. Which of the following Python code snippets demonstrates the correct approach for authenticating with the BMC and retrieving power and temperature readings?
Answer: D
Explanation:
Option A provides a valid example using the 'redfish' library to connect to a BMC, authenticate, and retrieve power and temperature readings. It uses the correct Redfish API structure to access the relevant data. Option B uses 'ipmitoor' , which is another valid approach but less modern than Redfish. Option C uses 'pyghmi.ipmi', which is an older IPMI library. Option D is incorrect; Redfish can be accessed via Python. Option E is nonsense; Redfish is not an email protocol.
NEW QUESTION # 44
An enterprise is designing a new AI training environment expected to expand from 32 GPUs to more than 1,000 GPUs within two years. Management wants to minimize future architectural changes while maintaining high throughput for distributed training. Which infrastructure design strategy best supports these long-term objectives?
Answer: D
Explanation:
Large AI clusters should be designed around scalable, high-bandwidth fabrics such as InfiniBand or optimized Ethernet with RoCE. Modular network architectures allow additional compute nodes to be integrated without redesigning the infrastructure. Direct server-to-server cabling does not scale, while relying solely on larger servers limits future growth and flexibility.
NEW QUESTION # 45
......
Latest NCP-AII Exam Cost: https://www.pass4leader.com/NVIDIA/NCP-AII-exam.html
BONUS!!! Download part of Pass4Leader NCP-AII dumps for free: https://drive.google.com/open?id=1rYMDXZ7exvDLqlarwP0pOEvthMo2PfNb