DOWNLOAD the newest Real4test DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1HeCvhSWGCqaY2n7405VNywMD0CSIM8Vk
Real4test's providing training material is very close to the content of the formal examination. Through our short-term special training You can quickly grasp IT professional knowledge, and then have a good preparation for your exam. We promise that we will do our best to help you pass the Microsoft Certification DP-100 Exam.
| Section | Objectives |
|---|---|
| Topic 1: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Topic 2: Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
| Topic 3: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 4: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 5: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
Real4test DP-100 exam dumps have been designed with the best possible format, ensuring all necessary information packed in them. Our experts have used only the authentic and recommended sources of studies by the certifications vendors for exam preparation. The information in the DP-100 Brain Dumps has been made simple up to the level of even an average exam candidate. To ease you in your preparation, each DP-100 dumps are made into easy English so that you learn information without any difficulty to understand them.
NEW QUESTION # 122
You are retrieving data from a large datastore by using Azure Machine Learning Studio.
You must create a subset of the data for testing purposes using a random sampling seed based on the system clock.
You add the Partition and Sample module to your experiment.
You need to select the properties for the module.
Which values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.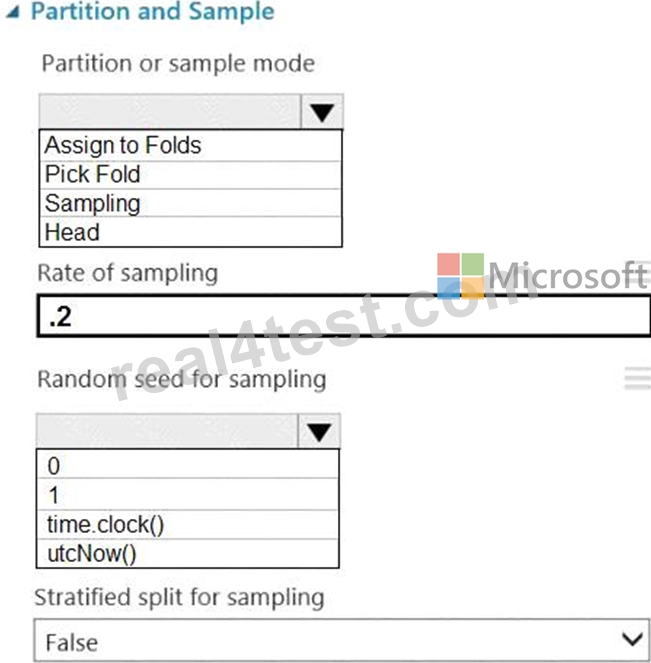
Answer:
Explanation: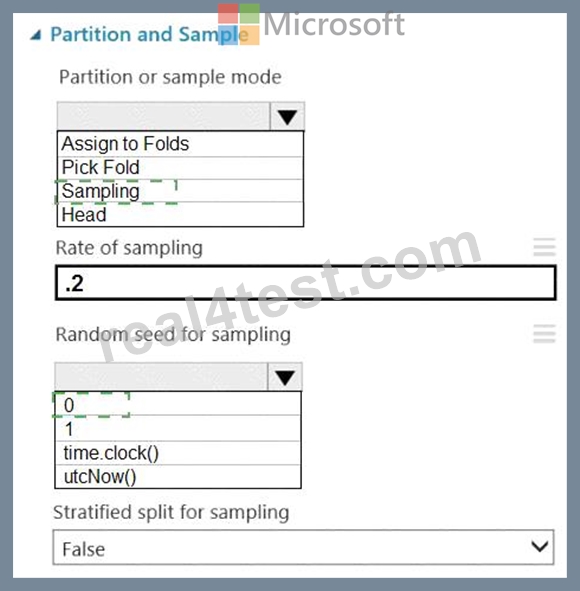
Explanation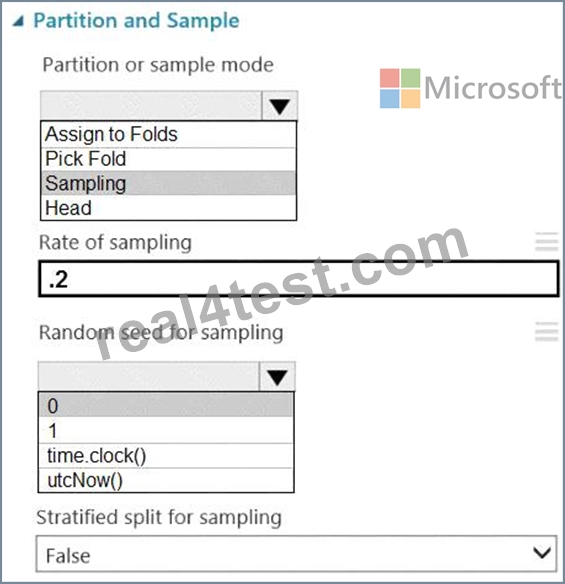
Box 1: Sampling
Create a sample of data
This option supports simple random sampling or stratified random sampling. This is useful if you want to create a smaller representative sample dataset for testing.
1. Add the Partition and Sample module to your experiment in Studio, and connect the dataset.
2. Partition or sample mode: Set this to Sampling.
3. Rate of sampling. See box 2 below.
Box 2: 0
3. Rate of sampling. Random seed for sampling: Optionally, type an integer to use as a seed value.
This option is important if you want the rows to be divided the same way every time. The default value is 0, meaning that a starting seed is generated based on the system clock. This can lead to slightly different results each time you run the experiment.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/partition-and-sample
NEW QUESTION # 123
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are analyzing a numerical dataset which contain missing values in several columns. You must clean the missing values using an appropriate operation without affecting the dimensionality of the feature set.
You need to analyze a full dataset to include all values.
Solution: Use the last Observation Carried Forward (IOCF) method to impute the missing data points.
Does the solution meet the goal?
Answer: B
Explanation:
Instead use the Multiple Imputation by Chained Equations (MICE) method.
Replace using MICE: For each missing value, this option assigns a new value, which is calculated by using a method described in the statistical literature as "Multivariate Imputation using Chained Equations" or "Multiple Imputation by Chained Equations". With a multiple imputation method, each variable with missing data is modeled conditionally using the other variables in the data before filling in the missing values.
Note: Last observation carried forward (LOCF) is a method of imputing missing data in longitudinal studies. If a person drops out of a study before it ends, then his or her last observed score on the dependent variable is used for all subsequent (i.e., missing) observation points.
LOCF is used to maintain the sample size and to reduce the bias caused by the attrition of participants in a study.
References:
https://methods.sagepub.com/reference/encyc-of-research-design/n211.xml
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC3074241/
NEW QUESTION # 124
You are tuning a hyperparameter for an algorithm. The following table shows a data set with different hyperparameter, training error, and validation errors.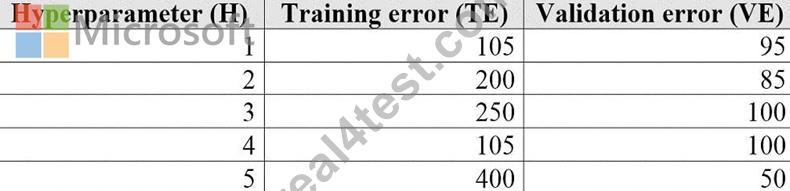
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.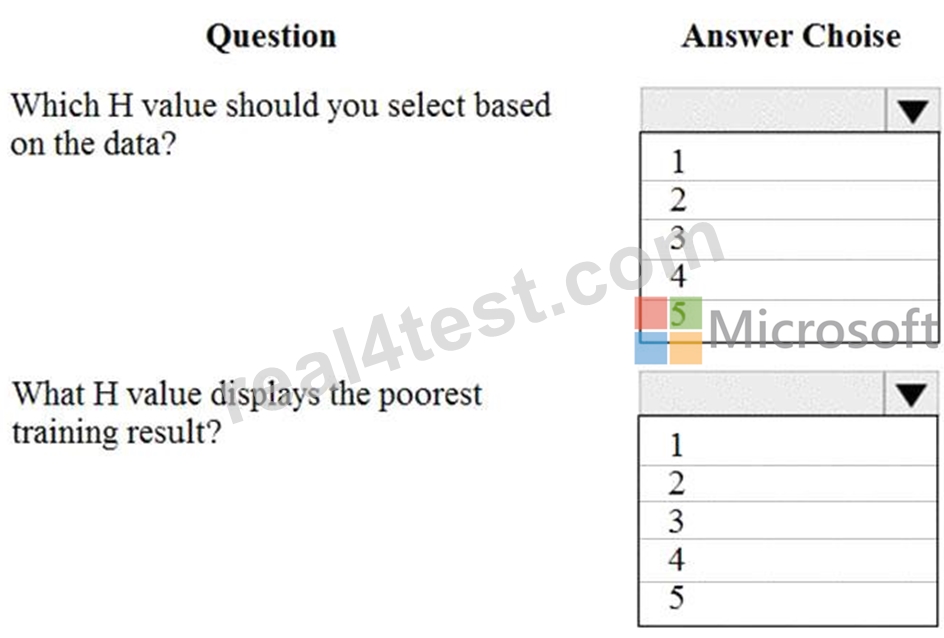
Answer:
Explanation: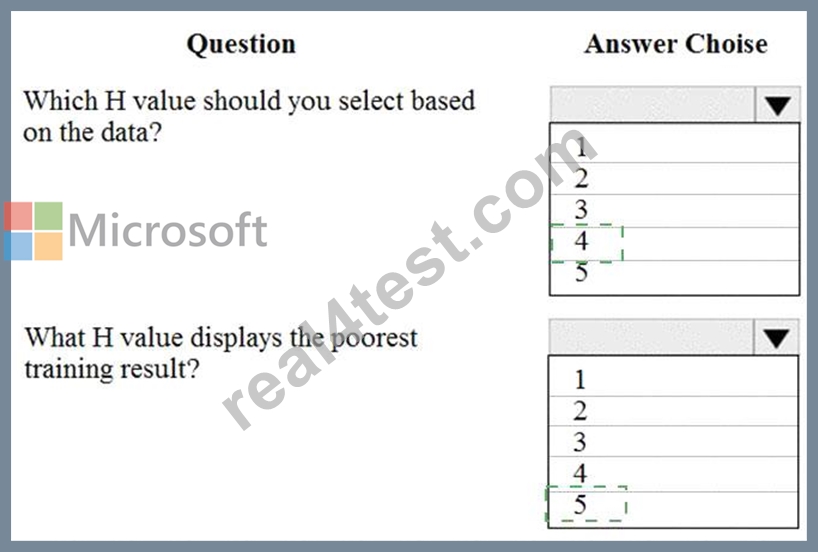
Explanation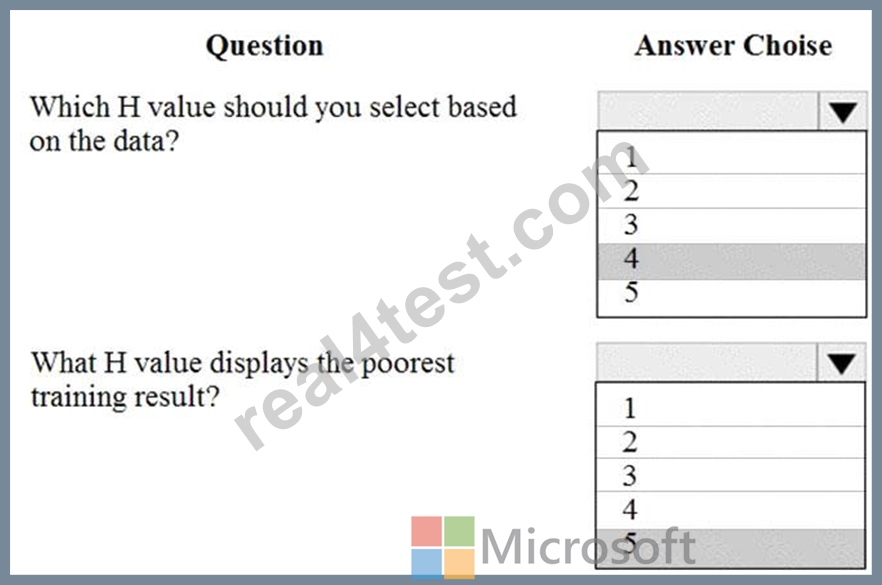
Box 1: 4
Choose the one which has lower training and validation error and also the closest match.
Minimize variance (difference between validation error and train error).
Box 2: 5
Minimize variance (difference between validation error and train error).
Reference:
https://medium.com/comet-ml/organizing-machine-learning-projects-project-management-guidelines-2d2b85651
NEW QUESTION # 125
Drag and Drop Question
You manage an Azure Machine Learning workspace.
You plan to import and wrangle data stored in Azure Data Lake Storage Gen2 with Apache Spark.
You need to start interactive data wrangling with the user identity passthrough.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.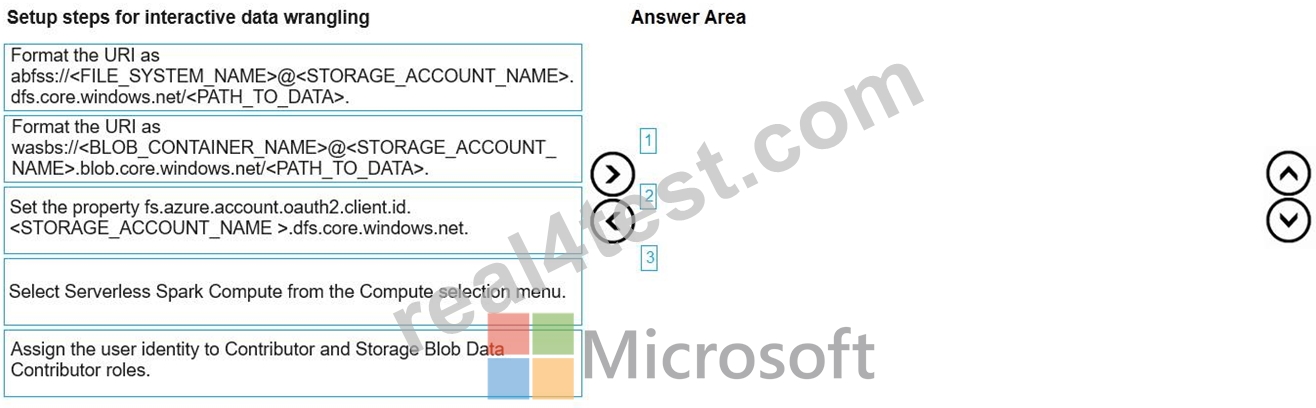
Answer:
Explanation: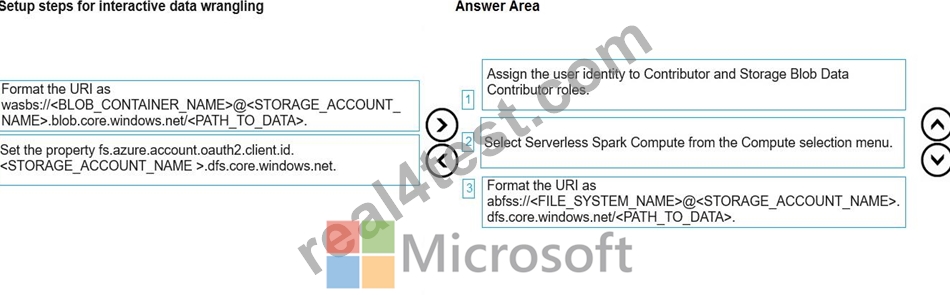
NEW QUESTION # 126
You are using Azure Machine Learning to monitor a trained and deployed model. You implement Event Grid to respond to Azure Machine Learning events.
Model performance has degraded due to model input data changes.
You need to trigger a remediation ML pipeline based on an Azure Machine Learning event.
Which event should you use?
Answer: B
Explanation:
https://learn.microsoft.com/en-
us/dotnet/api/azure.messaging.eventgrid.systemevents.machinelearningservicesdatasetdriftdetec tedeventdata?view=azure-dotnet
NEW QUESTION # 127
......
DP-100 practice test keeps a record of your attempts so you can evaluate and enhance your progress. Our Designing and Implementing a Data Science Solution on Azure (DP-100) practice exams replicate the real Designing and Implementing a Data Science Solution on Azure (DP-100) exam environment so you can eliminate your anxiety. You can access the web-based Designing and Implementing a Data Science Solution on Azure (DP-100) practice exam through browsers. Moreover, operating systems such as Mac, iOS, Android, Windows, and Linux support the online DP-100 practice exam.
DP-100 Practice Test Online: https://www.real4test.com/DP-100_real-exam.html
2026 Latest Real4test DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1HeCvhSWGCqaY2n7405VNywMD0CSIM8Vk