Certified-Data-Engineer-Professional높은통과율덤프샘플문제 & Certified-Data-Engineer-Professional인증덤프샘플체험

Databricks Certified-Data-Engineer-Professional 덤프는Databricks Certified-Data-Engineer-Professional시험문제변경에 따라 주기적으로 업데이트를 진행하여 저희 덤프가 항상 가장 최신버전이도록 보장해드립니다. 고객님들에 대한 깊은 배려의 마음으로 고품질Databricks Certified-Data-Engineer-Professional덤프를 제공해드리고 디테일한 서비스를 제공해드리는것이 저희의 목표입니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Use control flow operators in pipeline components
- 5. Compare streaming tables and materialized views
- 6. Develop unit and integration tests for data processing code
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Use APPLY CHANGES APIs for change data capture
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
>> Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 <<
최근 인기시험 Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 덤프문제
Fast2test의 덤프선택으로Databricks Certified-Data-Engineer-Professional인증시험에 응시한다는 것 즉 성공과 멀지 않았습니다. 여러분의 성공을 빕니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q183-Q188):
질문 # 183
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
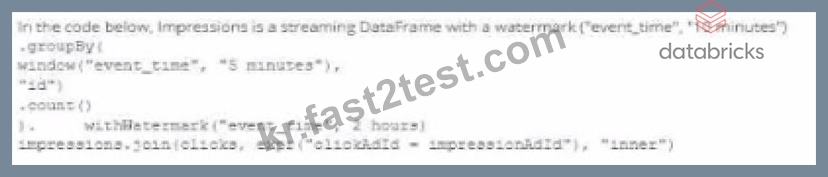
Which solution would improve the performance?
정답:B
설명:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
질문 # 184
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
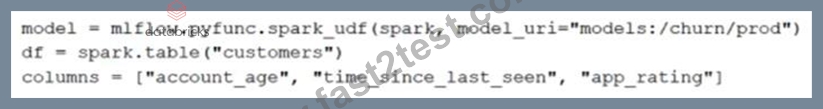
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.apply(model, columns).select("customer_id, predictions")
- B. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- C. df.select("customer_id", model(*columns).alias("predictions"))
- D. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- E. model.predict(df, columns)
정답:C
설명:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
질문 # 185
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- B. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
- C. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
- D. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- E. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
정답:B
질문 # 186
A company has a task management system that tracks the most recent status of tasks. The system takes task events as input and processes events in near real-time using Lakeflow Declarative Pipelines. A new task event is ingested into the system when a task is created or the task status is changed. Lakeflow Declarative Pipelines provides a streaming table (tasks_status) for BI users to query.
The table represents the latest status of all tasks and includes 5 columns:
task_id (unique for each task)
task_name
task_owner
task_status
task_event_time
The table enables three properties: deletion vectors, row tracking, and change data feed (CDF).
A data engineer is asked to create a new Lakeflow Declarative Pipeline to enrich the tasks_status table in near real-time by adding one additional column representing task_owner's department, which can be looked up from a static dimension table (employee).
How should this enrichment be implemented?
- A. Create a new Lakeflow Declarative Pipeline: use the read() function to read tasks_status table; enrich with employee table; store the result in a materialized view.
- B. Create a new Lakeflow Declarative Pipeline: use readStream() function with option readChangeFeed to read tasks_status table CDF; enrich with the employee table; create a new streaming table as the result table and use apply_changes() function to process the changes from the enriched CDF.
- C. Create a new Lakeflow Declarative Pipeline: use the readStream() function with the option skipChangeCommits to read the tasks_status table; enrich with the employee table; store the result in a new streaming table.
- D. Create a new Lakeflow Declarative Pipeline: use the readStream() function to read tasks_status table; enrich with the employee table; store the result in a new streaming table.
정답:B
설명:
Change Data Feed (CDF) allows downstream consumers to read incremental changes (inserts, updates, deletes) from a Delta table. The documentation explains that when streaming from a Delta table with CDF enabled, developers can use readStream().option("readChangeFeed","true") to capture incremental events. For maintaining a derived table with enrichment logic, the recommended practice is to use apply_changes(), which applies CDC semantics (insert/update/delete) correctly to the target streaming table. By joining with the static employee dimension, enriched rows are generated before being merged into the new streaming target. This ensures correctness, scalability, and minimal latency. Batch reads or skipping commits do not maintain correctness for CDC pipelines.
질문 # 187
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
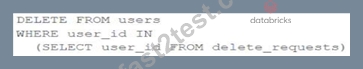
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- B. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- C. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- D. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- E. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
정답:E
설명:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
질문 # 188
......
IT인증시험문제는 수시로 변경됩니다. 이 점을 해결하기 위해Fast2test의Databricks인증 Certified-Data-Engineer-Professional덤프도 시험변경에 따라 업데이트하도록 최선을 다하고 있습니다.시험문제 변경에 초점을 맞추어 업데이트를 진행한후 업데이트된Databricks인증 Certified-Data-Engineer-Professional덤프를 1년간 무료로 업데이트서비스를 드립니다.
Certified-Data-Engineer-Professional인증덤프 샘플체험: https://kr.fast2test.com/Certified-Data-Engineer-Professional-premium-file.html
- Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 시험은 저희 최신덤프로 패스가능 🦟 무료 다운로드를 위해 지금[ www.passtip.net ]에서▷ Certified-Data-Engineer-Professional ◁검색Certified-Data-Engineer-Professional최신 시험기출문제
- Certified-Data-Engineer-Professional퍼펙트 덤프공부자료 ⏸ Certified-Data-Engineer-Professional시험유효자료 🧡 Certified-Data-Engineer-Professional테스트자료 🤿 [ www.itdumpskr.com ]웹사이트에서☀ Certified-Data-Engineer-Professional ️☀️를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional시험유효자료
- 시험패스 가능한 Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 최신버전 덤프 😬 지금➠ www.passtip.net 🠰에서《 Certified-Data-Engineer-Professional 》를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional인기덤프
- Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 시험은 저희 최신덤프로 패스가능 ⚔ 무료로 쉽게 다운로드하려면( www.itdumpskr.com )에서▛ Certified-Data-Engineer-Professional ▟를 검색하세요Certified-Data-Engineer-Professional최신 시험 공부자료
- 최신 Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 인증시험 덤프공부 🍺 ⇛ www.dumptop.com ⇚에서▷ Certified-Data-Engineer-Professional ◁를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional유효한 최신덤프공부
- Certified-Data-Engineer-Professional최신버전 시험대비 공부자료 🤓 Certified-Data-Engineer-Professional최신버전 시험대비 공부자료 🛄 Certified-Data-Engineer-Professional덤프자료 🆔 시험 자료를 무료로 다운로드하려면▷ www.itdumpskr.com ◁을 통해➠ Certified-Data-Engineer-Professional 🠰를 검색하십시오Certified-Data-Engineer-Professional Dumps
- 최신 Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 인증시험 덤프공부 🛅 무료 다운로드를 위해 지금( www.exampassdump.com )에서▷ Certified-Data-Engineer-Professional ◁검색Certified-Data-Engineer-Professional유효한 최신버전 덤프
- Certified-Data-Engineer-Professional높은 통과율 덤프샘플문제 시험은 저희 최신덤프로 패스가능 🔕 시험 자료를 무료로 다운로드하려면⇛ www.itdumpskr.com ⇚을 통해⮆ Certified-Data-Engineer-Professional ⮄를 검색하십시오Certified-Data-Engineer-Professional유효한 최신버전 덤프
- Certified-Data-Engineer-Professional최신버전 시험대비 공부자료 😏 Certified-Data-Engineer-Professional유효한 최신덤프공부 🍏 Certified-Data-Engineer-Professional Dumps 🥄 시험 자료를 무료로 다운로드하려면【 www.koreadumps.com 】을 통해{ Certified-Data-Engineer-Professional }를 검색하십시오Certified-Data-Engineer-Professional테스트자료
- Certified-Data-Engineer-Professional합격보장 가능 덤프문제 🛥 Certified-Data-Engineer-Professional인기자격증 덤프공부자료 🧹 Certified-Data-Engineer-Professional최신버전 시험대비 공부자료 🐹 지금[ www.itdumpskr.com ]에서“ Certified-Data-Engineer-Professional ”를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional Dumps
- Certified-Data-Engineer-Professional인증시험자료 🕶 Certified-Data-Engineer-Professional시험패스 가능 덤프 🪑 Certified-Data-Engineer-Professional최신 시험기출문제 🏏 [ www.pass4test.net ]에서✔ Certified-Data-Engineer-Professional ️✔️를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional시험유효자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes



