The Databricks Databricks-Certified-Professional-Data-Engineer practice tests have customizable time and Databricks-Certified-Professional-Data-Engineer exam questions feature so that the students can set the time and Databricks-Certified-Professional-Data-Engineer exam questions according to their needs. The Databricks Databricks-Certified-Professional-Data-Engineer practice test questions are getting updated on the daily basis and there are also up to 1 year of free updates. Earning the Databricks Databricks-Certified-Professional-Data-Engineer Certification Exam is the way to grow in the modern era with high-paying jobs. The 24/7 support system is available for the customers so that they can get the solution to every problem they face and pass Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam. You can also evaluate the Databricks-Certified-Professional-Data-Engineer prep material with a free demo.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 2: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 3: Monitoring and Alerting | 10% | - Performance and health monitoring - Setting up alerts and notifications - Pipeline observability and logging |
| Topic 4: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Topic 5: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Topic 6: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
| Topic 7: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Topic 8: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching - Cluster configuration and scaling |
| Topic 9: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Topic 10: Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
>> Databricks-Certified-Professional-Data-Engineer Valid Test Blueprint <<
Our Databricks-Certified-Professional-Data-Engineer study quiz are your optimum choices which contain essential know-hows for your information. If you really want to get the certificate successfully, only Databricks-Certified-Professional-Data-Engineer guide materials with intrinsic contents can offer help they are preeminent materials can satisfy your both needs of studying or passing with efficiency. For our Databricks-Certified-Professional-Data-Engineer Exam Braindumps contain the most useful information on the subject and are always the latest according to the efforts of our professionals.
NEW QUESTION # 38
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
df has the following schema: device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT Code block:
df.withWatermark("event_time", "10 minutes")
.groupBy(
________,
"device_id"
)
.agg(
avg("temp").alias("avg_temp"),
avg("humidity").alias("avg_humidity")
)
.writeStream
.format("delta")
.saveAsTable("sensor_avg")
Which line of code correctly fills in the blank within the code block to complete this task?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "window(timeColumn, windowDuration[, slideDuration]) returns a time window for grouping on event-time." Exact extract: "If slideDuration is not specified the windows are non-overlapping (tumbling) with length windowDuration." Exact extract: "Watermarking on the event-time column is required with aggregations to bound state and handle late data."
NEW QUESTION # 39
You were asked to write python code to stop all running streams, which of the following command can be used to get a list of all active streams currently running so we can stop them, fill in the blank.
1.for s in _______________:
2. s.stop()
Answer: A
NEW QUESTION # 40
The marketing team is launching a new campaign to monitor the performance of the new campaign for the first two weeks, they would like to set up a dashboard with a refresh schedule to run every 5 minutes, which of the below steps can be taken to reduce of the cost of this refresh over time?
Answer: B
Explanation:
Explanation
The answer is Setup the dashboard refresh schedule to end in two weeks
NEW QUESTION # 41
Which of the following scenarios is the best fit for the AUTO LOADER solution?
Answer: B
Explanation:
Explanation
The answer is, Efficiently process new data incrementally from cloud object storage.
Please note: AUTO LOADER only works on data/files located in cloud object storage like S3 or Azure Blob Storage it does not have the ability to read other data sources, although AU-TO LOADER is built on top of structured streaming it only supports files in the cloud object stor-age. If you want to use Apache Kafka then you can just use structured streaming.
Diagram Description automatically generated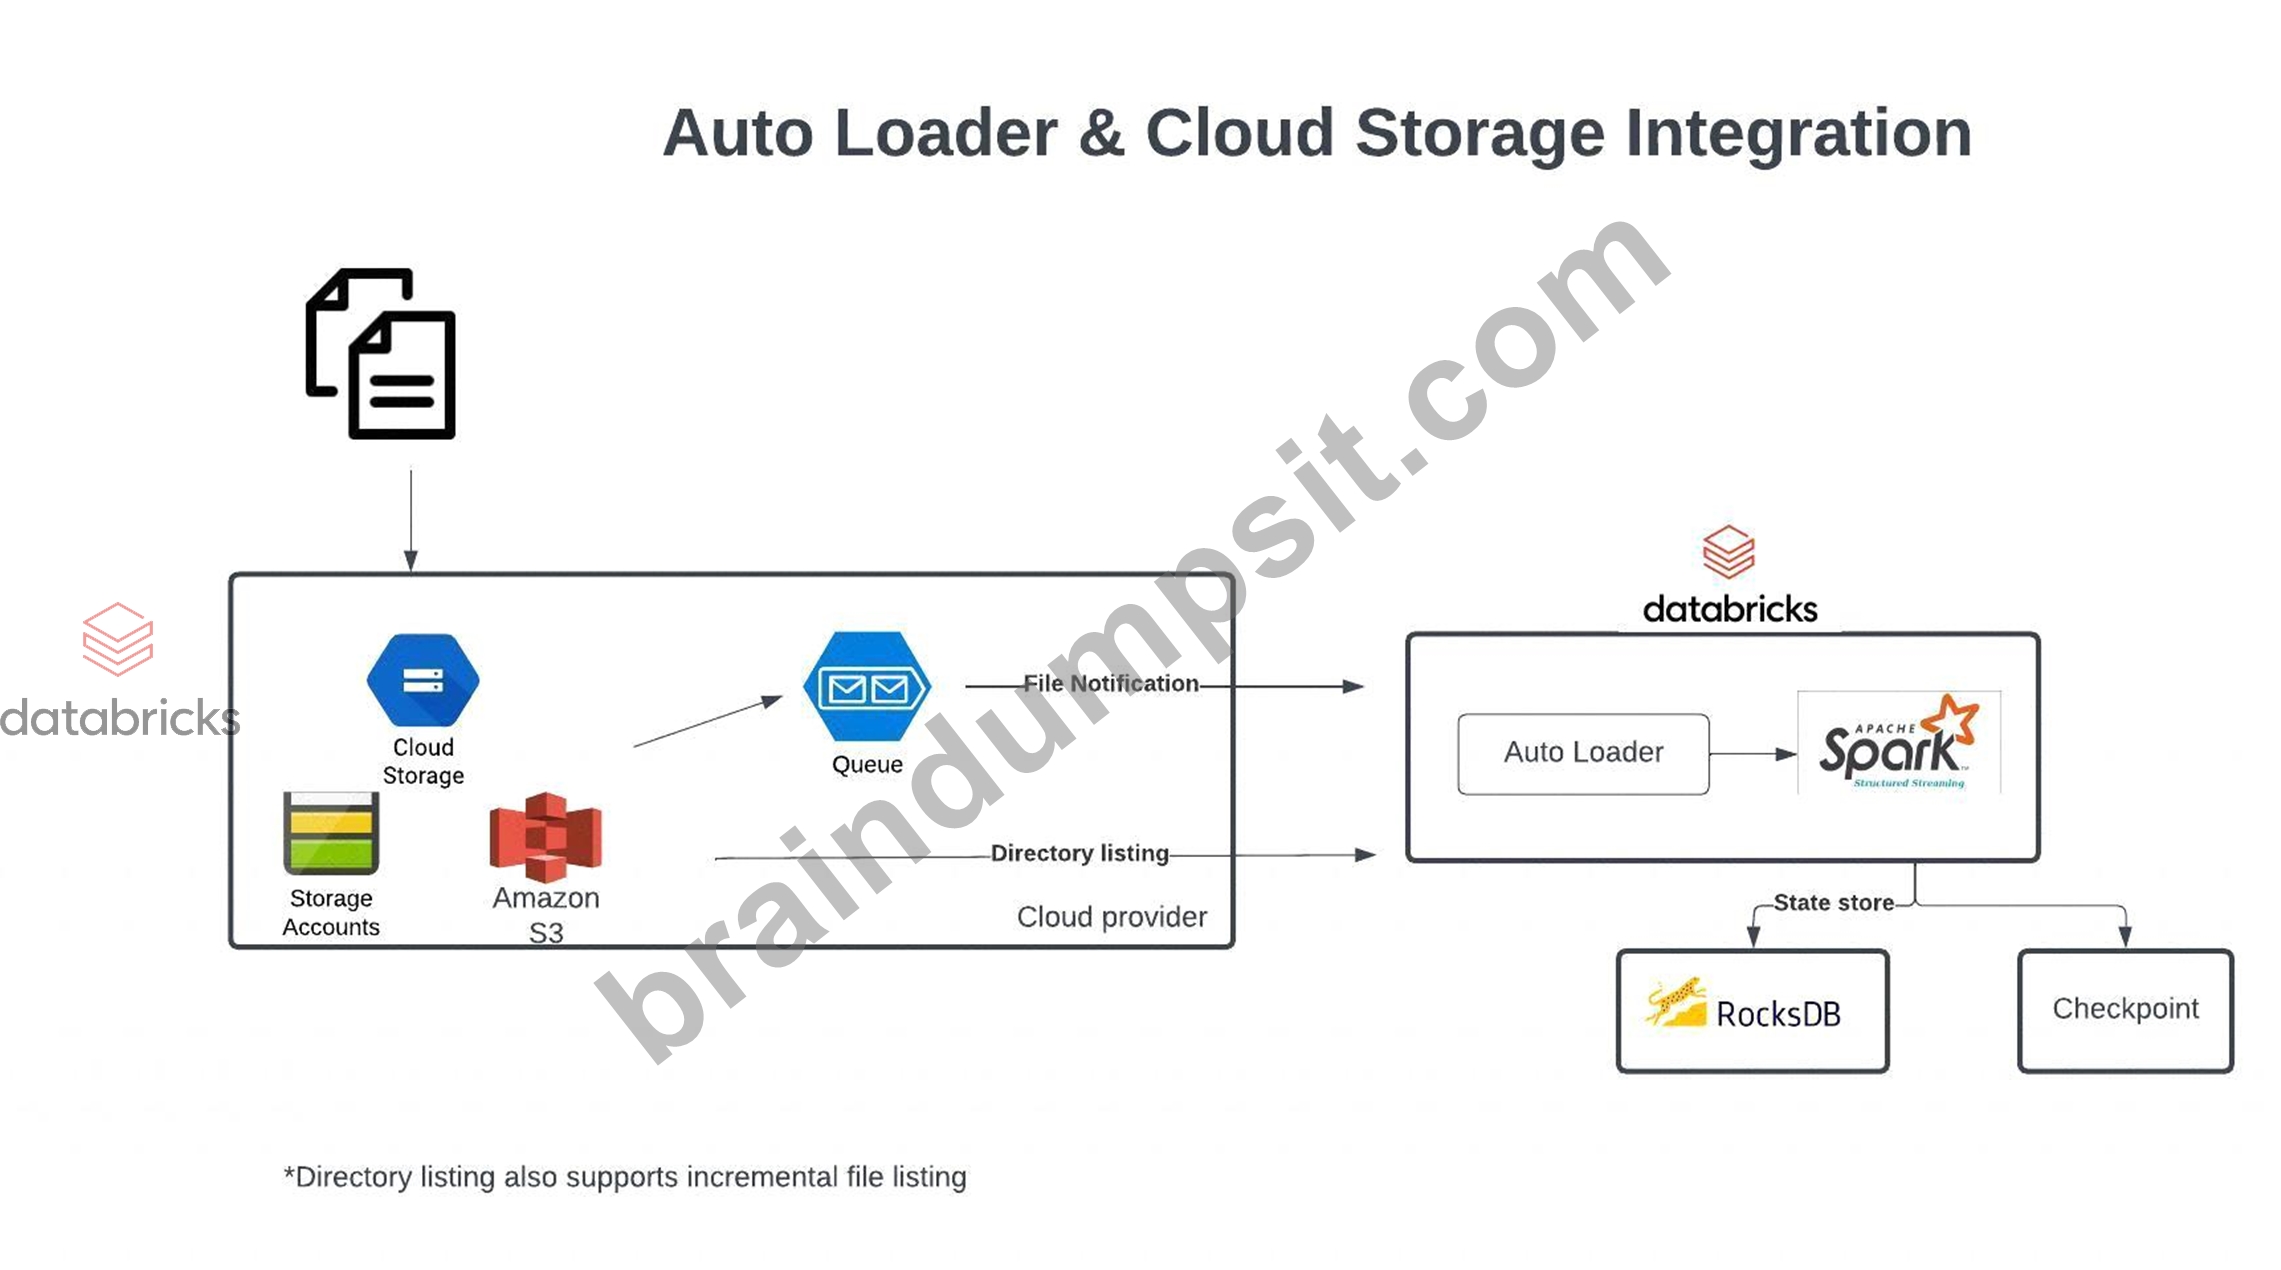
Auto Loader and Cloud Storage Integration
Auto Loader supports a couple of ways to ingest data incrementally
1.Directory listing - List Directory and maintain the state in RocksDB, supports incremental file listing
2.File notification - Uses a trigger+queue to store the file notification which can be later used to retrieve the file, unlike Directory listing File notification can scale up to millions of files per day.
[OPTIONAL]
Auto Loader vs COPY INTO?
Auto Loader
Auto Loader incrementally and efficiently processes new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a new Structured Streaming source called cloudFiles. Given an input directory path on the cloud file storage, the cloudFiles source automatically processes new files as they arrive, with the option of also processing existing files in that directory.
When to use Auto Loader instead of the COPY INTO?
*You want to load data from a file location that contains files in the order of millions or higher. Auto Loader can discover files more efficiently than the COPY INTO SQL command and can split file processing into multiple batches.
*You do not plan to load subsets of previously uploaded files. With Auto Loader, it can be more difficult to reprocess subsets of files. However, you can use the COPY INTO SQL command to reload subsets of files while an Auto Loader stream is simultaneously running.
Refer to more documentation here,
https://docs.microsoft.com/en-us/azure/databricks/ingestion/auto-loader
NEW QUESTION # 42
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
An analyze who is not a member of the auditing group executing the following query:
Which result will be returned by this query?
Answer: A
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 43
......
As this new frontier of personalizing the online experience advances, our Databricks-Certified-Professional-Data-Engineer exam guide is equipped with comprehensive after-sale online services. And we have customer service people 24 hours online to deal with your difficulties on our Databricks-Certified-Professional-Data-Engineer exam questions. If you have any question or request for further assistance about the Databricks-Certified-Professional-Data-Engineer study braindumps, you can leave us a message on the web page or email us. All in all, we take an approach to this market by prioritizing the customers first, and we believe the customer-focused vision will help our Databricks-Certified-Professional-Data-Engineer test guide’ growth.
Databricks-Certified-Professional-Data-Engineer Reliable Exam Topics: https://www.braindumpsit.com/Databricks-Certified-Professional-Data-Engineer_real-exam.html