Latest Study DY0-001 Questions, Pdf Demo DY0-001 Download

P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by Actual4test: https://drive.google.com/open?id=1HI6Xh6HMxmmab_fxIW4z2IaNeCKeukj3
They can try a free demo for satisfaction before buying our CompTIA DY0-001 dumps. And a 24/7 support system assists them whenever they are stuck in any problem or issue. This CompTIA DataAI Certification Exam (DY0-001) questions is a complete package and a blessing for candidates who want to prepare quickly for the DY0-001 exam. Buy It Now!
CompTIA DY0-001 Exam Overview:
>> Latest Study DY0-001 Questions <<
Pdf Demo DY0-001 Download - DY0-001 Reliable Test Duration
In your day-to-day life, things look like same all the time. Sometimes you feel the life is so tired, do the same things again and again every day. Doing the same things and living on the same life make you very bored. So hurry to prepare for DY0-001 Exam, we believe that the DY0-001 exam will help you change your present life. It is possible for you to start your new and meaningful life in the near future, if you can pass the DY0-001 exam and get the certification.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 4 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| Topic 5 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
CompTIA DataAI Certification Exam Sample Questions (Q71-Q76):
NEW QUESTION # 71
A data scientist is analyzing a data set with categorical features and would like to make those features more useful when building a model. Which of the following data transformation techniques should the data scientist use? (Choose two.)
- A. Linearization
- B. Pivoting
- C. Scaling
- D. One-hot encoding
- E. Normalization
- F. Label encoding
Answer: D,F
NEW QUESTION # 72
A data scientist wants to predict a person's travel destination. The options are:
Which of the following models would best fit this use case?
- A. k-means modeling
- B. Principal component analysis
- C. Latent semantic analysis
- D. Linear discriminant analysis
Answer: D
Explanation:
You need a supervised multiclass classification model to predict one of the four labeled destinations. Linear Discriminant Analysis is designed for such tasks, finding the linear boundaries that best separate the known destination classes.
NEW QUESTION # 73
Which of the following measures would a data scientist most likely use to calculate the similarity of two text strings?
- A. Word cloud
- B. k-nearest neighbors
- C. String indexing
- D. Edit distance
Answer: D
Explanation:
# Edit distance (also known as Levenshtein distance) measures how many single-character edits (insertions, deletions, or substitutions) are needed to transform one string into another. It's a common metric for assessing string similarity, especially in natural language processing (NLP) tasks.
Why the other options are incorrect:
* A: Word clouds visualize word frequency, not similarity.
* C: String indexing is a method for referencing string positions, not comparison.
* D: k-NN is a classification algorithm, not a string similarity measure.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 6.3:"Edit distance is a key similarity metric in text comparison tasks, particularly in cleaning or matching string records."
-
NEW QUESTION # 74
The following graphic shows the results of an unsupervised, machine-learning clustering model:
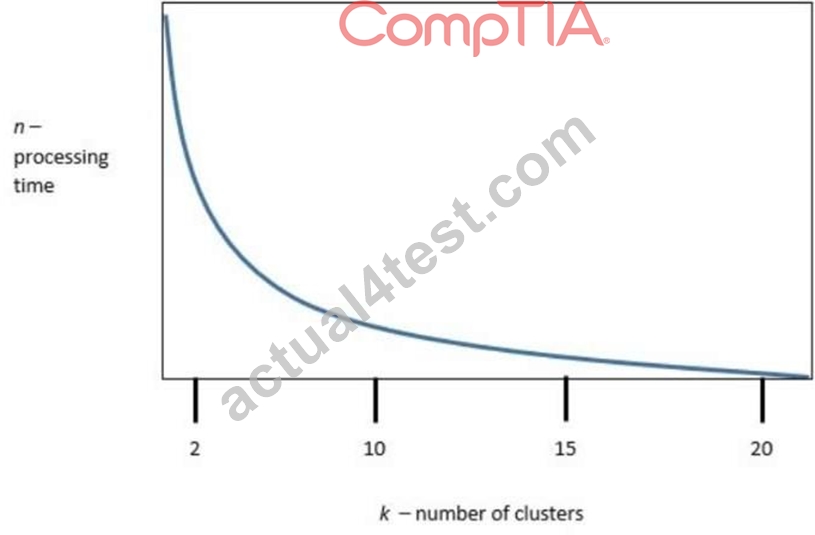
k is the number of clusters, and n is the processing time required to run the model. Which of the following is the best value of k to optimize both accuracy and processing requirements?
Answer: B
Explanation:
The curve shows a steep drop in processing time up to about k = 10, after which gains in speed taper off. Choosing 10 clusters balances sufficient model complexity with reasonable computational cost.
NEW QUESTION # 75
Which of the following is best solved with graph theory?
- A. Traveling salesman
- B. One-armed bandit
- C. Fraud detection
- D. Optical character recognition
Answer: A
Explanation:
The traveling-salesman problem is a prototypical graph theory challenge, finding the shortest tour through a graph's nodes, whereas the other tasks rely on different domains (OCR on image processing, fraud detection often on statistical/anomaly methods, bandit problems on sequential decision theory).
NEW QUESTION # 76
......
Pdf Demo DY0-001 Download: https://www.actual4test.com/DY0-001_examcollection.html
- DY0-001 Visual Cert Test 🦩 Study DY0-001 Group 🛑 Study DY0-001 Group 🐡 Download [ DY0-001 ] for free by simply entering ➤ www.prepawaypdf.com ⮘ website 🍼High DY0-001 Quality
- High DY0-001 Quality 🦧 DY0-001 Authentic Exam Questions 🚢 Frequent DY0-001 Updates 🚺 Open ➡ www.pdfvce.com ️⬅️ enter ➤ DY0-001 ⮘ and obtain a free download 🥪DY0-001 Reliable Exam Preparation
- DY0-001 Authentic Exam Questions 🤷 DY0-001 Advanced Testing Engine 🦘 Exam DY0-001 Book 🔍 Open ➤ www.verifieddumps.com ⮘ and search for ➽ DY0-001 🢪 to download exam materials for free 🥱Study DY0-001 Group
- Reliable Latest Study DY0-001 Questions - Accurate Pdf Demo DY0-001 Download - Efficient DY0-001 Reliable Test Duration 💓 The page for free download of 【 DY0-001 】 on 「 www.pdfvce.com 」 will open immediately 💕Frequent DY0-001 Updates
- Study DY0-001 Group 🤩 Exam DY0-001 Torrent ➡️ DY0-001 Reliable Exam Preparation 🥰 Open ➠ www.testkingpass.com 🠰 and search for ➥ DY0-001 🡄 to download exam materials for free 🐱Exam DY0-001 Torrent
- 2026 Latest Study DY0-001 Questions - CompTIA DataAI Certification Exam Unparalleled Pdf Demo Download 🛤 Search for ✔ DY0-001 ️✔️ and obtain a free download on 《 www.pdfvce.com 》 🐶Exam DY0-001 Torrent
- Valid Test DY0-001 Vce Free ✳ Exam DY0-001 Book ⛴ DY0-001 Reliable Exam Preparation 🙁 Search on ➥ www.validtorrent.com 🡄 for ▷ DY0-001 ◁ to obtain exam materials for free download 💉New DY0-001 Practice Questions
- 2026 Latest Study DY0-001 Questions | Pass-Sure 100% Free Pdf Demo DY0-001 Download 📜 Simply search for ➥ DY0-001 🡄 for free download on ▷ www.pdfvce.com ◁ ⭐Exam DY0-001 Torrent
- Latest Updated Latest Study DY0-001 Questions - Leader in Qualification Exams - Free PDF CompTIA CompTIA DataAI Certification Exam 🏩 Download { DY0-001 } for free by simply entering 「 www.troytecdumps.com 」 website 💡Exam Questions DY0-001 Vce
- Trusted DY0-001 Exam Resource 💏 Valid Test DY0-001 Vce Free 🕸 Exam Questions DY0-001 Vce 📂 Enter [ www.pdfvce.com ] and search for ⮆ DY0-001 ⮄ to download for free 🤺High DY0-001 Quality
- 100% Pass CompTIA - DY0-001 - High-quality Latest Study CompTIA DataAI Certification Exam Questions 🎵 [ www.practicevce.com ] is best website to obtain 「 DY0-001 」 for free download 🌑New DY0-001 Practice Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that Actual4test DY0-001 dumps now are free: https://drive.google.com/open?id=1HI6Xh6HMxmmab_fxIW4z2IaNeCKeukj3