P.S. Free & New DP-600 dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=1gqvR8slIEll22-dujOtv2xzTQUrTeG_4
The advantages of our DP-600 cram guide is plenty and the price is absolutely reasonable. The clients can not only download and try out our products freely before you buy them but also enjoy the free update and online customer service at any time during one day. The clients can use the practice software to test if they have mastered the DP-600 Test Guide and use the function of stimulating the test to improve their performances in the real test. So our products are absolutely your first choice to prepare for the test DP-600 certification.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Interactive DP-600 Course <<
You plan to place an order for our Microsoft DP-600 test questions answers; you should have a credit card. Mostly we just support credit card. If you just have debit card, you should apply a credit card or you can ask other friend to help you pay for DP-600 test questions answers. Normally we suggest candidates to pay by PayPal, here it is no need for you to have a PayPal account. When you click PayPal it will transfer to credit card payment. If you choose SWREG payment for DP-600 Test Questions Answers, it will have extra tax for some countries.
NEW QUESTION # 168
You have a Fabric workspace named Workspace1 that contains a KQL database The database contains a table named Table1. Workspace1 is allocated to an F 128 capacity. Table1 contains 10 billion rows and 25 columns named d through c25. Column cl contains identifiers that range from 1 to 15 and are equally distributed.
You have the following query.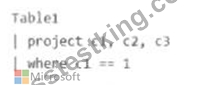
You modify the query as shown.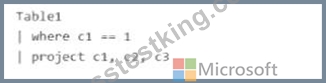
How will the execution time of the query be affected?
Answer: B
NEW QUESTION # 169
You are implementing a medallion architecture in a single Fabric workspace.
You have a lakehouse that contains the Bronze and Silver layers and a warehouse that contains the Gold layer.
You create the items required to populate the layers as shown in the following table.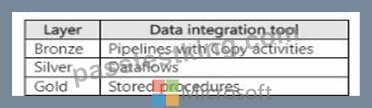
You need to ensure that the layers are populated daily in sequential order such that Silver is populated only after Bronze is complete, and Gold is populated only after Silver is complete. The solution must minimize development effort and complexity.
What should you use to execute each set of items? To answer, drag the appropriate options to the correct items. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.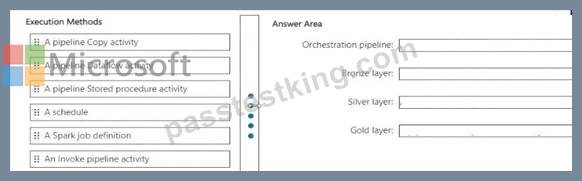
Answer:
Explanation: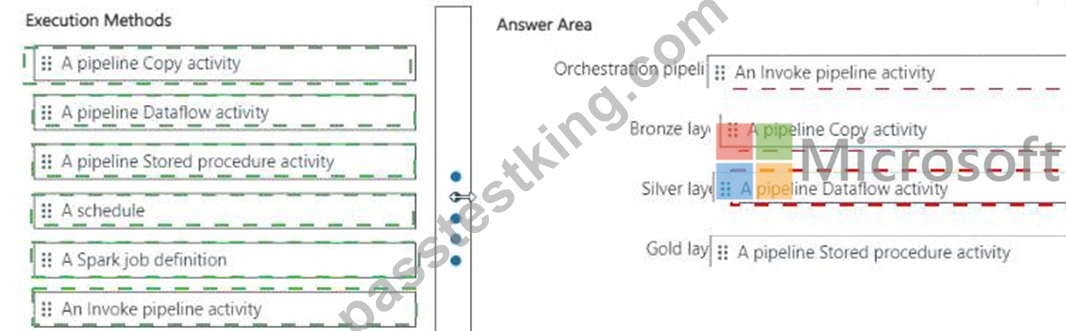
Explanation:
To execute each set of items in sequential order with minimized development effort and complexity, you should use the following options:
* Orchestration pipeline: Use a pipeline with an Invoke pipeline activity. This allows for orchestrating and scheduling the execution of other pipelines, ensuring they run in the correct sequence.
* Bronze layer: Implement a pipeline Copy activity. This aligns with the table indicating that the Bronze layer uses pipelines with Copy activities for data integration.
* Silver layer: Implement a pipeline Dataflow activity. The table specifies that Dataflows are used for the Silver layer.
* Gold layer: Implement a pipeline Stored procedure activity. Stored procedures are specified for the Gold layer according to the table.
NEW QUESTION # 170
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.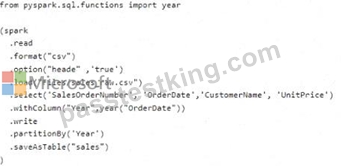
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.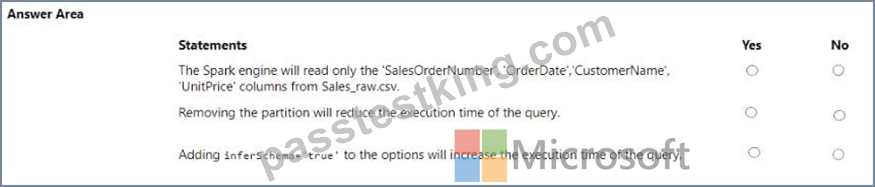
Answer:
Explanation: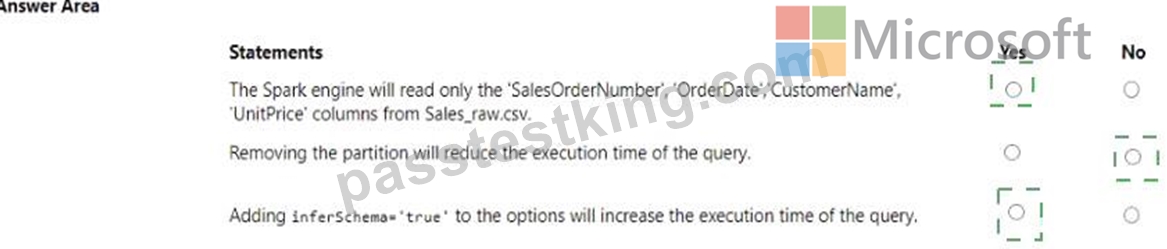
Explanation: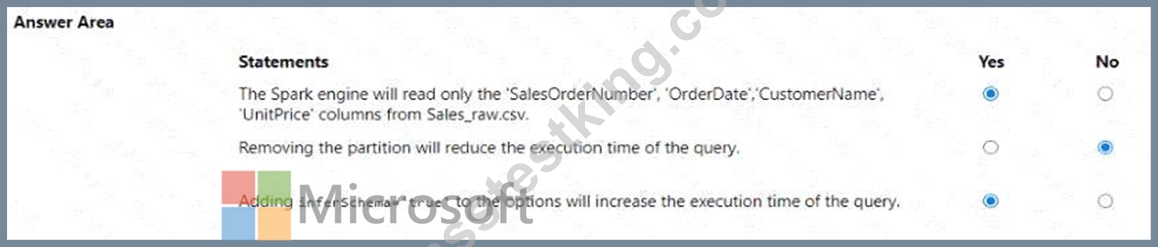
* The Spark engine will read only the 'SalesOrderNumber', 'OrderDate', 'CustomerName', 'UnitPrice' columns from Sales_raw.csv. - Yes
* Removing the partition will reduce the execution time of the query. - No
* Adding inferSchema='true' to the options will increase the execution time of the query. - Yes The code specifies the selection of certain columns, which means only those columns will be read into the DataFrame. Partitions in Spark are a way to optimize the execution of queries by organizing the data into parts that can be processed in parallel. Removing the partition could potentially increase the execution time because Spark would no longer be able to process the data in parallel efficiently. The inferSchema option allows Spark to automatically detect the column data types, which can increase the execution time of the initial read operation because it requires Spark to read through the data to infer the schema.
NEW QUESTION # 171
You need to provide Power Bl developers with access to the pipeline. The solution must meet the following requirements:
* Ensure that the developers can deploy items to the workspaces for Development and Test.
* Prevent the developers from deploying items to the workspace for Production.
* Follow the principle of least privilege.
Which three levels of access should you assign to the developers? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
Answer: B,E,F
Explanation:
To meet the requirements, developers should have Admin access to the deployment pipeline (B), Contributor access to the Development and Test workspaces (E), and Viewer access to the Production workspace (D).
This setup ensures they can perform necessary actions in development and test environments without having the ability to affect production. References = The Power BI documentation on workspace access levels and deployment pipelines provides guidelines on assigning appropriate permissions.
NEW QUESTION # 172
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.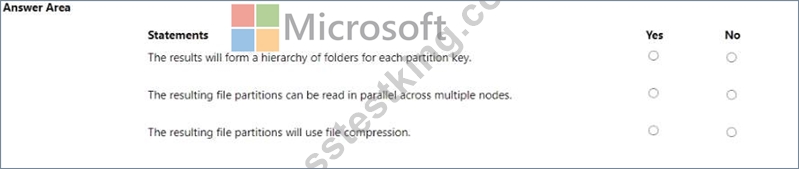
Answer:
Explanation: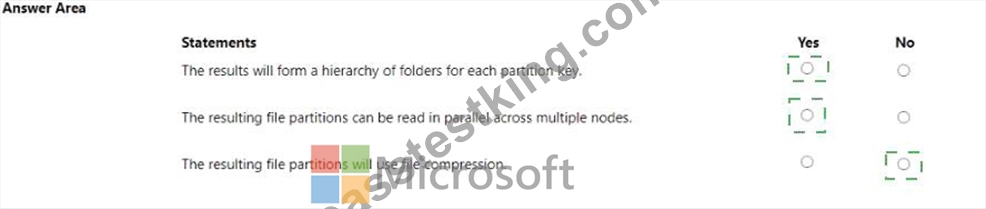
Explanation:
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
NEW QUESTION # 173
......
There are great and plenty benefits after the clients pass the DP-600 test. Because the knowledge that our DP-600 exam practice materials provides is conducive to enhancing the client' practical working abilities and stocks of knowledge, the clients will be easier to increase their wages and be promoted by their boss. Besides, they will be respected by their colleagues, friends and family members and be recognized as the elites among the industry. They will acquire more access to work abroad for further studies. So the clients must appreciate our DP-600 study question after they pass the test.
Study DP-600 Demo: https://www.passtestking.com/Microsoft/DP-600-practice-exam-dumps.html
BONUS!!! Download part of PassTestking DP-600 dumps for free: https://drive.google.com/open?id=1gqvR8slIEll22-dujOtv2xzTQUrTeG_4