BTW, DOWNLOAD part of PassExamDumps NCP-BC-7.5 dumps from Cloud Storage: https://drive.google.com/open?id=1lHADhoxNOo7Zszy-WmTU52SMYTMNr9vd
You will have the chance to renew your knowledge while getting trustworthy proof of your expertise with the Nutanix NCP-BC-7.5 exam. After passing the Nutanix NCP-BC-7.5 certification exam, you can take advantage of a number of extra benefits. The Nutanix NCP-BC-7.5 Certification test, however, is a valuable and difficult credential. But with the correct concentration, commitment, and NCP-BC-7.5 exam preparation, you could ace this test with ease.
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Replication Types (Sync/Async) - Nutanix Leap Overview - Protection Domains |
| Topic 2: Recovery Operations | - Failover and Failback Procedures - Test Recovery Workflows - Recovery Plans and Orchestration |
| Topic 3: Disaster Recovery Fundamentals | - DR Concepts (RPO, RTO, SLAs) - Business Continuity Principles |
| Topic 4: Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Topic 5: Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
>> NCP-BC-7.5 Test Preparation <<
Now it is wise choice for you to choose our NCP-BC-7.5 actual test guide materials. Valid exam questions help you study and prepare double results with half works. You will get high-quality 100% pass rate NCP-BC-7.5 learning prep so that you can master the key knowledge and clear exam easily. You can Pass NCP-BC-7.5 Exam in the shortest time and obtain a certification soon. It will benefit you more. Instead of admiring others' redoubtable life, start your new life from choosing valid test dumps. Our NCP-BC-7.5 actual test guide is the pass king in this field which will be the best option for you.
NEW QUESTION # 111
Refer to Exhibit: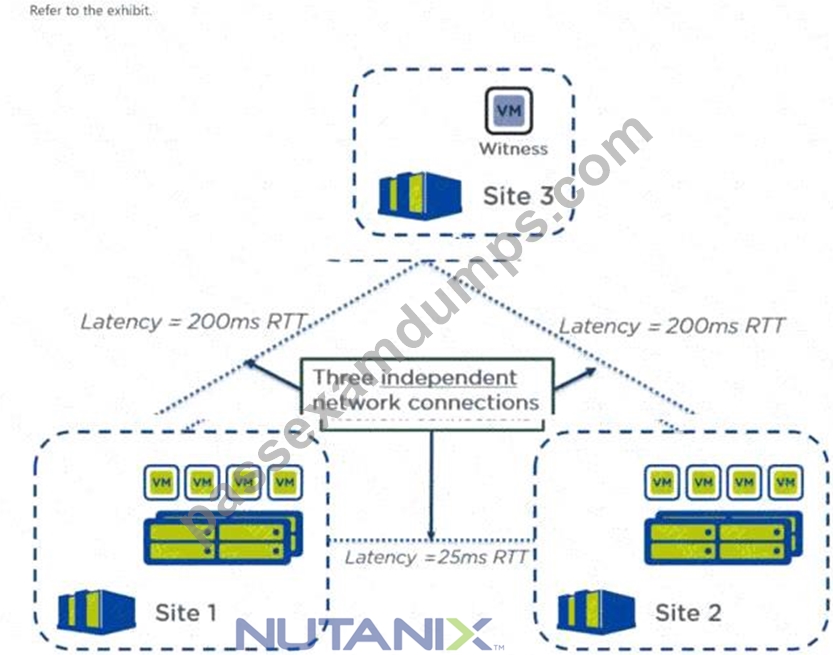
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
Answer: C
Explanation:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
NEW QUESTION # 112
Two AHV clusters are 4 ms RTT apart. The business requires:
* 0 RPO
* Automatic failover
* No application performance degradation
* Hybrid HCI nodes with 100 TB capacity
What storage configuration must be validated before enabling synchronous replication?
Answer: D
Explanation:
Synchronous replication is a high-performance disaster recovery solution designed to provide a Zero Recovery Point Objective (RPO) by mirroring every write operation in real-time between two clusters.
Because the system must wait for the remote site to acknowledge every write before confirming the operation to the application, the underlying storage media must be capable of extremely low-latency I/O.
On hybrid clusters that utilize both Solid State Drives (SSDs) and Hard Disk Drives (HDDs), Nutanix mandates a minimum of one SSD per node to support synchronous replication. The SSD tier is used to store metadata and provide the high-speed " Oplog " where incoming writes are initially landed before being drained to the HDD tier. If a cluster were to attempt synchronous replication using only HDDs (Option D), the mechanical latency of the spinning disks combined with the network Round Trip Time (RTT) would cause severe application performance degradation, failing the business requirement. Even though the cluster has large capacity requirements (100 TB), the presence of an SSD tier is a technical prerequisite for the software to even enable the synchronous consistency feature. Therefore, ensuring at least one SSD exists in every node of the hybrid cluster is the critical storage validation step required before implementation.
NEW QUESTION # 113
An organization is finalizing its Disaster Recovery (DR) plan. The primary objective is to balance cost- efficiency with a target RTO of under 15 minutes. Data currently resides in Object Storage, but the team is debating between a Zero Compute approach and a Pilot Light approach. Why would a Pilot Light infrastructure be selected over a Zero Compute model despite the higher " Moderate " cost?
Answer: C
Explanation:
When designing disaster recovery to a cloud environment (such as NC2 on AWS or Azure), organizations must choose a compute model that aligns with their Recovery Time Objective (RTO). The " Zero Compute " model is the most cost-efficient because it stores only the data (snapshots) in low-cost Object Storage (S3 or Blob) and does not maintain a running cluster. However, the RTO for Zero Compute is high because, in a disaster, the organization must first deploy a new Nutanix cluster, configure it, and then begin the process of hydrating data from the Object Storage.
In contrast, the " Pilot Light " model involves keeping a minimal, active Nutanix cluster (e.g., 3 nodes) running at the recovery site. While this carries a moderate ongoing cost, it significantly reduces the RTO.
Because the cluster already exists, the management plane (Prism Central), the storage containers, and all metadata are already active. When a failover is triggered, the system only needs to power on the VMs or perform a small amount of data hydration. This allows the organization to meet aggressive RTO targets of under 15 minutes, which is generally impossible with the Zero Compute model. Pilot Light provides the " ready-to-go " infrastructure needed for mission-critical applications that cannot afford the multiple hours required to provision a fresh cluster from scratch during an emergency.
NEW QUESTION # 114
The Disaster Recovery dashboard in Prism Central shows that the protection domain is out of sync and new recovery points are no longer being created at the recovery site. No recent changes were made to the protection policy configuration or RPO settings. During initial troubleshooting, an administrator has observed the following:
* Production VMs are running normally at the primary site.
* The recovery cluster is reachable from Prism Central.
* No storage capacity alerts are seen on either cluster.
* A recent network change was implemented to enable network segmentation between clusters.
* New firewall rules were introduced recently as part of a security hardening effort.
Which action should the administrator take first when evaluating this issue?
Answer: B
Explanation:
Network segmentation is a powerful Nutanix feature used to isolate replication and storage traffic from standard management traffic. However, implementing this in a " brownfield " environment-where replication is already active-requires careful coordination. In this scenario, the replication failure coincides with the implementation of network segmentation and new firewall rules. The administrator ' s first action must be to verify if segmentation was enabled while replication was actively running. If segmentation is enabled on one site without a matching configuration on the remote cluster, or if the services (Cerebro
/Stargate) were not properly restarted to bind to the new interfaces, the replication stream will " hang " .
Furthermore, enabling segmentation changes the source and destination IP addresses used for replication traffic. If these new segmented IP addresses were not whitelisted in the recent firewall hardening effort, all " Snapshot-on-wire " traffic will be dropped. By verifying the segmentation state first, the administrator can determine if the network plumbing is consistent across both sites. Recreating policies (Option A) or triggering failover (Option C) would not resolve an underlying network isolation issue and would likely result in further failures until the segmentation and firewall rules are properly aligned.
NEW QUESTION # 115
A financial institution is designing a disaster recovery solution for a business-critical application that requires a zero recovery point objective (RPO). The infrastructure team decides to implement Nutanix Metro Availability between two physical data centers (DC-Alpha and DC-Beta) interconnected by a dedicated dark fiber. What is the maximum possible network latency on this link for this configuration to function correctly?
Answer: C
Explanation:
Nutanix Metro Availability is a continuous availability solution designed to survive a site failure with zero data loss (Zero RPO). Because it operates on a synchronous replication model, every write performed by a virtual machine must be acknowledged by both the local and the remote clusters before the write is confirmed to the application. This process introduces a " latency penalty " equal to the network Round Trip Time (RTT) between the sites.
To maintain acceptable application performance and ensure cluster stability, Nutanix enforces a strict latency limit of 5 ms RTT between the primary and secondary clusters. If the latency exceeds this 5 ms threshold, the time spent waiting for remote acknowledgments would cause severe performance degradation for high-I/O workloads, such as the SQL or Oracle databases common in financial institutions. Furthermore, high latency increases the risk of the synchronous link being " broken " during periods of high data churn. While the Witness VM (used for tie-breaking) can tolerate much higher latency (up to 200 ms), the data-path link must remain under 5 ms to satisfy the technical requirements of the Metro Availability feature and the performance expectations of Tier-1 business-critical applications.
NEW QUESTION # 116
......
These Nutanix NCP-BC-7.5 Exam questions help you practice theoretical and practical skills in different aspects, making problem-solving easier. Our Nutanix NCP-BC-7.5 questions PDF is a complete bundle of problems presenting the versatility and correlativity of questions observed in past exam papers. These questions are bundled into Nutanix NCP-BC-7.5 PDF Questions following the official study guide.
Trustworthy NCP-BC-7.5 Exam Torrent: https://www.passexamdumps.com/NCP-BC-7.5-valid-exam-dumps.html
BTW, DOWNLOAD part of PassExamDumps NCP-BC-7.5 dumps from Cloud Storage: https://drive.google.com/open?id=1lHADhoxNOo7Zszy-WmTU52SMYTMNr9vd