DOWNLOAD the newest Itbraindumps DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BL92sNKjhMfJT_wdcwzSqwIO3BODexzp
Our to-the-point and trustworthy Microsoft DP-800 Exam Questions in three formats for the Microsoft DP-800 certification exam will surely assist you to qualify for Developing AI-Enabled Database Solutions certification. Do not underestimate the value of our Microsoft DP-800 Exam Dumps because it is the make-or-break point of your career.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Available Languages: | English |
| Exam Format: | Multiple choice, Case studies |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
Once you have practiced and experienced the quality of our DP-800 exam preparation, you will remember the serviceability and usefulness of them. For the excellent quality of our DP-800 training questions explains why our DP-800 practice materials helped over 98 percent of exam candidates get the certificate you dream of successfully. Believe me with our DP-800 Guide quiz, you will be more confident to pass the exam in the shortest time with ease.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 43
Which SQL feature is commonly used to integrate AI-generated insights?
Answer: D
Explanation:
AI models (like OpenAI) are typically accessed via APIs, which SQL apps call externally.
NEW QUESTION # 44
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: B
Explanation:
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content , not simple categorical, numeric, or location-only values. Microsoft's DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings , generating embeddings , and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches.
In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location . Those are descriptive context elements that are typically captured in a free- text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search , semantic search , and RAG retrieval . Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items.
The other options are weaker choices:
* vehicleLocation is too narrow and usually better handled with geospatial filtering , not embeddings.
* incidentType is likely categorical and too low in semantic richness.
* SeverityScore is numeric and not appropriate as the primary source for semantic embeddings.
Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding.
But among the options given, the best and most exam-aligned answer is the textual narrative column :
incidentDescrlption .
NEW QUESTION # 45
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.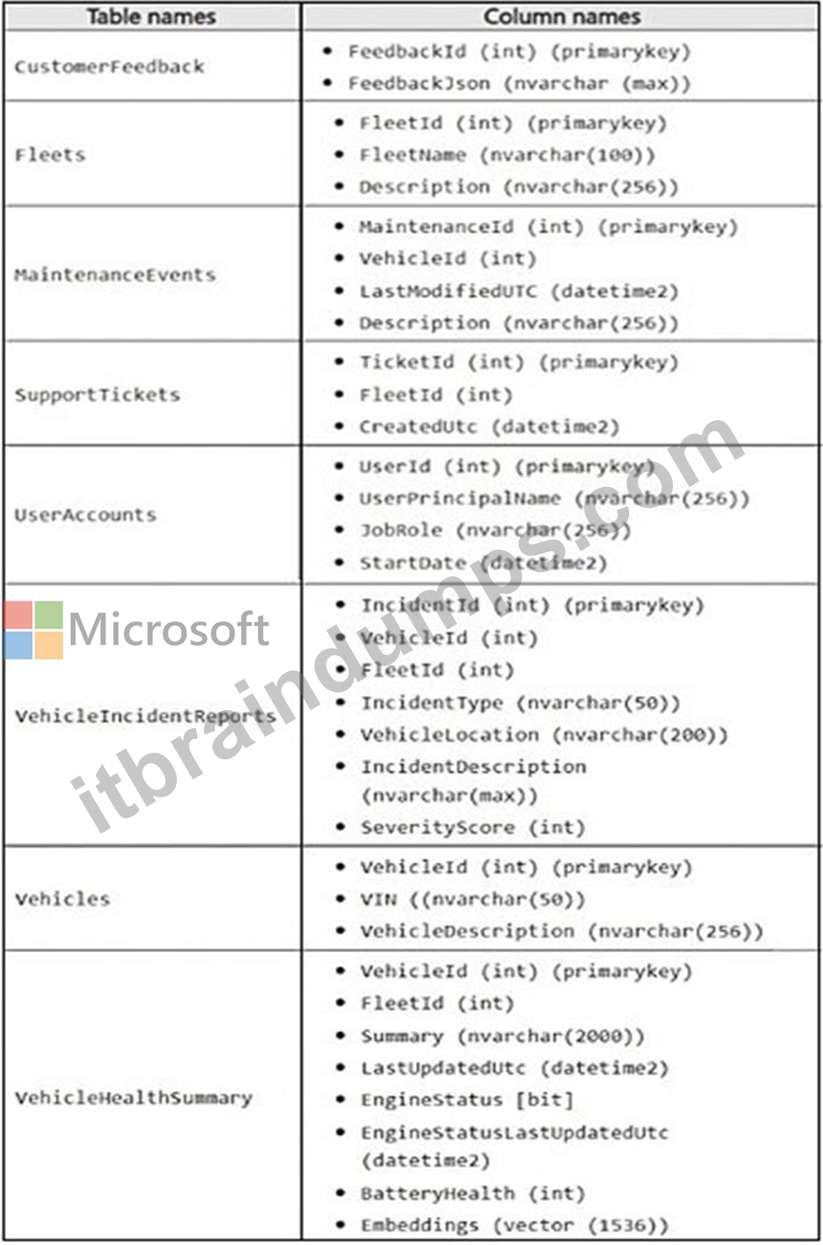
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.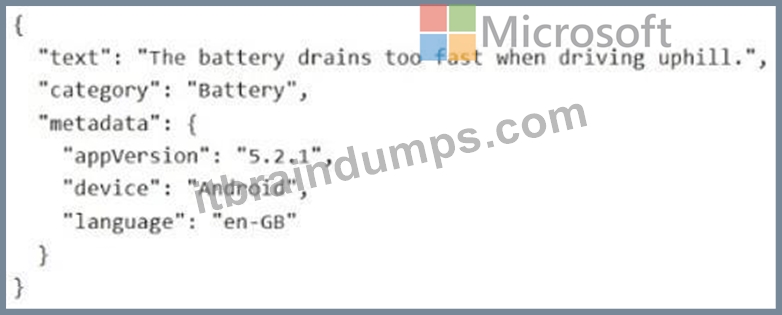
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.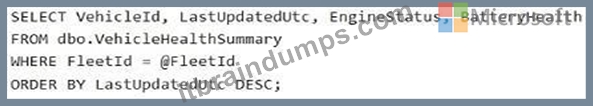
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution to resolve the slow dashboard query issue. What should you recommend?
Answer: C
Explanation:
Scenario:
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
To optimize this query, you should create a covering nonclustered index that handles both the filtering (WHERE) and the sorting (ORDER BY) requirements while including the remaining columns to avoid expensive lookups.
Recommended Index Strategy
Creating an index with FleetID as the first key column and LastUpdateUtc as the second key column will allow SQL Server to perform an Index Seek to find the specific fleet and then retrieve those rows in the pre-sorted order required by your ORDER BY clause.
T-SQL Implementation:
CREATE NONCLUSTERED INDEX IX_VehicleHealth_Fleet_Update
ON dbo.VehicleHealthSummary (FleetID, LastUpdateUtc DESC)
INCLUDE (EngineStatus, BatteryHealth);
Use code with caution.
Why this works
Eliminates Clustered Index Scan: The current plan scans the entire table because no index exists that starts with FleetID. This new index allows the engine to jump directly to the relevant rows.
Avoids a Sort Operator: By including LastUpdateUtc DESC in the index key, the data is already physically ordered. SQL Server can read the index and return the results immediately without needing a costly in-memory sort.
Fully Covers the Query: Using the INCLUDE clause for EngineStatus and BatteryHealth ensures all data required by the SELECT statement is present in the index. This prevents "Key Lookups," where the engine would otherwise have to go back to the original table for those specific values.
Reference:
https://www.mssqltips.com/sqlservertip/8192/sql-server-uses-non-clustered-index-rather-than- clustered-index
NEW QUESTION # 46
You have a Microsoft SQL Server 2025 instance that contains a database named SalesDB SalesDB supports a Retrieval Augmented Generation (RAG) pattern for internal support tickets. The SQL Server instance runs without any outbound network connectivity.
You plan to generate embeddings inside the SQL Server instance and store them in a table for vector similarity queries.
You need to ensure that only a database user account named AlApplicationUser can run embedding generation by using the model.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Because the SQL Server 2025 instance has no outbound network connectivity , the embedding model cannot rely on a remote REST endpoint such as Azure AI Foundry or Azure OpenAI. Microsoft's CREATE EXTERNAL MODEL documentation includes a local deployment pattern using ONNX Runtime running locally with local runtime/model paths . That is the right design when embeddings must be generated inside the SQL Server instance without external network access. Microsoft explicitly documents a local ONNX Runtime example for SQL Server 2025 and notes the required local runtime setup and model path configuration.
The permission requirement is handled by granting the application user access to use the external embeddings model. Microsoft's AI_GENERATE_EMBEDDINGS documentation states that, as a prerequisite, you must create an external model of type EMBEDDINGS that is accessible via the correct grants, roles, and/or permissions . Among the choices, the exam-appropriate action is to grant execute permission on the external model project to AlApplicationUser so only that database user can run embedding generation through the model.
NEW QUESTION # 47
You have an Azure SQL database named SalesDB that supports an AI-enabled product search application.
SalesDB has a table named SalesLT.Product that contains the following columns:
* ProductID (int)
* Name (nvarchar(100))
* ListPrice (decimal(18,2))
You need to create an object that returns products priced above a caller-provided threshold. The solution must meet the following requirements:
* Support being used in a join.
* Accept one input parameter.
* Return a table result.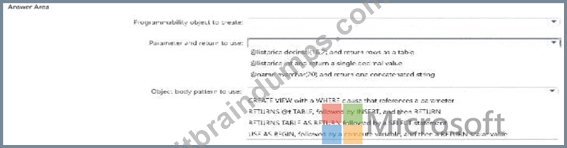
Answer:
Explanation: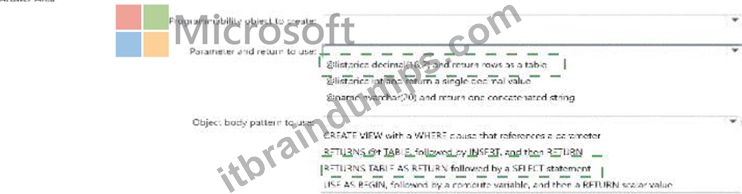
Explanation: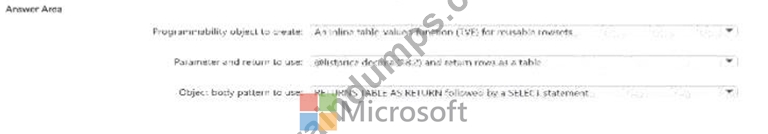
NEW QUESTION # 48
......
DP-800 Actual Questions: https://www.itbraindumps.com/DP-800_exam.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=1BL92sNKjhMfJT_wdcwzSqwIO3BODexzp