P.S. JPTestKingがGoogle Driveで共有している無料かつ新しいDEA-C02ダンプ:https://drive.google.com/open?id=1PPArmPBPeUPOLG8hwSfSU6nGV3WFze7T
あなたは君の初めてのSnowflakeのDEA-C02認定試験を受ける時に認定試験に合格したいか。JPTestKingでは、私たちは君のすべての夢を叶えさせて、君の最も早い時間でSnowflakeのDEA-C02認定試験に合格するということを保証します。JPTestKingのSnowflakeのDEA-C02試験トレーニング資料は豊富な経験を持っているIT専門家が研究したもので、問題と解答が緊密に結んでいるものです。JPTestKingを選ぶなら、絶対に後悔させません。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Sourcing | 20-25% | - Design and implement continuous and batch ingestion pipelines - Handle different data formats: structured, semi-structured, unstructured - Ingest data from various sources: data lakes, APIs, on-premises systems, cloud storage - Use Snowflake ingestion methods: Snowpipe, COPY INTO, External Functions |
| Topic 2: Data Governance, Security, and Compliance | 10-15% | - Manage data lineage, cataloging, and compliance policies - Implement access control: RBAC, authentication, authorization - Enforce data quality and governance standards - Apply data protection: encryption, masking, row-level security |
| Topic 3: Data Pipeline Architecture and Design | 15-20% | - Apply design patterns for data engineering workloads - Build end-to-end near real-time streaming solutions - Integrate with external tools and platforms: orchestration, BI, ML - Design scalable, reliable, and maintainable data pipelines |
| Topic 4: Performance Optimization and Compute Management | 15-20% | - Optimize query performance: clustering, partitioning, materialized views - Use search optimization and query acceleration services - Monitor and tune workloads and resource utilization - Manage virtual warehouses: sizing, scaling, multi-cluster, cost control |
| Topic 5: Data Sharing and Collaboration | 5-10% | - Design multi-tenant and cross-account data architectures - Implement secure data sharing and data exchanges - Work with Snowflake Data Marketplace and external data providers |
| Topic 6: Data Transformation and Processing | 20-25% | - Manage data quality, validation, and deduplication - Transform and enrich data using SQL, JavaScript, Python, and Snowpark - Implement ELT/ETL workflows using Streams, Tasks, and Dynamic Tables - Process semi-structured data: JSON, Avro, Parquet, ORC |
DEA-C02試験問題の継続的な刷新により、当社は大きな市場シェアを占めています。強力な研究センターを構築し、DEA-C02トレーニングガイドでより良い仕事をするために強力なチームを所有しています。Snowflakeこれまで、DEA-C02学習教材に関する多くの特許を取得しています。一方で、当社は改修の恩恵を受けています。お客様は当社の製品を選択する可能性が高くなります。一方、私たちが投資したお金は有意義なものであり、DEA-C02試験の新しい学習スタイルを刷新するのに役立ちます。
質問 # 133
You are using the Snowflake REST API to insert data into a table named 'RAW JSON DATA. The JSON data is complex and nested, and you want to efficiently parse and flatten it into a relational structure. You have the following JSON sample: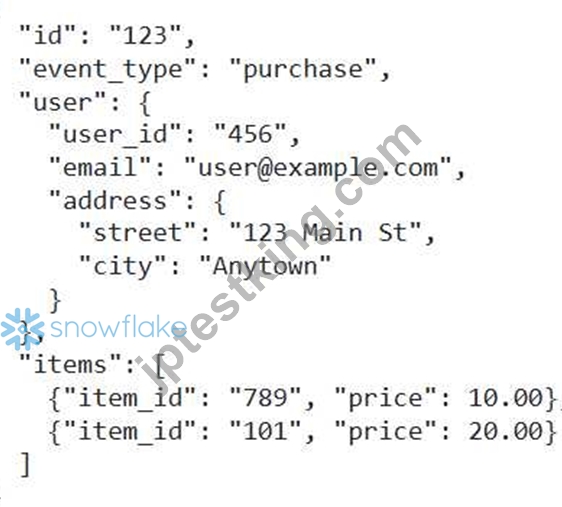
Which SQL statement, executed after loading the raw JSON using the REST API, is the MOST efficient way to flatten the JSON and extract relevant fields into a new table named 'PURCHASES' with columns like 'EVENT TYPE', 'USER D', 'EMAIL', 'STREET, 'CITY', 'ITEM ID', and 'PRICE'?
正解:B
解説:
Option C is the most efficient and correct. It uses the correct Snowflake syntax for accessing JSON elements with and for data type casting and also correctly uses the TABLE(FLATTEN()) function to handle the nested 'items' array. Option A utilizes a deprecated syntax LATERAL FLATTEN'. Options B, D and E don't handle the nested JSON structure properly or the flattening of the 'items' array, resulting in incomplete or incorrect data extraction.
質問 # 134
Consider the following scenario: You have a Snowflake task that refreshes a materialized view. The materialized view is based on a large base table that is constantly being updated. The refresh operation is taking longer than expected, impacting downstream reporting. Which of the following actions will likely NOT improve the performance of the materialized view refresh?
正解:A
解説:
Adding more columns to the materialized view (Option C) will generally worsen the performance of refresh operations, as it increases the amount of data that needs to be processed and stored. The materialized view only needs the minimal set of columns required by its query. All other options will likely improve performance or provide data to improve performance. Option A allows for more resources to be used during the refresh. Option B reduces the amount of data that needs to be scanned. Option D automates the refresh process, making it more efficient overall and leverages Snowflake's automatic refresh optimization. Option E: by analyzing the query profile, data engineers can uncover specific areas for improvement within the query execution plan.
質問 # 135
You are working with a directory table named associated with an external stage containing a large number of small JSON files. You need to process only the files containing specific sensor readings based on a substring match within their filenames (e.g., files containing 'temperature' in the filename). You also want to load these files into a Snowflake table 'sensor_readings. Consider performance and cost-effectiveness. Which of the following approaches is the MOST efficient and cost-effective to achieve this? Choose TWO options.
正解:B、C
解説:
Options B and C are the most efficient and cost-effective. Option B (Create a view and use COPY INTO with FILES): Creating a view that filters the directory table allows you to isolate the relevant filenames. Then, using 'COPY INTO' with the 'FILES' parameter pointing to this filtered view directly instructs Snowflake to load only the specified files, minimizing unnecessary data processing. This is efficient as it leverages Snowflake's built-in capabilities. Option C (COPY INTO with the PATTERN parameter): The 'PATTERN' parameter within the 'COPY INTO' command allows you to specify a regular expression. By incorporating the substring match into this regular expression against the metadata$filename" , you can directly filter which files are loaded during the 'COPY INTO operation. This avoids loading irrelevant data and is generally more performant than iterating through files using a UDF. Other options are less efficient or less cost-effective: Option A (Python UDF): Using a Python UDF for this task is generally less efficient. Snowflake is designed to handle this processing natively, and using UDF can lead to performance overhead due to data serialization and deserialization between Snowflake and the UDF environment. Option D (Load all and filter later): Loading all files into a staging table and then filtering is wasteful. It increases data processing time and costs since you're loading unnecessary data. It's always better to filter data closer to the source if possible. Option E (Masking Policy): Masking policies are for security, not data transformation. They are applied at the query level to prevent users from seeing data, but do not help in efficiently processing only specific files.
質問 # 136
A large e-commerce company stores clickstream data in an AWS S3 bucket. The data is partitioned by date and consists of Parquet files. They need to analyze this data in Snowflake without physically moving it into Snowflake's internal storage. However, the data frequently changes, and they need to ensure queries reflect the latest updates to the files without significant latency. Which of the following approaches would be MOST suitable, considering cost, performance, and data freshness?
正解:E
解説:
Iceberg tables are the most suitable option in this scenario. They address the limitations of standard external tables regarding metadata management and incremental updates. 'AUTO REFRESH' for external tables isn't ideal for frequent changes as it still relies on scanning the file system. A Snowflake-managed catalog with Snowpipe could work, but Iceberg is more purpose-built for handling the data evolution in place. READ_PARQUET in views is inefficient as it requires parsing the data every time the view is queried. Iceberg provides ACID properties and optimized query performance on data residing in external storage. The key benefit is the automatic metadata management provided by Snowflake for Iceberg tables.
質問 # 137
You have a table 'EMPLOYEE DATA' containing Personally Identifiable Information (PII), including 'salary' and 'email'. You need to implement column-level security such that: 1) The 'salary' column is only visible to users in the 'FINANCE ROLE. 2) The 'email' column is masked with a SHA256 hash for all users except those in the 'HR ROLE. You create the following masking policies:
Which of the following SQL statements correctly applies these masking policies to the 'EMPLOYEE DATA table?
正解:B
解説:
The correct syntax for applying a masking policy to a column is 'ALTER TABLE ALTER COLUMN SET MASKING POLICY MODIFY COLUMN' is used for changing data types or constraints, not applying masking policies. The sign after 'SET MASKING POLICY is incorrect syntax. There's no 'APPLY MASKING POLICY command in Snowflake.
質問 # 138
......
DEA-C02トレーニングガイドSnowflakeでは、PDFバージョン、PCバージョン、APPオンラインバージョンを含む3つのバージョンを強化しています。 DEA-C02テストガイドは非常に効率的で、回答と質問の形式は同じです。バージョンが異なると、独自の機能と使用方法が強化され、クライアントは最も便利な方法を選択できます。たとえば、DEA-C02ガイドトレントのPDF形式は印刷可能で、ダウンロードへの即時アクセスを促進します。いつでも学習でき、1年の任意の日にDEA-C02試験問題を自由に更新できます。
DEA-C02資格準備: https://www.jptestking.com/DEA-C02-exam.html
BONUS!!! JPTestKing DEA-C02ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1PPArmPBPeUPOLG8hwSfSU6nGV3WFze7T