Leave yourself some spare time to study and think. Perhaps you will regain courage and confidence through a period of learning our ACD-301 preparation quiz. If you want to have a try, we have free demos of our ACD-301 exam questions to help you know about our products. And there are three versions of the free demos according to the three different versions of the ACD-301 study braindumps: the PDF, the Software and the APP online. Just try and you will love them.
| Section | Objectives |
|---|---|
| Application Design and Architecture | - Solution structuring and application layering - Reusable components and design patterns |
| Expression Language and Logic | - Advanced Appian expression functions - Rule design and optimization |
| Process Modeling | - Exception handling and optimization - Advanced process model design |
| User Interface Design | - User experience best practices - Interface design and dynamic layouts |
| Data Management | - Data types and CDT structures - Record types and data stores |
| Security and Deployment | - Security roles and group management - Deployment pipelines and environment management |
App online version being suitable to all kinds of digital equipment is supportive to offline exercises on the condition that you practice it without mobile data. These versions of ACD-301 test guide make our customers sublimely happy. So they are great ACD-301 test guide with high approbation. Our ACD-301 Torrent prep is fabulous with inspired points of questions for your reference. After your practice and regular review of our ACD-301 exam questions the advancement will be obvious, and your skills of the exam will be improved greatly.
NEW QUESTION # 14
You are required to configure a connection so that Jira can inform Appian when specific tickets change (using a webhook). Which three required steps will allow you to connect both systems?
Answer: A,B,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Configuring a webhook connection from Jira to Appian requires setting up a mechanism for Jira to push ticket change notifications to Appian in real-time. This involves creating an endpoint in Appian to receive the webhook and configuring Jira to send the data. Appian's Integration Best Practices and Web API documentation provide the framework for this process.
Option A (Create a Web API object and set up the correct security):
This is a required step. In Appian, a Web API object serves as the endpoint to receive incoming webhook requests from Jira. You must define the API structure (e.g., HTTP method, input parameters) and configure security (e.g., basic authentication, API key, or OAuth) to validate incoming requests. Appian recommends using a service account with appropriate permissions to ensure secure access, aligning with the need for a controlled webhook receiver.
Option B (Configure the connection in Jira specifying the URL and credentials):
This is essential. In Jira, you need to set up a webhook by providing the Appian Web API's URL (e.g., https://<appian-site>/suite/webapi/<web-api-name>) and the credentials or authentication method (e.g., API key or basic auth) that match the security setup in Appian. This ensures Jira can successfully send ticket change events to Appian.
Option C (Create a new API Key and associate a service account):
This is necessary for secure authentication. Appian recommends using an API key tied to a service account for webhook integrations. The service account should have permissions to process the incoming data (e.g., write to a process or data store) but not excessive privileges. This step complements the Web API security setup and Jira configuration.
Option D (Give the service account system administrator privileges):
This is unnecessary and insecure. System administrator privileges grant broad access, which is overkill for a webhook integration. Appian's security best practices advocate for least-privilege principles, limiting the service account to the specific objects or actions needed (e.g., executing the Web API).
Option E (Create an integration object from Appian to Jira to periodically check the ticket status):
This is incorrect for a webhook scenario. Webhooks are push-based, where Jira notifies Appian of changes. Creating an integration object for periodic polling (pull-based) is a different approach and not required for the stated requirement of Jira informing Appian via webhook.
These three steps (A, B, C) establish a secure, functional webhook connection without introducing unnecessary complexity or security risks.
The three required steps that will allow you to connect both systems are:
A . Create a Web API object and set up the correct security. This will allow you to define an endpoint in Appian that can receive requests from Jira via webhook. You will also need to configure the security settings for the Web API object, such as authentication method, allowed origins, and access control.
B . Configure the connection in Jira specifying the URL and credentials. This will allow you to set up a webhook in Jira that can send requests to Appian when specific tickets change. You will need to specify the URL of the Web API object in Appian, as well as any credentials required for authentication.
C . Create a new API Key and associate a service account. This will allow you to generate a unique token that can be used for authentication between Jira and Appian. You will also need to create a service account in Appian that has permissions to access or update data related to Jira tickets.
The other options are incorrect for the following reasons:
D . Give the service account system administrator privileges. This is not required and could pose a security risk, as giving system administrator privileges to a service account could allow it to perform actions that are not related to Jira tickets, such as modifying system settings or accessing sensitive data.
E . Create an integration object from Appian to Jira to periodically check the ticket status. This is not required and could cause unnecessary overhead, as creating an integration object from Appian to Jira would involve polling Jira for ticket status changes, which could consume more resources than using webhook notifications. Verified Appian Documentation, section "Web API" and "API Keys".
NEW QUESTION # 15
You are on a protect with an application that has been deployed to Production and is live with users. The client wishes to increase the number of active users.
You need to conduct load testing to ensure Production can handle the increased usage Review the specs for four environments in the following image.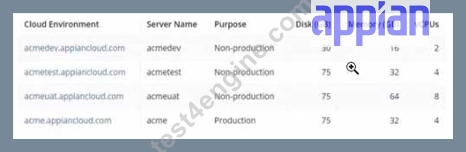
Which environment should you use for load testing7
Answer: A
Explanation:
The image provides the specifications for four environments in the Appian Cloud:
acmedev.appiancloud.com (acmedev): Non-production, Disk: 30 GB, Memory: 16 GB, vCPUs: 2 acmetest.appiancloud.com (acmetest): Non-production, Disk: 75 GB, Memory: 32 GB, vCPUs: 4 acmeuat.appiancloud.com (acmeuat): Non-production, Disk: 75 GB, Memory: 64 GB, vCPUs: 8 acme.appiancloud.com (acme): Production, Disk: 75 GB, Memory: 32 GB, vCPUs: 4 Load testing assesses an application's performance under increased user load to ensure scalability and stability. Appian's Performance Testing Guidelines emphasize using an environment that mirrors Production as closely as possible to obtain accurate results, while avoiding direct impact on live systems.
Option A (acmeuat):This is the best choice. The UAT (User Acceptance Testing) environment (acmeuat) has the highest resources (64 GB memory, 8 vCPUs) among the non-production environments, closely aligning with Production's capabilities (32 GB memory, 4 vCPUs) but with greater capacity to handle simulated loads. UAT environments are designed to validate the application with real-world usage scenarios, making them ideal for load testing. The higher resources also allow testing beyond current Production limits to predict future scalability, meeting the client's goal of increasing active users without risking live data.
Option B (acmedev):The development environment (acmedev) has the lowest resources (16 GB memory, 2 vCPUs), which is insufficient for load testing. It's optimized for development, not performance simulation, and results would not reflect Production behavior accurately.
Option C (acme):The Production environment (acme) is live with users, and load testing here would disrupt service, violate Appian's Production Safety Guidelines, and risk data integrity. It should never be used for testing.
Option D (acmetest):The test environment (acmetest) has moderate resources (32 GB memory, 4 vCPUs), matching Production's memory and vCPUs. However, it's typically used for SIT (System Integration Testing) and has less capacity than acmeuat. While viable, it's less ideal than acmeuat for simulating higher user loads due to its resource constraints.
Appian recommends using a UAT environment for load testing when it closely mirrors Production and can handle simulated traffic, making acmeuat the optimal choice given its superior resources and non-production status.
NEW QUESTION # 16
You need to connect Appian with LinkedIn to retrieve personal information about the users in your application. This information is considered private, and users should allow Appian to retrieve their information. Which authentication method would you recommend to fulfill this request?
Answer: D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, integrating with an external system like LinkedIn to retrieve private user information requires a secure, user-consented authentication method that aligns with Appian's capabilities and industry standards. The requirement specifies that users must explicitly allow Appian to access their private data, which rules out methods that don't involve user authorization. Let's evaluate each option based on Appian's official documentation and LinkedIn's API requirements:
A . API Key Authentication:
API Key Authentication involves using a single static key to authenticate requests. While Appian supports this method via Connected Systems (e.g., HTTP Connected System with an API key header), it's unsuitable here. API keys authenticate the application, not the user, and don't provide a mechanism for individual user consent. LinkedIn's API for private data (e.g., profile information) requires per-user authorization, which API keys cannot facilitate. Appian documentation notes that API keys are best for server-to-server communication without user context, making this option inadequate for the requirement.
B . Basic Authentication with user's login information:
This method uses a username and password (typically base64-encoded) provided by each user. In Appian, Basic Authentication is supported in Connected Systems, but applying it here would require users to input their LinkedIn credentials directly into Appian. This is insecure, impractical, and against LinkedIn's security policies, as it exposes user passwords to the application. Appian Lead Developer best practices discourage storing or handling user credentials directly due to security risks (e.g., credential leakage) and maintenance challenges. Moreover, LinkedIn's API doesn't support Basic Authentication for user-specific data access-it requires OAuth 2.0. This option is not viable.
C . Basic Authentication with dedicated account's login information:
This involves using a single, dedicated LinkedIn account's credentials to authenticate all requests. While technically feasible in Appian's Connected System (using Basic Authentication), it fails to meet the requirement that "users should allow Appian to retrieve their information." A dedicated account would access data on behalf of all users without their individual consent, violating privacy principles and LinkedIn's API terms. LinkedIn restricts such approaches, requiring user-specific authorization for private data. Appian documentation advises against blanket credentials for user-specific integrations, making this option inappropriate.
D . OAuth 2.0: Authorization Code Grant:
This is the recommended choice. OAuth 2.0 Authorization Code Grant, supported natively in Appian's Connected System framework, is designed for scenarios where users must authorize an application (Appian) to access their private data on a third-party service (LinkedIn). In this flow, Appian redirects users to LinkedIn's authorization page, where they grant permission. Upon approval, LinkedIn returns an authorization code, which Appian exchanges for an access token via the Token Request Endpoint. This token enables Appian to retrieve private user data (e.g., profile details) securely and per user. Appian's documentation explicitly recommends this method for integrations requiring user consent, such as LinkedIn, and provides tools like a!authorizationLink() to handle authorization failures gracefully. LinkedIn's API (e.g., v2 API) mandates OAuth 2.0 for personal data access, aligning perfectly with this approach.
Conclusion: OAuth 2.0: Authorization Code Grant (D) is the best method. It ensures user consent, complies with LinkedIn's API requirements, and leverages Appian's secure integration capabilities. In practice, you'd configure a Connected System in Appian with LinkedIn's Client ID, Client Secret, Authorization Endpoint (e.g., https://www.linkedin.com/oauth/v2/authorization), and Token Request Endpoint (e.g., https://www.linkedin.com/oauth/v2/accessToken), then use an Integration object to call LinkedIn APIs with the access token. This solution is scalable, secure, and aligns with Appian Lead Developer certification standards for third-party integrations.
Appian Documentation: "Setting Up a Connected System with the OAuth 2.0 Authorization Code Grant" (Connected Systems).
Appian Lead Developer Certification: Integration Module (OAuth 2.0 Configuration and Best Practices).
LinkedIn Developer Documentation: "OAuth 2.0 Authorization Code Flow" (API Authentication Requirements).
NEW QUESTION # 17
Your application contains a process model that is scheduled to run daily at a certain time, which kicks off a user input task to a specified user on the 1st time zone for morning data collection. The time zone is set to the (default) pm!timezone. In this situation, what does the pm!timezone reflect?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In Appian, the pm!timezone variable is a process variable automatically available in process models, reflecting the time zone context for scheduled or time-based operations. Understanding its behavior is critical for scheduling tasks accurately, especially in scenarios like this where a process runs daily and assigns a user input task.
Option C (The default time zone for the environment as specified in the Administration Console):
This is the correct answer. Per Appian's Process Model documentation, when a process model uses pm!timezone and no custom time zone is explicitly set, it defaults to the environment's time zone configured in the Administration Console (under System > Time Zone settings). For scheduled processes, such as one running "daily at a certain time," Appian uses this default time zone to determine when the process triggers. In this case, the task assignment occurs based on the schedule, and pm!timezone reflects the environment's setting, not the user's location.
Option A (The time zone of the server where Appian is installed): This is incorrect. While the server's time zone might influence underlying system operations, Appian abstracts this through the Administration Console's time zone setting. The pm!timezone variable aligns with the configured environment time zone, not the raw server setting.
Option B (The time zone of the user who most recently published the process model): This is irrelevant. Publishing a process model does not tie pm!timezone to the publisher's time zone. Appian's scheduling is system-driven, not user-driven in this context.
Option D (The time zone of the user who is completing the input task): This is also incorrect. While Appian can adjust task display times in the user interface to the assigned user's time zone (based on their profile settings), the pm!timezone in the process model reflects the environment's default time zone for scheduling purposes, not the assignee's.
For example, if the Administration Console is set to EST (Eastern Standard Time), the process will trigger daily at the specified time in EST, regardless of the assigned user's location. The "1st time zone" phrasing in the question appears to be a typo or miscommunication, but it doesn't change the fact that pm!timezone defaults to the environment setting.
NEW QUESTION # 18
You are taking your package from the source environment and importing it into the target environment.
Review the errors encountered during inspection:
What is the first action you should take to Investigate the issue?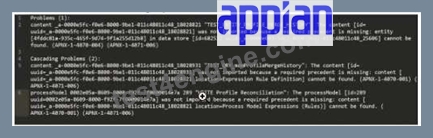
Answer: B
Explanation:
The error log provided indicates issues during the package import into the target environment, with multiple objects failing to import due to missing precedents. The key error messages highlight specific UUIDs associated with objects that cannot be resolved. The first error listed states:
"'TEST_ENTITY_PROFILE_MERGE_HISTORY': The content [id=uuid-a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] was not imported because a required precedent is missing: entity [uuid=a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] cannot be found..." According to Appian's Package Deployment Best Practices, when importing a package, the first step in troubleshooting is to identify the root cause of the failure. The initial error in the log points to an entity object with a UUID ending in 18028821, which failed to import due to a missing precedent. This suggests that the object itself or one of its dependencies (e.g., a data store or related entity) is either missing from the package or not present in the target environment.
Option A (Check whether the object (UUID ending in 18028821) is included in this package): This is the correct first action. Since the first error references this UUID, verifying its inclusion in the package is the logical starting point. If it's missing, the package export from the source environment was incomplete. If it's included but still fails, the precedent issue (e.g., a missing data store) needs further investigation.
Option B (Check whether the object (UUID ending in 7t00000i4e7a) is included in this package): This appears to be a typo or corrupted UUID (likely intended as something like "7t000014e7a" or similar), and it's not referenced in the primary error. It's mentioned later in the log but is not the first issue to address.
Option C (Check whether the object (UUID ending in 25606) is included in this package): This UUID is associated with a data store error later in the log, but it's not the first reported issue.
Option D (Check whether the object (UUID ending in 18028931) is included in this package): This UUID is mentioned in a subsequent error related to a process model or expression rule, but it's not the initial failure point.
Appian recommends addressing errors in the order they appear in the log to systematically resolve dependencies. Thus, starting with the object ending in 18028821 is the priority.
NEW QUESTION # 19
......
Test4Engine is determined to give hand to the candidates who want to pass their ACD-301 exam smoothly and with ease by their first try. Our professional experts have compiled the most visual version: the PDF version of our ACD-301 exam questions, which owns the advantage of convenient to be printed on the paper for it shows the entirety. In such a way, you can overcome your lack of confidence as well since you can have an overall look. The PDF version of our ACD-301 Study Guide will provide you the easiest, the most flexible and leisure study experience to success.
Book ACD-301 Free: https://www.test4engine.com/ACD-301_exam-latest-braindumps.html