BONUS!!! Itcertkr DP-700 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=19NlLG-ulF9xfG9iZCFA4IAsUrYSa7zWb
우리 Itcertkr에서는 최고이자 최신의Microsoft 인증DP-700덤프자료를 제공 함으로 여러분을 도와Microsoft 인증DP-700인증자격증을 쉽게 취득할 수 있게 해드립니다.만약 아직도Microsoft 인증DP-700시험패스를 위하여 고군분투하고 있다면 바로 우리 Itcertkr를 선택함으로 여러분의 고민을 날려버릴수 있습니다.
| Section | Objectives |
|---|---|
| Topic 1: Develop data transformation solutions | - Transform data using Spark in Fabric
|
| Topic 2: Manage and monitor data solutions | - Optimize performance and reliability
|
| Topic 3: Design and implement data ingestion solutions | - Integrate external data sources
|
| Topic 4: Secure and govern data in Microsoft Fabric | - Data governance and compliance
|
Pass4Tes가 제공하는 제품을 사용함으로 여러분은 IT업계하이클래스와 멀지 않았습니다. Pass4Tes 가 제공하는 인증시험덤프는 여러분을Microsoft인증DP-700시험을 안전하게 통과는 물론 관연전업지식장악에도 많은 도움이 되며 또한 우리는 일년무료 업뎃서비스를 제공합니다.
질문 # 102
HOTSPOT
You have a Fabric workspace that contains a warehouse named Warehouse1. Warehouse1 contains the following tables and columns.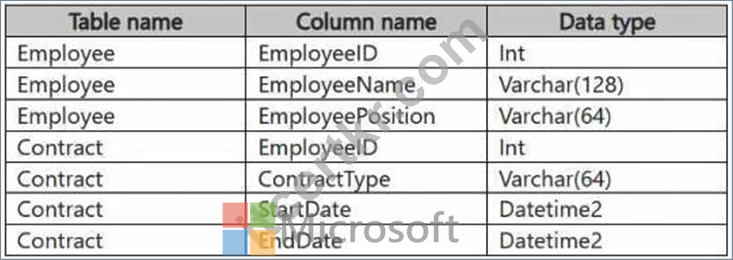
You need to denormalize the tables and include the ContractType and StartDate columns in the Employee table. The solution must meet the following requirements:
Ensure that the StartDate column is of the date data type.
Ensure that all the rows from the Employee table are preserved and include any matching rows from the Contract table.
Ensure that the result set displays the total number of employees per contract type for all the contract types that have more than two employees.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.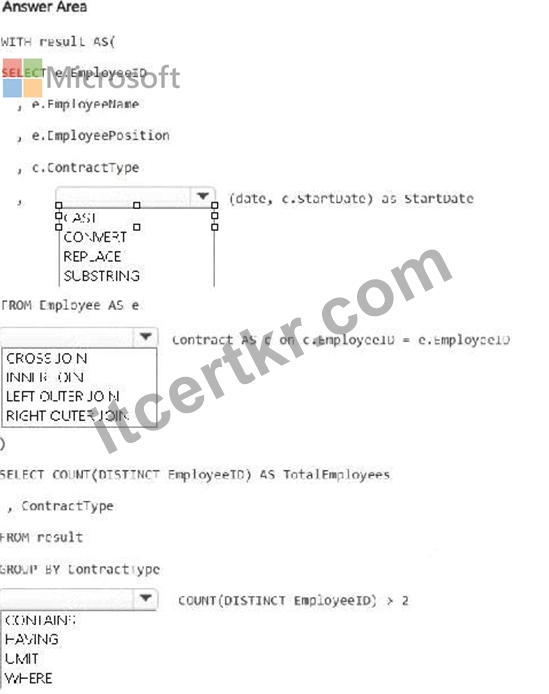
정답:
설명: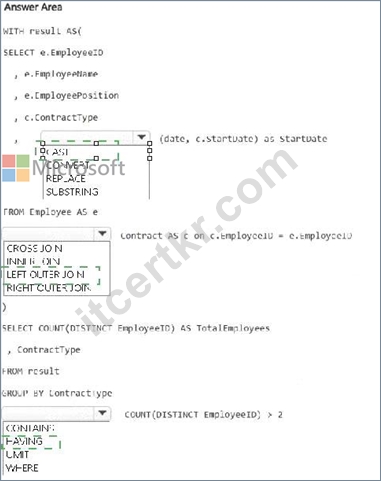
Explanation: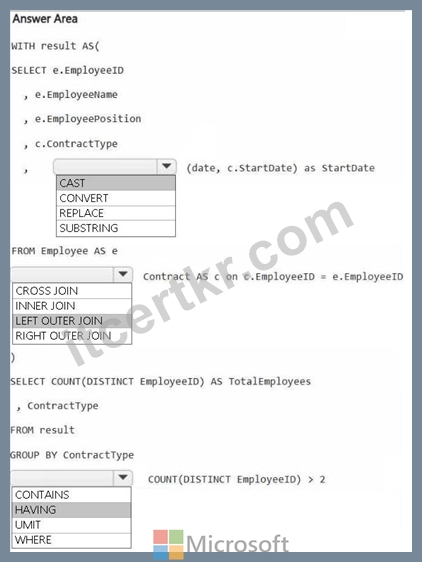
질문 # 103
HOTSPOT
You are building a data loading pattern for Fabric notebook workloads.
You have the following code segment: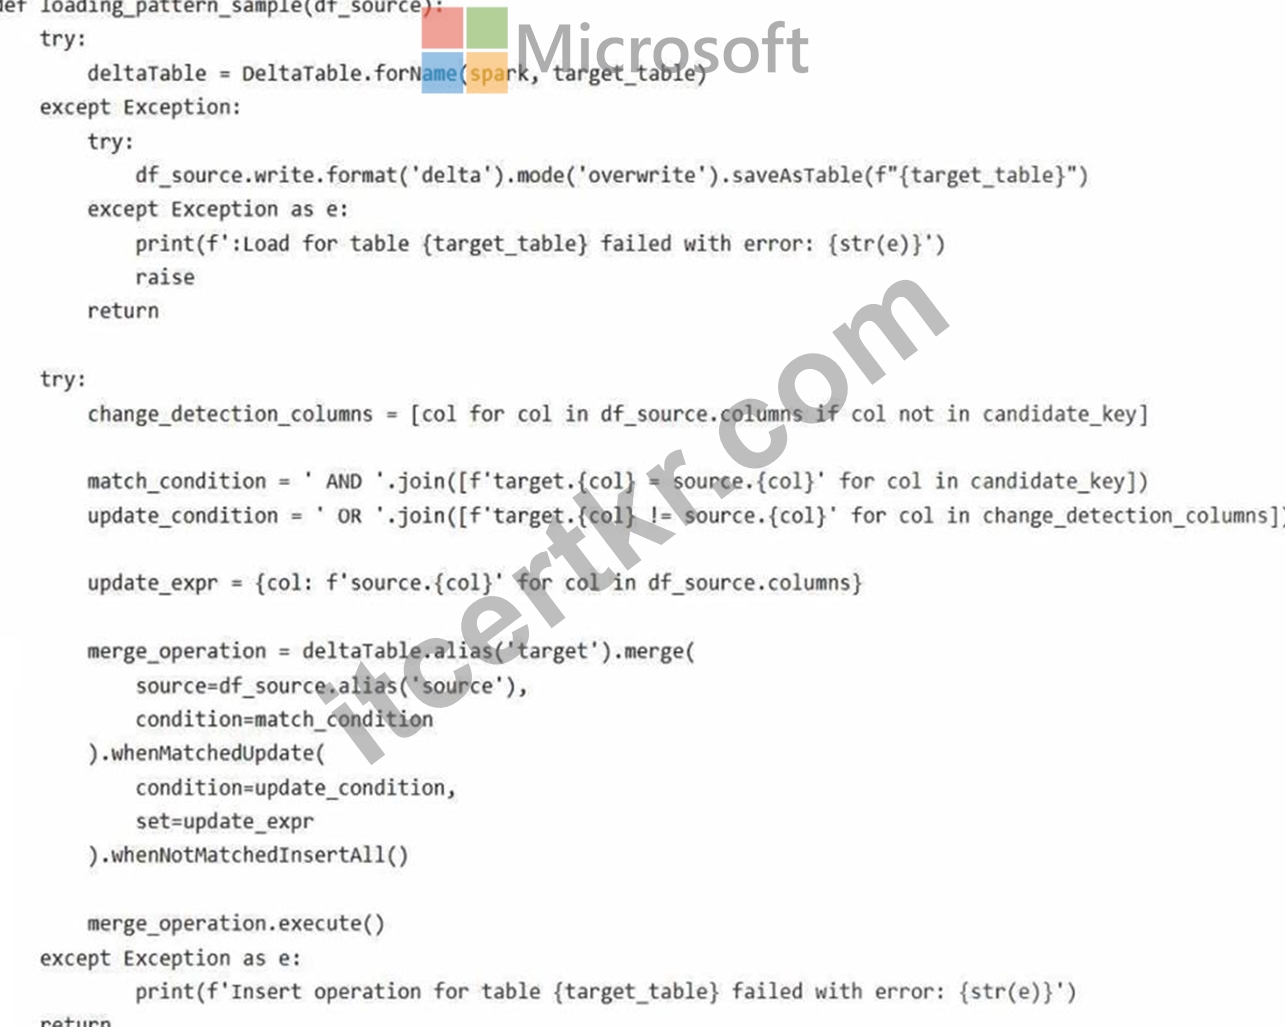
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.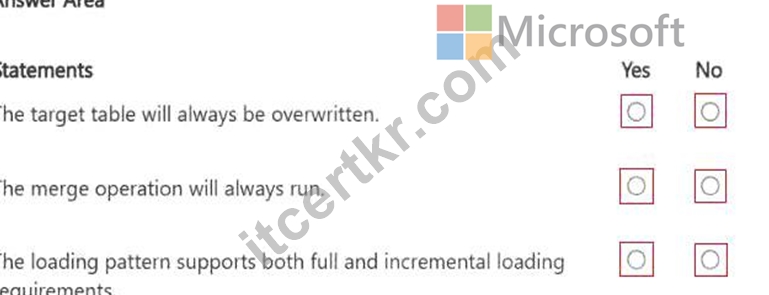
정답:
설명: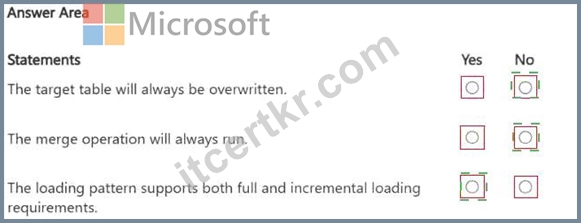
Explanation: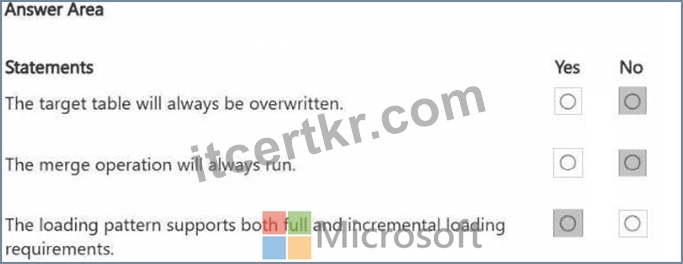
질문 # 104
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
You need to automate a PySpark-based data transformation process. The solution must meet the following requirements:
* Ensure that users can edit and test the PySpark code interactively.
* Ensure that the code can be operationalized for automated execution.
Which three actions should you perform in sequence?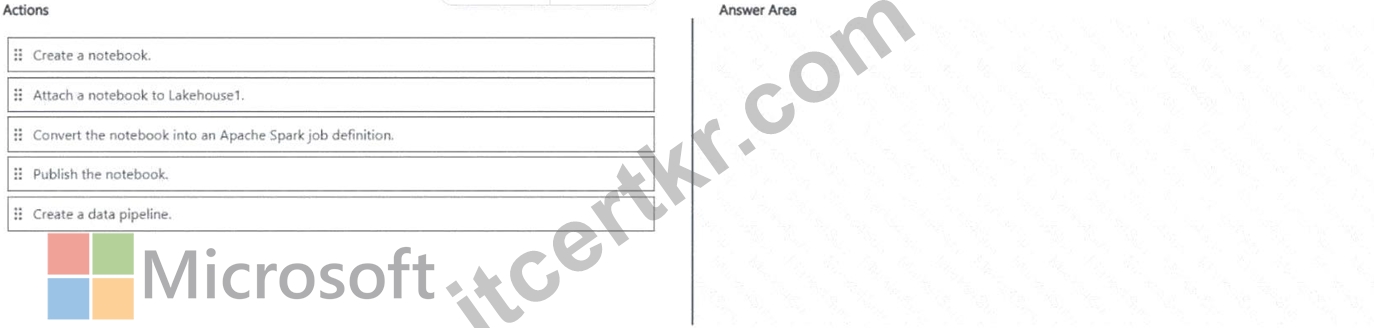
정답:
설명: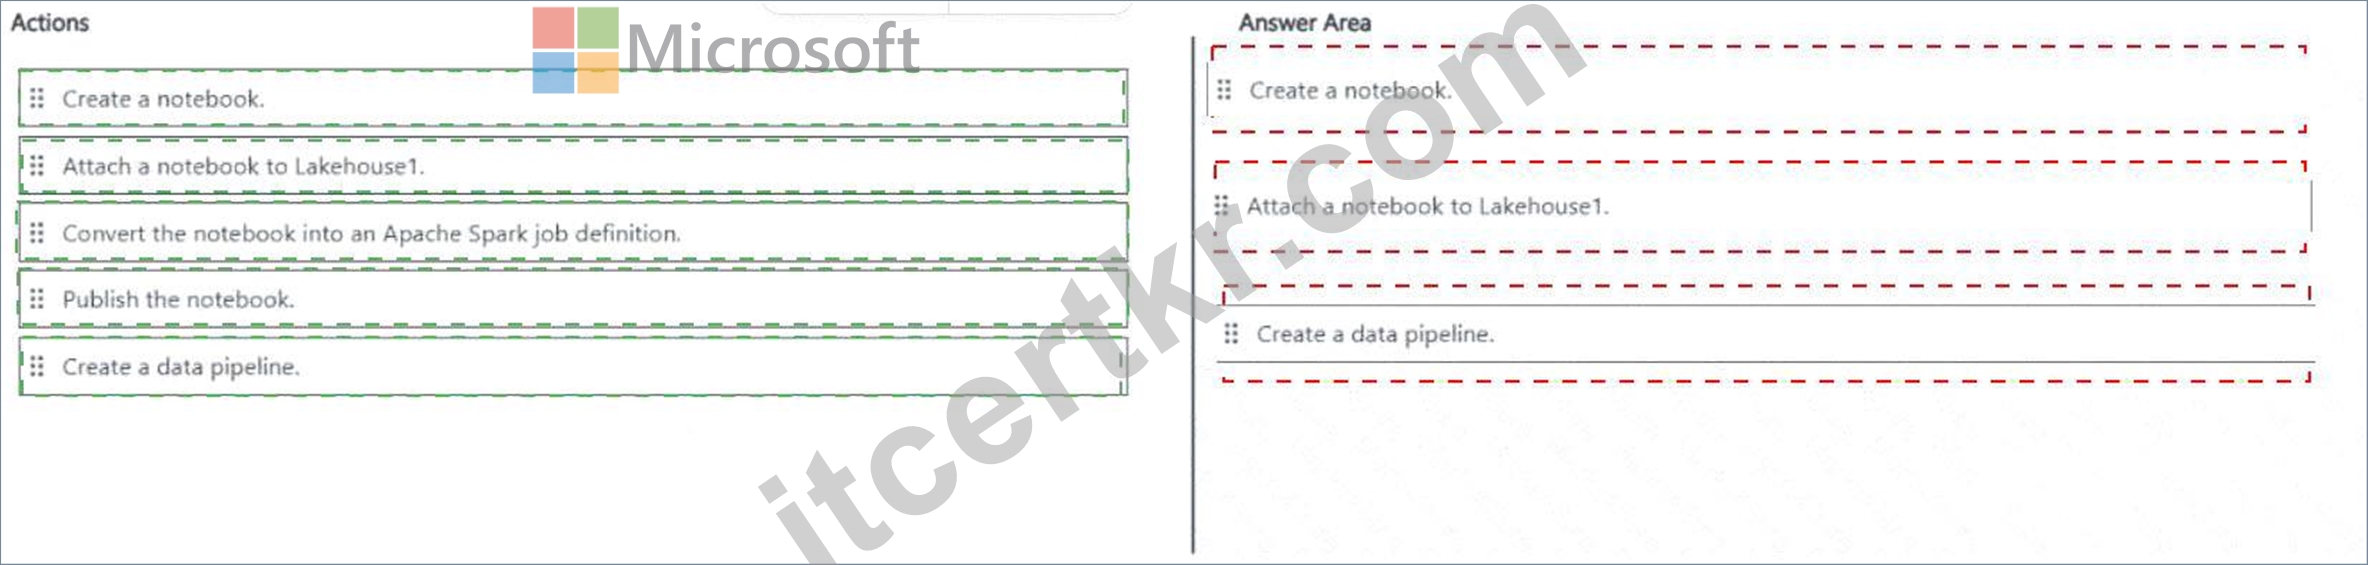
Explanation:
The correct sequence is Create a notebook # Attach the notebook to Lakehouse1 # Create a data pipeline
.
First, create a Fabric notebook because notebooks provide the interactive development environment required for authoring, executing, debugging, and testing PySpark code. Microsoft describes Fabric notebooks as a primary code item for developing Apache Spark workloads and specifically supports their use for data ingestion, preparation, and transformation.
Second, attach the notebook to Lakehouse1 . Attaching a lakehouse establishes the notebook ' s lakehouse context, allowing PySpark code to access the lakehouse ' s Files and Tables through Spark and OneLake. This enables developers to interactively validate the transformation against the required Fabric data.
Third, create a data pipeline and use a Notebook activity to operationalize the notebook. Fabric Data Factory explicitly supports running Fabric notebooks as pipeline activities for automated data transformation workflows. Pipelines can subsequently be run manually, scheduled, or incorporated into larger orchestration processes.
Converting the notebook to an Apache Spark job definition is unnecessary; Spark job definitions are separate executable Fabric items. Publishing the notebook is also not required for pipeline execution.
Study Guide reference: Ingest and transform data # Transform data with Apache Spark # Fabric notebooks # Orchestrate processes and schedules with Data Factory pipelines.
질문 # 105
HOTSPOT
You have a Fabric workspace named Workspace1_DEV that contains the following items:
10 reports
Four notebooks
Three lakehouses
Two data pipelines
Two Dataflow Gen1 dataflows
Three Dataflow Gen2 dataflows
Five semantic models that each has a scheduled refresh policy
You create a deployment pipeline named Pipeline1 to move items from Workspace1_DEV to a new workspace named Workspace1_TEST.
You deploy all the items from Workspace1_DEV to Workspace1_TEST.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.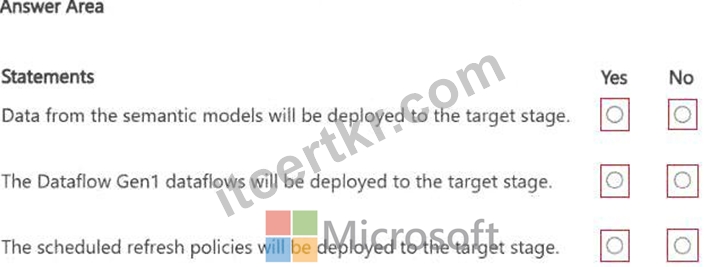
정답:
설명: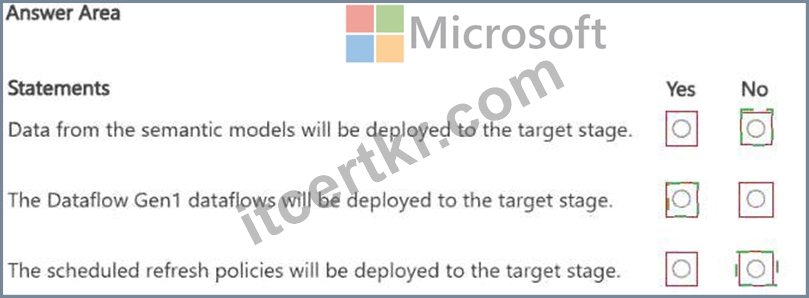
Explanation: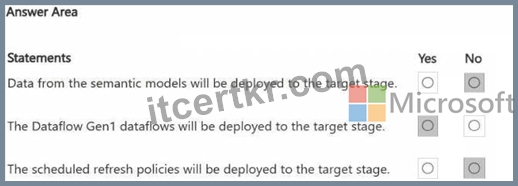
질문 # 106
You have a Fabric workspace named WS1 that is connected to the main branch of an Azure DevOps Git repository. WS1 contains a lakehouse a notebook and a pipeline.
Two data engineer must update the notebook and people concurrently for separate features.
You need to configure version control to support isolated feature development and controlled integration into the main branch.
The solution must meet the following requirements:
Prevent one engineer's reviewed workspace changes from affecting the other engineer workspace.
Support a review before changes are integrated into the main branch.
Track changes to the Fabric items in Git.
How should you configure the development workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.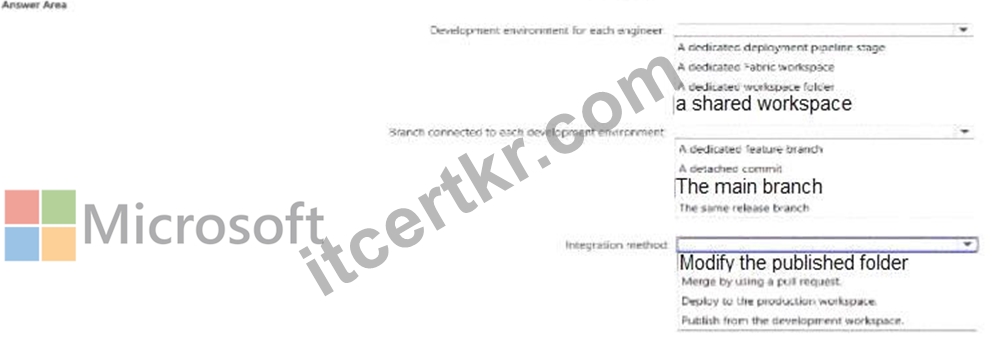
정답:
설명: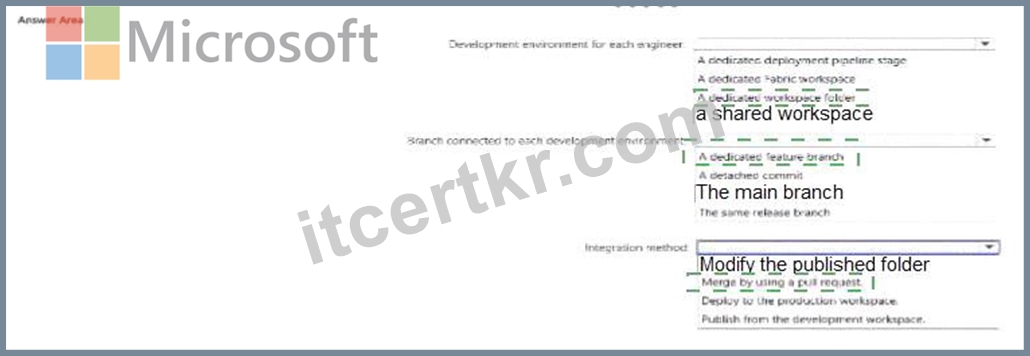
Explanation: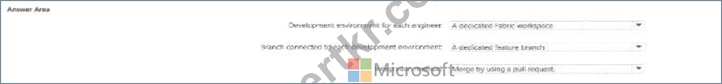
질문 # 107
......
Microsoft인증 DP-700시험은 빨리 패스해야 되는데 어디서부터 어떻게 시험준비를 시작해야 하는지 갈피를 잡을수 없는 분들은Itcertkr가 도와드립니다. Itcertkr의 Microsoft인증 DP-700덤프만 공부하면 시험패스에 자신이 생겨 불안한 상태에서 벗어날수 있습니다.덤프는 시장에서 가장 최신버전이기에 최신 시험문제의 모든 시험범위와 시험유형을 커버하여Microsoft인증 DP-700시험을 쉽게 패스하여 자격증을 취득하여 찬란한 미래에 더 가깝도록 도와드립니다.
DP-700시험패스 인증덤프문제: https://www.itcertkr.com/DP-700_exam.html
참고: Itcertkr에서 Google Drive로 공유하는 무료 2026 Microsoft DP-700 시험 문제집이 있습니다: https://drive.google.com/open?id=19NlLG-ulF9xfG9iZCFA4IAsUrYSa7zWb