In order to help customers solve the problem, our Implementing Data Engineering Solutions Using Azure Databricks test torrent support the printing of page. We will provide you with three different versions, the PDF version allow you to switch our DP-750 study torrent on paper. You just need to download the PDF version of our DP-750 Exam Prep, and then you will have the right to switch study materials on paper. We believe it will be more convenient for you to make notes. Our website is very secure and regular platform, you can be assured to download the version of our DP-750 study torrent.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
The language in our Microsoft DP-750 test guide is easy to understand that will make any learner without any learning disabilities, whether you are a student or a in-service staff, whether you are a novice or an experienced staff who has abundant experience for many years. It should be a great wonderful idea to choose our DP-750 Guide Torrent for sailing through the difficult test.
NEW QUESTION # 40
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: D
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 42
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: C
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 43
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: C
NEW QUESTION # 44
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.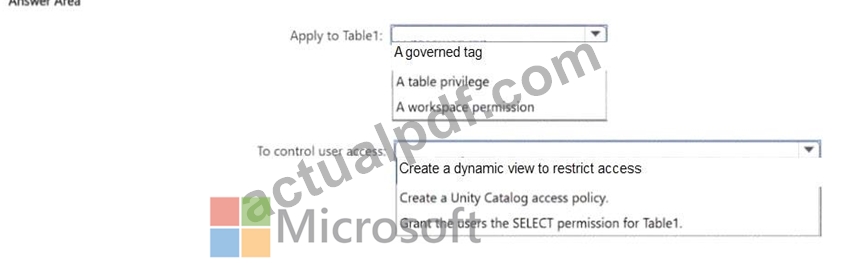
Answer:
Explanation: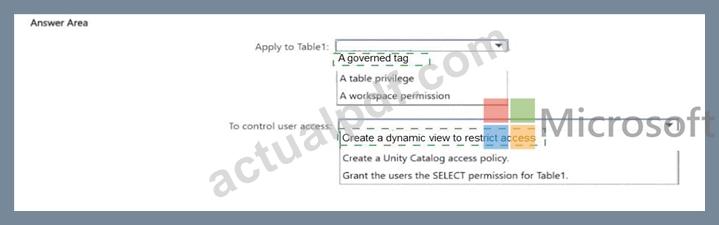
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 45
......
Applying the international recognition third party for payment for DP-750 exam cram, and if you choose us, your money and account safety can be guaranteed. And the third party will protect the interests of you. In addition, DP-750 learning materials are edited and verified by professional experts who possess the professional knowledge for the exam, and the quality can be guaranteed. We are pass guarantee and money back guarantee and if you fail to pass the exam, we will give you full refund. We provide free update for 365 days for DP-750 Exam Materials for you, so that you can know the latest information for the exam, and the update version will be sent to your email automatically.
DP-750 Actual Dumps: https://www.actualpdf.com/DP-750_exam-dumps.html