그리고 Itexamdump Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1FIxDEMhgsRKFdZnC5f-03oNj_4AIR_cg
IT전문가들이 자신만의 경험과 끊임없는 노력으로 만든 최고의Databricks Databricks-Certified-Professional-Data-Engineer학습자료---- Itexamdump의 Databricks Databricks-Certified-Professional-Data-Engineer덤프! Databricks Databricks-Certified-Professional-Data-Engineer덤프로 시험보시면 시험패스는 더는 어려운 일이 아닙니다. 사이트에서 데모를 다운받아 보시면 덤프의 일부분 문제를 먼저 풀어보실수 있습니다.구매후 덤프가 업데이트되면 업데이트버전을 무료로 드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Performance and health monitoring - Setting up alerts and notifications |
| Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
>> Databricks-Certified-Professional-Data-Engineer높은 통과율 덤프문제 <<
Itexamdump에서 제공해드리는 IT인증시험대비 덤프를 사용해보신적이 있으신지요? 만약에 다른 과목을 사용해보신 분이라면 Databricks Databricks-Certified-Professional-Data-Engineer덤프도 바로 구매할것입니다. 첫번째 구매에서 패스하셨다면 덤프에 신뢰가 있을것이고 불합격받으셨다하더라도 바로 환불해드리는 약속을 지켜드렸기때문입니다. 처음으로 저희 사이트에 오신 분이라면Databricks Databricks-Certified-Professional-Data-Engineer덤프로 첫구매에 도전해보지 않으실래요? 저희 덤프로 쉬운 자격증 취득이 가능할것입니다.
질문 # 206
Spill occurs as a result of executing various wide transformations. However, diagnosing spill requires one to proactively look for key indicators.
Where in the Spark UI are two of the primary indicators that a partition is spilling to disk?
정답:D
설명:
In Apache Spark's UI, indicators of data spilling to disk during the execution of wide transformations can be found in the Stage's detail screen and the Query's detail screen. These screens provide detailed metrics about each stage of a Spark job, including information about memory usage and spill data. If a task is spilling data to disk, it indicates that the data being processed exceeds the available memory, causing Spark to spill data to disk to free up memory. This is an important performance metric as excessive spill can significantly slow down the processing.
Reference:
Apache Spark Monitoring and Instrumentation: Spark Monitoring Guide
Spark UI Explained: Spark UI Documentation
질문 # 207
Which of the following SQL statements can replace python variables in Databricks SQL code, when the notebook is set in SQL mode?
1.%python
2.table_name = "sales"
3.schema_name = "bronze"
4.
5.%sql
6.SELECT * FROM ____________________
정답:C
설명:
Explanation
The answer is, SELECT * FROM ${schema_name}.${table_name}
%python
table_name = "sales"
schema_name = "bronze"
%sql
SELECT * FROM ${schema_name}.${table_name}
${python variable} -> Python variables in Databricks SQL code
질문 # 208
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table( " sales " )
result = df.groupBy( " region " ).agg(sum( " revenue " ))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
정답:A
설명:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
질문 # 209
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
정답:C
설명:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay."
* Exact extract: "Records older than the event-time watermark are considered late and may be dropped." References: Structured Streaming watermarking and deduplication; One-time trigger.
질문 # 210
A Delta Lake table was created with the below query: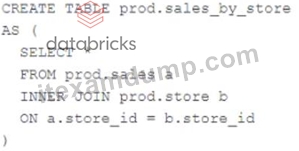
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
정답:B
설명:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. Reference:
https://docs.databricks.com/delta/quick-start.html#drop-a-table
https://docs.databricks.com/delta/delta-batch.html#drop-table
질문 # 211
......
Itexamdump이 바로 아주 좋은Databricks Databricks-Certified-Professional-Data-Engineer인증시험덤프를 제공할 수 있는 사이트입니다. Itexamdump 의 덤프자료는 IT관련지식이 없는 혹은 적은 분들이 고난의도인Databricks Databricks-Certified-Professional-Data-Engineer인증시험을 패스할 수 있습니다. 만약Itexamdump에서 제공하는Databricks Databricks-Certified-Professional-Data-Engineer인증시험덤프를 장바구니에 넣는다면 여러분은 많은 시간과 정신력을 절약하실 수 있습니다. 우리Itexamdump 의Databricks Databricks-Certified-Professional-Data-Engineer인증시험덤프는 Itexamdump전문적으로Databricks Databricks-Certified-Professional-Data-Engineer인증시험대비로 만들어진 최고의 자료입니다.
Databricks-Certified-Professional-Data-Engineer최고품질 인증시험공부자료: https://www.itexamdump.com/Databricks-Certified-Professional-Data-Engineer.html
참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1FIxDEMhgsRKFdZnC5f-03oNj_4AIR_cg