2026 Latest Actual4Labs DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1j-hvvt54Wt-w2YBrP0i5T_r0U6eUONxx
Actual4Labs is the best choice for those in preparation for exams. Many people have gained good grades after using our DP-600 real test, so you will also enjoy the good results. Our free demo of DP-600 training material provides you with the free renewal in one year so that you can keep track of the latest points happening in the world. As the questions of exams of our DP-600 Exam Torrent are more or less involved with heated issues and customers who prepare for the exams must haven’t enough time to keep trace of exams all day long.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
These are expertly designed Microsoft DP-600 mock tests, under the supervision of thousands of professionals. A 24/7 customer service is available for assistance in case of any sort of pinch. It shows results at the end of every Microsoft DP-600 mock test attempt so you don't repeat mistakes in the next try. To confirm the license of the product, you need an active internet connection. Actual4Labs desktop Implementing Analytics Solutions Using Microsoft Fabric (DP-600) Practice Test is compatible with every Windows-based computer. You can use this software without an active internet connection.
NEW QUESTION # 193
Which syntax should you use in a notebook to access the Research division data for Productlinel?




Answer: D
Explanation:
Comprehensive Detailed Explanation
The question asks: Which syntax should you use in a Fabric notebook to access the Research division data for Productline1?
Key Background from the Case
In Productline1ws, a lakehouse named Lakehouse1 is created.
In Lakehouse1, a shortcut is created to storage1, named ResearchProduct.
Storage1 contains the Research division data for Productline1 in Delta format.
Requirement: All data in lakehouses must be presented as managed tables in Lakehouse explorer.
Analyzing the Syntax Options
Option A:
spark.sql("SELECT * FROM Lakehouse1.ResearchProduct")
This syntax directly queries the ResearchProduct shortcut within Lakehouse1 using Spark SQL.
Since the shortcut points to Delta data, Spark can directly query it.
This is the correct way to retrieve Productline1 data from Lakehouse1.
Option B:
spark.sql("SELECT * FROM Lakehouse1.productline1.ResearchProduct")
This introduces an extra schema-like path (productline1) that is not part of the shortcut name.
Incorrect, because the shortcut was created as ResearchProduct inside Lakehouse1, not under another schema.
Option C:
external_table('Tables/ResearchProduct')
external_table is not the correct way to access a Lakehouse shortcut.
Shortcuts in Lakehouses appear as tables and can be queried using Spark SQL directly.
Option D:
spark.sql("SELECT * FROM Lakehouse1.productline1.ResearchProduct")
Same issue as Option B, includes a schema path that does not exist.
Correct Choice
Since the shortcut to ResearchProduct was created inside Lakehouse1, and Spark SQL can query it directly, the correct syntax is:
spark.sql("SELECT * FROM Lakehouse1.ResearchProduct")
That matches Option A.
References
Microsoft Fabric Lakehouse - Shortcuts
Query data in a lakehouse using Spark SQL
Delta format support in Microsoft Fabric
NEW QUESTION # 194
You need to migrate the Research division data for Productline2. The solution must meet the data preparation requirements. How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.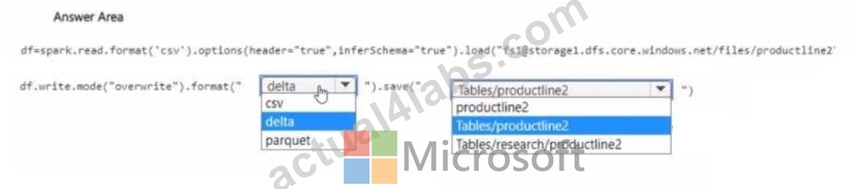
Answer:
Explanation: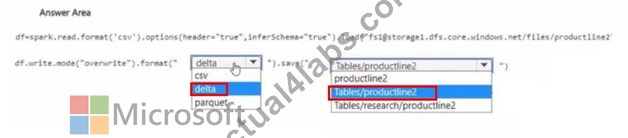
NEW QUESTION # 195
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
Which syntax should you use in a notebook to access the Research division data for Productline1?
Answer: B
Explanation:
A is loading the data from the ResearchProduct table stored in Delta format within the Tables directory of your lakehouse.
NEW QUESTION # 196
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
Hotspot Question
You need to migrate the Research division data for Productline1. The solution must meet the data preparation requirements.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.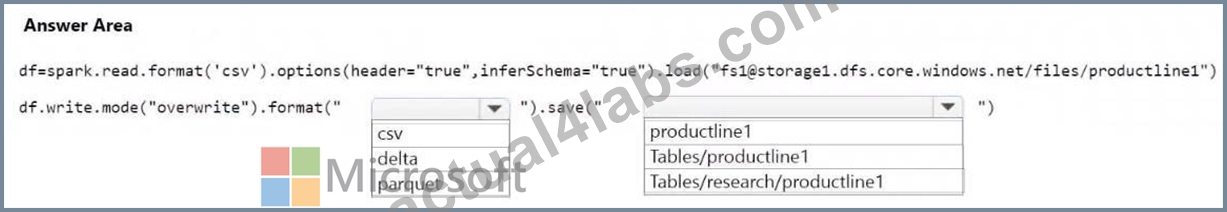
Answer:
Explanation: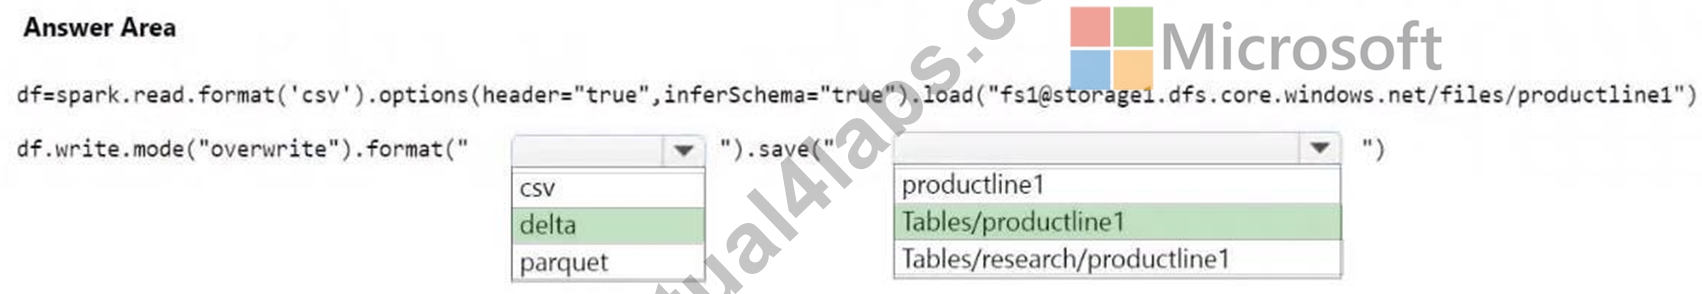
Explanation:
Requirements: Use managed tables.
If you use saveAsTable() you don't need to specify the path "Table/"
If you you save() you specify the full path
NEW QUESTION # 197
You have the source data model shown in the following exhibit.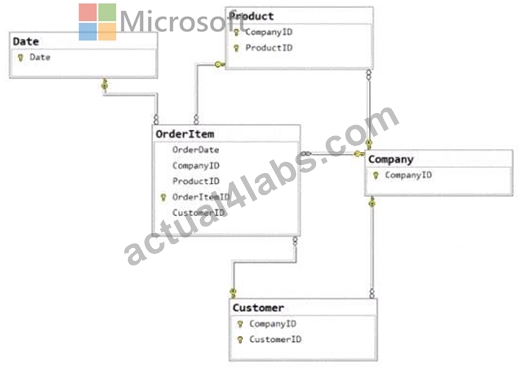
The primary keys of the tables are indicated by a key symbol beside the columns involved in each key.
You need to create a dimensional data model that will enable the analysis of order items by date, product, and customer.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.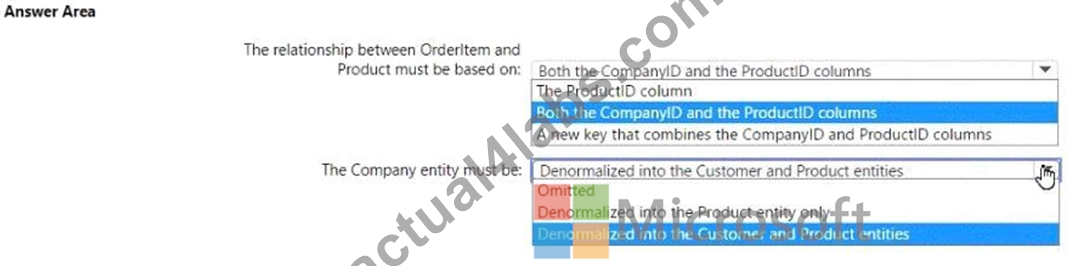
Answer:
Explanation: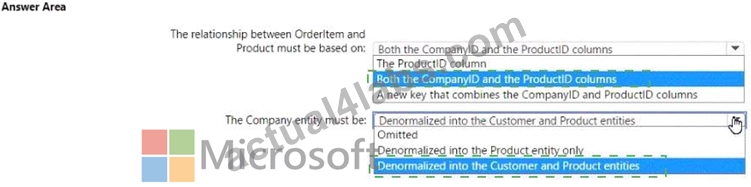
Explanation: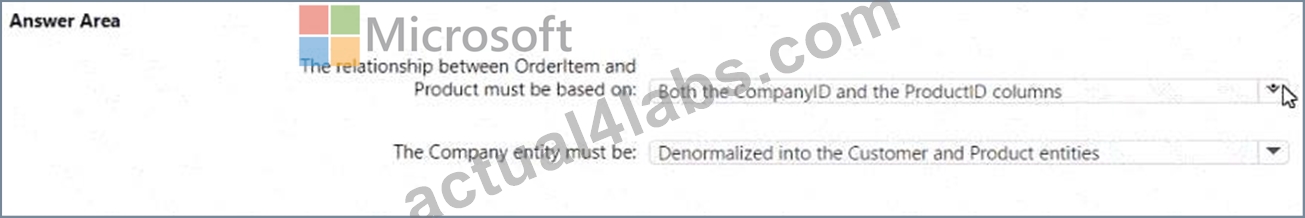
The relationship between OrderItem and Product must be based on: Both the CompanyID and the ProductID columns The Company entity must be: Denormalized into the Customer and Product entities In a dimensional model, the relationships are typically based on foreign key constraints between the fact table (OrderItem) and dimension tables (Product, Customer, Date). Since CompanyID is present in both the OrderItem and Product tables, it acts as a foreign key in the relationship. Similarly, ProductID is a foreign key that relates these two tables. To enable analysis by date, product, and customer, the Company entity would need to be denormalized into the Customer and Product entities to ensure that the relevant company information is available within those dimensions for querying and reporting purposes.
References =
Dimensional modeling
Star schema design
NEW QUESTION # 198
......
We can say that how many the DP-600 certifications you get and obtain qualification certificates, to some extent determines your future employment and development, as a result, the DP-600 exam guide is committed to helping you become a competitive workforce, let you have no trouble back at home. Actually, just think of our DP-600 Test Prep as the best way to pass the DP-600 exam is myopic. They can not only achieve this, but ingeniously help you remember more content at the same time.
DP-600 Test Free: https://www.actual4labs.com/Microsoft/DP-600-actual-exam-dumps.html
2026 Latest Actual4Labs DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1j-hvvt54Wt-w2YBrP0i5T_r0U6eUONxx