Valid Implementing Data Engineering Solutions Using Azure Databricks (DP-750) dumps of PassCollection are reliable because they are original and will help you pass the DP-750 certification test on your first attempt. We are sure that our DP-750 updated questions will enable you to crack the Microsoft DP-750 test in one go. By giving you the knowledge you need to ace the DP-750 Exam in one sitting, our DP-750 exam dumps help you make the most of the time you spend preparing for the test. Download our updated and real Microsoft questions right away rather than delaying.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
>> Free DP-750 Test Questions <<
Nowadays, using electronic DP-750 exam materials to prepare for the exam has become more and more popular, so now, you really should not be restricted to paper materials any more, our electronic Microsoft DP-750 preparation dumps will surprise you with their effectiveness and usefulness. I can assure you that you will pass the exam as well as getting the related DP-750 Certification under the guidance of our DP-750 training materials as easy as pie.
NEW QUESTION # 39
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.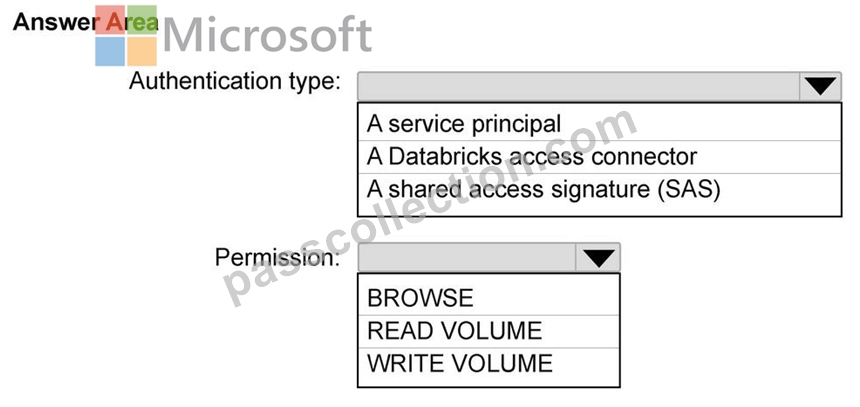
Answer:
Explanation: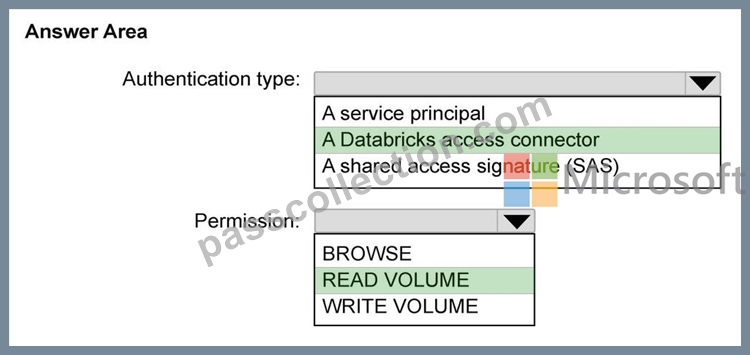
NEW QUESTION # 40
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: B
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: D
Explanation:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn't integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements
* Transaction logs and deleted data files that are older than 90 days must be removed from Delta tables to reclaim storage.
* All the tables must remain available for querying during the cleanup process.
* Administrative effort must be minimized
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.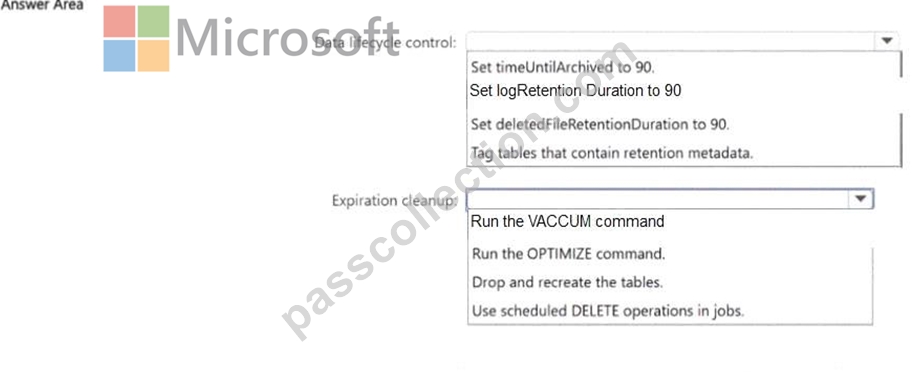
Answer:
Explanation: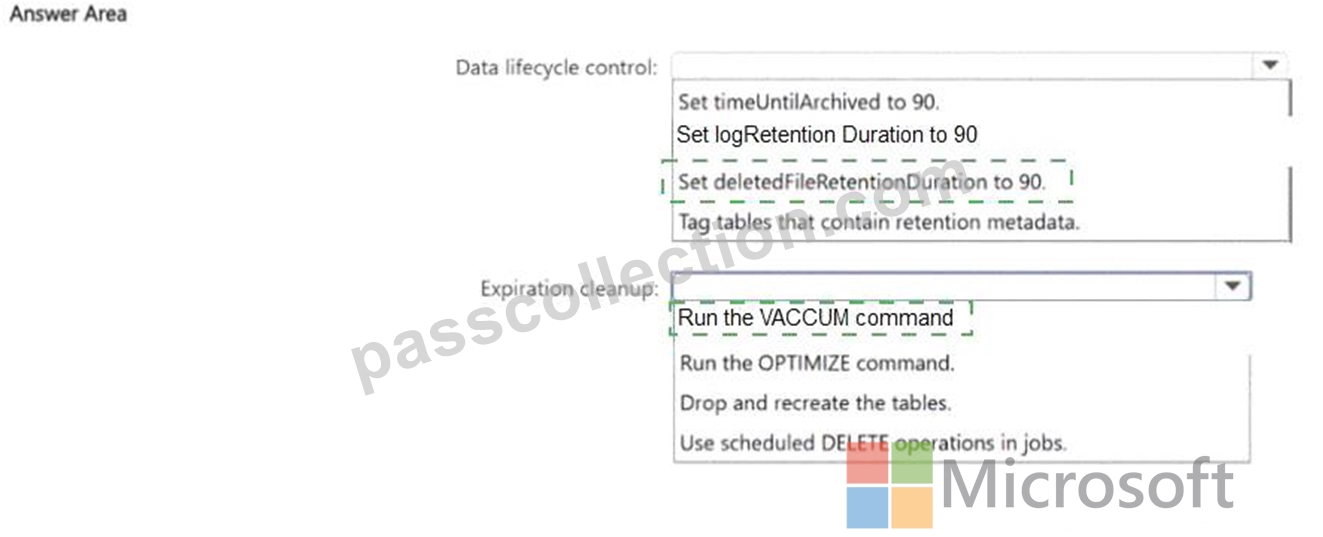
Explanation:
Two actions are needed to reclaim storage while keeping tables queryable:
Set delta.deletedFileRetentionDuration and delta.logRetentionDuration to 90 days on each table. These properties define the retention floor - VACUUM will not touch anything newer than this threshold, so no data needed for time travel within 90 days can be accidentally removed.
Run VACUUM on each table. VACUUM is the Delta Lake command that physically removes data files and transaction log entries older than the retention duration. Importantly, VACUUM runs as a background operation - it uses Delta Lake's MVCC (multi-version concurrency control) to ensure that concurrent reads against the table continue uninterrupted while cleanup happens. Tables are fully available throughout.
OPTIMIZE compacts small files for query performance but doesn't delete anything. Manually deleting files outside the Delta protocol would corrupt the table.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: B
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 44
......
If you visit our website PassCollection, then you will find that our Microsoft DP-750 practice questions are written in three different versions: PDF version, Soft version and APP version. All types of DP-750 Training Questions are priced favorably on your wishes. Obtaining our Microsoft DP-750 study guide in the palm of your hand, you can achieve a higher rate of success.
Relevant DP-750 Questions: https://www.passcollection.com/DP-750_real-exams.html