Laden Sie die neuesten ZertFragen Professional-Machine-Learning-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1_JRxnP--jV5ATAdWAvJxFA3Piq6--gDg
Die Google Professional-Machine-Learning-Engineer Zertifizierung ist eine der hochwertigsten Zertifizierungen zwischen vielfältigen Prüfungen. Dieses Jahrhundert ist die hohe Entwicklungszeit der IT-Industrie. Deshalb können Sie die knappe Kandidaten in der Arbeitswelt. Und wie können wir Google Professional-Machine-Learning-Engineer Prüfungen bestehen? Sie sollen die Lernhilfe zur Google Professional-Machine-Learning-Engineer Zertifizierung von ZertFragen benötigen. Und es ist auch nötig, einen kürzen und leichten Weg zu finden. Und wir ZertFragen sind für Sie vorhanden. Und Wenn Sie ZertFragen auswählen, wählen Sie nämlich den Erfolg. Die Professional-Machine-Learning-Engineer Prüfungsfragen und Testantworten sind von ZertFragen IT-Eliten gesammelt. Und unsere Produkte sind die neuesten und hochqualitativsten.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Scale prototypes into AI models | 18% | - Optimize model performance and generalization - Work with foundation models and generative AI techniques - Design and run experiments - Select appropriate model architectures and frameworks |
| Topic 2: Automate and orchestrate ML pipelines | 18% | - Design end-to-end ML workflows - Implement CI/CD for ML systems - Automate retraining and model updates - Use Vertex AI Pipelines, TFX, and other orchestration tools |
| Topic 3: Train and deploy models | 20% | - Use Vertex AI deployment features and infrastructure - Deploy models for online, batch, and streaming prediction - Configure training jobs and environments - Implement generative AI deployment patterns |
| Topic 4: Architect low-code AI solutions | 12% | - Apply responsible AI principles to low-code designs - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder |
| Topic 5: Monitor and optimize AI solutions | 16% | - Optimize cost, latency, and resource usage - Troubleshoot and maintain production systems - Monitor model performance, fairness, and drift - Monitor data quality and pipeline health |
| Topic 6: Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
>> Professional-Machine-Learning-Engineer Prüfungen <<
Unser ZertFragen setzt sich aus großen Eliteteams zusammen. Wir werden Ihnen die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung schnell und genau bieten und zugleich rechtzeitig die Fragen und Antworten zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung erneuern und bearbeiten. Außerdem verschafft unser ZertFragen in den Zertifizierungsbranchen große Reputation. Obwohl die Chance für das Bestehen der Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung sehr gering ist, versprechen der glaubwürdige ZertFragen Ihnen, dass Sie diese Prüfung trotz geringer Chance bestehen können.
110. Frage
You recently developed a deep learning model using Keras, and now you are experimenting with different training strategies. First, you trained the model using a single GPU, but the training process was too slow.
Next, you distributed the training across 4 GPUs using tf.distribute.MirroredStrategy (with no other changes), but you did not observe a decrease in training time. What should you do?
Antwort: A
Begründung:
* Option A is incorrect because distributing the dataset with
tf.distribute.Strategy.experimental_distribute_dataset is not the most effective way to decrease the training time. This method allows you to distribute your dataset across multiple devices or machines, by creating a tf.data.Dataset instance that can be iterated over in parallel1. However, this option may not improve the training time significantly, as it does not change the amount of data or computation that each device or machine has to process. Moreover, this option may introduce additional overhead or complexity, as it requires you to handle the data sharding, replication, and synchronization across the devices or machines1.
* Option B is incorrect because creating a custom training loop is not the easiest way to decrease the training time. A custom training loop is a way to implement your own logic fortraining your model, by using low-level TensorFlow APIs, such as tf.GradientTape, tf.Variable, or tf.function2. A custom training loop may give you more flexibility and control over the training process, but it also requires more effort and expertise, as you have to write and debug the code for each step of the training loop, such as computing the gradients, applying the optimizer, or updating the metrics2. Moreover, a custom training loop may not improve the training time significantly, as it does not change the amount of data or computation that each device or machine has to process.
* Option C is incorrect because using a TPU with tf.distribute.TPUStrategy is not a valid way to decrease the training time. A TPU (Tensor Processing Unit) is a custom hardware acceleratordesigned for high-performance ML workloads3. A tf.distribute.TPUStrategy is a distribution strategy that allows you to distribute your training across multiple TPUs, by creating a tf.distribute.TPUStrategy instance that can be used with high-level TensorFlow APIs, such as Keras4. However, this option is not feasible, as Vertex AI Training does not support TPUs as accelerators for custom training jobs5. Moreover, this option may require significant code changes, as TPUs have different requirements and limitations than GPUs.
* Option D is correct because increasing the batch size is the best way to decrease the training time. The batch size is a hyperparameter that determines how many samples of data are processed in each iteration of the training loop. Increasing the batch size may reduce the training time, as it reduces the number of iterations needed to train the model, and it allows each device or machine to process more data in parallel. Increasing the batch size is also easy to implement, as it only requires changing a single hyperparameter. However, increasing the batch size may also affect the convergence and the accuracy of the model, so it is important to find the optimal batch size that balances the trade-off between the training time and the model performance.
References:
* tf.distribute.Strategy.experimental_distribute_dataset
* Custom training loop
* TPU overview
* tf.distribute.TPUStrategy
* Vertex AI Training accelerators
* [TPU programming model]
* [Batch size and learning rate]
* [Keras overview]
* [tf.distribute.MirroredStrategy]
* [Vertex AI Training overview]
* [TensorFlow overview]
111. Frage
You are training and deploying updated versions of a regression model with tabular data by using Vertex Al Pipelines. Vertex Al Training Vertex Al Experiments and Vertex Al Endpoints. The model is deployed in a Vertex Al endpoint and your users call the model by using the Vertex Al endpoint. You want to receive an email when the feature data distribution changes significantly, so you can retrigger the training pipeline and deploy an updated version of your model What should you do?
Antwort: A
Begründung:
Prediction drift is the change in the distribution of feature values or labels over time. It can affect the performance and accuracy of the model, and may require retraining or redeploying the model. Vertex AI Model Monitoring allows you to monitor prediction drift on your deployed models and endpoints, and set up alerts and notifications when the drift exceeds a certain threshold. You can specify an email address to receive the notifications, and use the information to retrigger the training pipeline and deploy an updated version of your model. This is the most direct and convenient way to achieve your goal. Reference:
Vertex AI Model Monitoring
Monitoring prediction drift
Setting up alerts and notifications
112. Frage
You have deployed a model on Vertex AI for real-time inference. During an online prediction request, you get an "Out of Memory" error. What should you do?
Antwort: A
Begründung:
Option A is incorrect because using batch prediction mode instead of online mode does not solve the "Out of Memory" error, but rather changes the latency and throughput of the prediction service. Batch prediction mode is suitable for large-scale, asynchronous, and non-urgent predictions, while online prediction mode is suitable for low-latency, synchronous, and real-time predictions1.
Option B is correct because sending the request again with a smaller batch of instances can reduce the memory consumption of the prediction service and avoid the "Out of Memory" error. The batch size is the number of instances that are processed together in one request. A smaller batch size means less data to load into memory at once2.
Option C is incorrect because using base64 to encode your data before using it for prediction does not reduce the memory consumption of the prediction service, but rather increases it. Base64 encoding is a way of representing binary data as ASCII characters, which increases the size of the data by about 33%3. Base64 encoding is only required for certain data types, such as images and audio, that cannot be represented as JSON or CSV4.
Option D is incorrect because applying for a quota increase for the number of prediction requests does not solve the "Out of Memory" error, but rather increases the number of requests that can be sent to the prediction service per day. Quotas are limits on the usage of Google Cloud resources, such as CPU, memory, disk, and network5. Quotas do not affect the performance of the prediction service, but rather the availability and cost of the service.
Reference:
Choosing between online and batch prediction
Online prediction input data
Base64 encoding
Preparing data for prediction
Quotas and limits
113. Frage
You work for a company that captures live video footage of checkout areas in their retail stores.
You need to use the live video footage to build a model to detect the number of customers waiting for service in near real time. You want to implement a solution quickly and with minimal effort.
How should you build the model?
Antwort: A
114. Frage
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?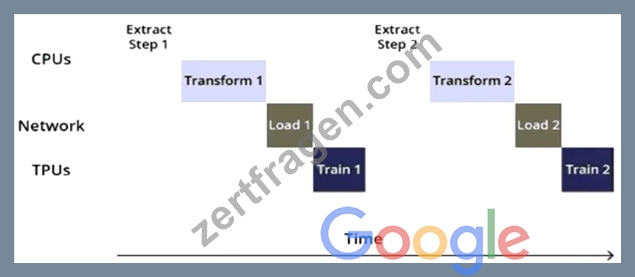
Antwort: D
115. Frage
......
Die Forschungsmaterialien haben gezeigt, dass es schwierig ist, die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung zu bestehen. Unser ZertFragen hat erfahrungsreiche IT-Experten, die durch harte Arbeit die neuesten Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bearbeitet haben. Unser ZertFragen hat die besten Ressourcen, die Ihnen beim Bestehen der Google Professional-Machine-Learning-Engineer Prüfung helfen. Sie enthalten sowohl Fragen, als auch Antworten. Sie brauchen sich nicht so viel Mühe dafür auszugeben und können trotzdem eine hohe Note in der Prüfung bekommen. Wählen Sie doch die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung, die Ihnen sehr helfen können.
Professional-Machine-Learning-Engineer Deutsch Prüfungsfragen: https://www.zertfragen.com/Professional-Machine-Learning-Engineer_prufung.html
P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ZertFragen verfügbar: https://drive.google.com/open?id=1_JRxnP--jV5ATAdWAvJxFA3Piq6--gDg