The time and energy are all very important for the office workers. In order to get the AI-200 certification with the less time and energy investment, you need a useful and valid AI-200 study material for your preparation. AI-200 free download pdf will be the right material you find. The comprehensive contents of AI-200 practice torrent can satisfied your needs and help you solve the problem in the actual test easily. Now, choose our AI-200 study practice, you will get high scores.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Topic 2: Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Topic 3: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 4: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
If you are sure that you want to be better, then you must start taking some measures. Selecting AI-200 practice prep may be your key step. If you are determined to pass the exam, our AI-200 study materials can provide you with everything you need. You can have the AI-200 Learning Materials, study plans and necessary supervision you need. You will have no reason to stop halfway until you get success.
NEW QUESTION # 72
You are developing an Azure Function that calls external APIs by providing an access token for the API. The access token is stored in a secret named token in an Azure Key Vault named mykeyvault.
You need to ensure the Azure Function can access the token. Which value should you store in the Azure Functions app configuration?
Answer: C
NEW QUESTION # 73
Drag and Drop Question
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.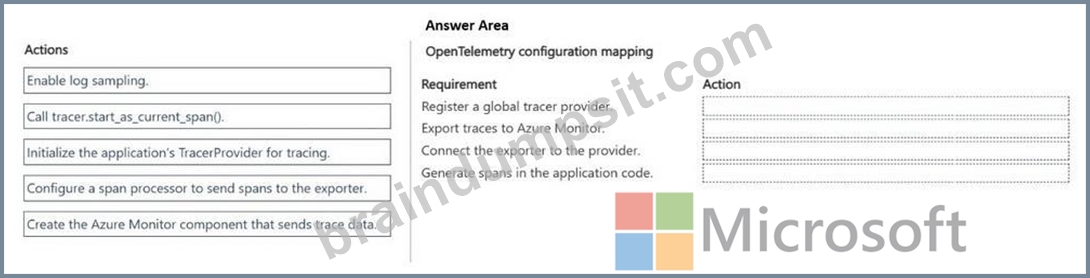
Answer:
Explanation: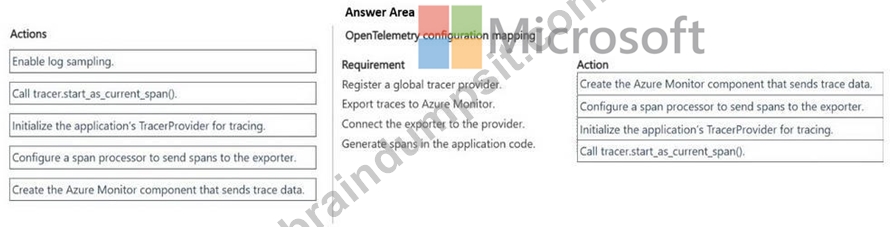
Explanation:
Box 1: Create the Azure Monitor component that sends trace data
To register a global TracerProvider in OpenTelemetry, you must call the SetTracerProvider method on the global tracer provider object, passing in your fully configured TracerProvider instance.
Box 2: Configure a span processor to send spans to the exporter
To export OpenTelemetry traces to Azure Monitor using the Python SDK, you must configure a span processor (such as BatchExportSpanProcessor), pass your initialized Azure Monitor trace exporter to it, and register that span processor with your global tracer provider.
Box 3: Initialize the application's TracerProvider for tracing
Box 4: Call tracer.start_as_current_span()
Acquire your tracer and create spans. Example code (continued from box 2 above):
tracer = trace.get_tracer(__name__)
with tracer.start_as_current_span("hello-aca-span")
Reference:
https://learn.microsoft.com/en-us/azure/durable-task/sdks/durable-task-scheduler-opentelemetry-tracing
https://learn.microsoft.com/en-us/python/api/overview/azure/monitor-opentelemetry-exporter-readme
NEW QUESTION # 74
You are developing an AI search API that caches semantic search results in Redis.
Search results must remain cached for 10 minutes. If the underlying data changes, cached entries must NOT be returned.
You need to implement a cache-aside strategy to ensure data consistency.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Delete keys on mutation. Implement an event-driven or database-hook system to purge related Redis keys the moment the source data updates.
Use absolute expiration. Set a strict, un-extendable Time-To-Live (TTL) of 10 minutes when writing to the cache, ensuring the data naturally expires even if a deletion event is missed.
Incorrect:
[Not C]
Implementing a sliding expiration is not a good step for this specific architecture because it violates the requirement that entries must not be returned if the underlying data changes.
Reference:
https://medium.com/real-world-net/net-caching-strategies-compared-redis-vs-memory-vs-hybrid-b8b8be1e708d
NEW QUESTION # 75
Drag and Drop Question
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data.
The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account.
The application must perform the following tasks:
- Initialize the connection by using the account endpoint and key.
- Define shared throughput.
- Perform create, read, update, and delete (CRUD) operations on items
stored in a container.
You need to implement the SDK components required for the application to access and manage data in Azure Cosmos DB for NoSQL.
Which SDK components should you use? To answer, move the appropriate components to the correct requirements. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.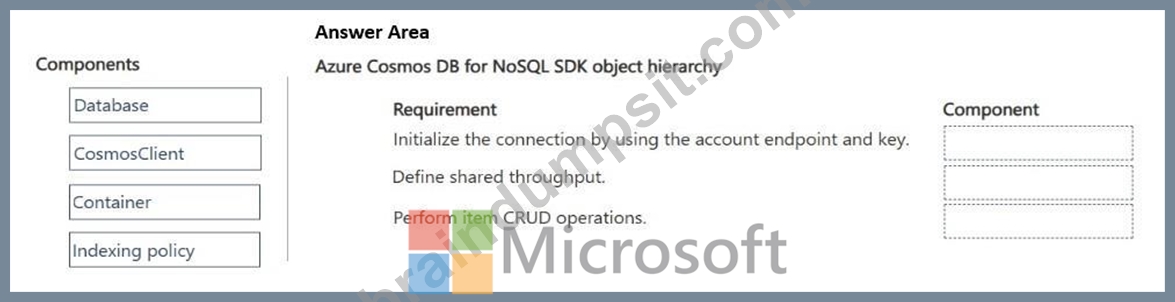
Answer:
Explanation: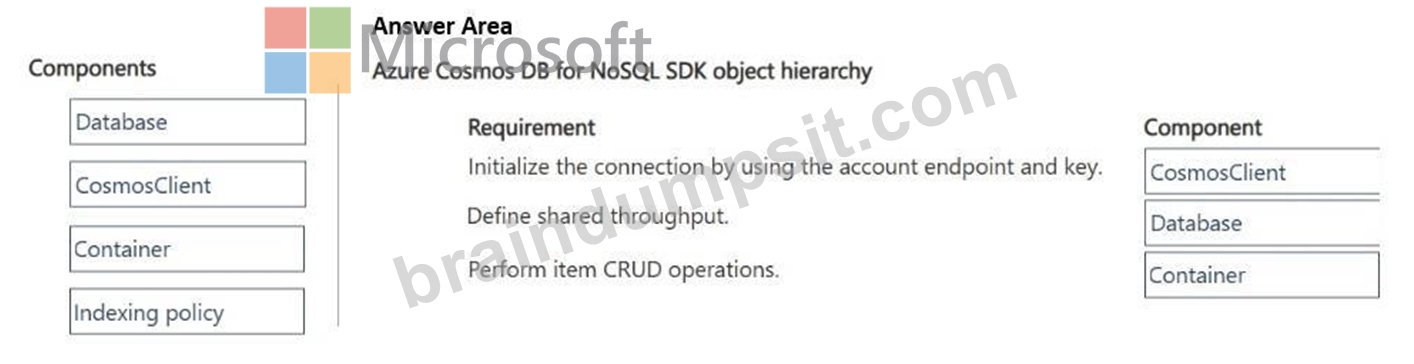
Explanation:
Box 1: CosmosClient
To initialize the connection to an Azure Cosmos DB for NoSQL account using the account endpoint and key, you must use the CosmosClient class.
Box 2: Database
The database SDK component should be used to define shared throughput.
In Azure Cosmos DB, shared throughput (provisioned Request Units per second or RU/s) is configured at the database level. When throughput is provisioned on a database, that capacity is shared among all the containers created within that specific database.
Box 3: Container
To perform item create, read, update, and delete (CRUD) operations, you should use the Container SDK component In the Azure Cosmos DB for NoSQL SDK for .NET, individual JSON documents (items) live inside a container. The Container class exposes the specific methods required to execute CRUD operations on these items.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/how-to-dotnet-get-started
NEW QUESTION # 76
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule. You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Detailed Explanation: A KEDA custom scale rule must identify what scaler to use and which resource within that scaler should be observed. For Azure Storage queues, the trigger type selects the Storage Queue scaler and the queue name identifies the specific queue whose message count drives scaling. Polling interval and maximum replicas are general scaling controls, but they do not define the required queue-specific trigger.
Therefore trigger type and queue name are the essential rule values tested here.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Set scaling rules in Azure Container Apps
NEW QUESTION # 77
......
If you really want to get an international certificate, AI-200 training quiz is really your best choice. Of course. AI-200 preparation materials are global products that have been tested by users worldwide. You can be absolutely assured about the quality of the AI-200 training quiz. Our company has hired the most professional team of experts at all costs to ensure that the content of AI-200 guide questions is the most valuable. you really must get international certification!
AI-200 Vce Free: https://www.braindumpsit.com/AI-200_real-exam.html