If you are also planning to take the AI-200 practice test and don't know where to get real AI-200 exam questions, then you are at the right place. CramPDF is offering the actual AI-200 Questions that can help you get ready for the examination in a short time. These AI-200 Practice Tests are collected by our team of experts. It has ensured that our questions are genuine and updated. We guarantee that you will be satisfied with the quality of our Developing AI Cloud Solutions on Azure (AI-200) practice questions.
| Section | Objectives |
|---|---|
| Topic 1: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 4: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
Before you really attend the AI-200 exam and choose your materials, we want to remind you of the importance of holding a certificate like this one. Obtaining a AI-200 certificate likes this one can help you master a lot of agreeable outcomes in the future, like higher salary, the opportunities to promotion and being trusted by the superiors and colleagues. All these agreeable outcomes are no longer dreams for you. And with the aid of our AI-200 Exam Preparation to improve your grade and change your states of life and get amazing changes in career, everything is possible. It all starts from our AI-200 learning questions.
NEW QUESTION # 13
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
Answer: A
Explanation:
TTL (Time-To-Live) with a fixed duration of five minutes is the exact Redis feature you need to purge AI-generated summaries regardless of access frequency.
Redis TTL and Expiration Features
Core Expiration Feature
EXPIRE command: Sets a timeout in seconds on a key. Use EXPIRE key 300 to remove the summary after 300 seconds (five minutes).
PX command: Sets a timeout in milliseconds. Use PX key 300000 for precise millisecond control.
EXPIREAT / PEXPIREAT: Sets an absolute Unix timestamp for expiration instead of a relative duration.
Reference:
https://dev.to/truongpx396/30-common-redis-interview-questions-1ai
NEW QUESTION # 14
You need to implement trace correlation according to the business requirements.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you se lect.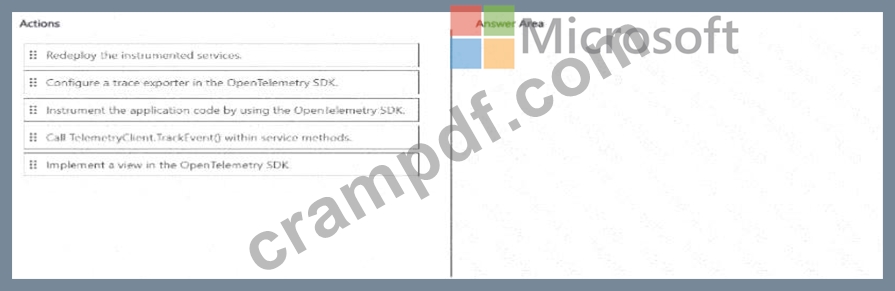
Answer:
Explanation: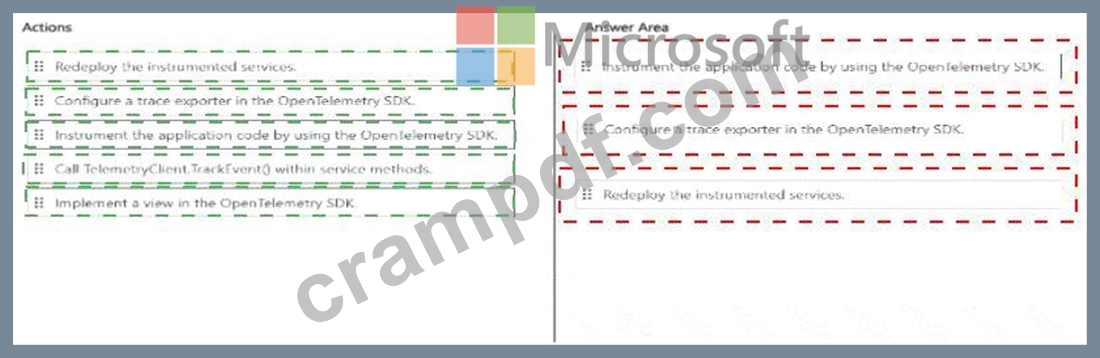
Explanation: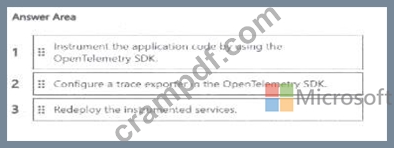
Verified answer: 1) Instrument the application code with the OpenTelemetry SDK; 2) configure an Azure Monitor trace exporter in the OpenTelemetry SDK; 3) redeploy the instrumented services.
Detailed Explanation: Trace correlation requires the application to create OpenTelemetry spans and an exporter to send those spans to Azure Monitor. Instrumentation must therefore be present before the updated service is deployed. The previous Application Insights SDK instrumentation does not satisfy the case-study requirement that all tracing use OpenTelemetry. Configuring an OpenTelemetry view is unrelated to basic distributed-trace export, and calling TrackEvent is an Application Insights SDK pattern rather than the required OpenTelemetry approach.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 15
Drag and Drop Question
You are deploying an Azure Function app that retrieves secrets from Key Vault by using a managed identity.
The deployment must ensure that identity and secret configuration are in place before the function code is deployed.
You need to deploy the function app securely.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.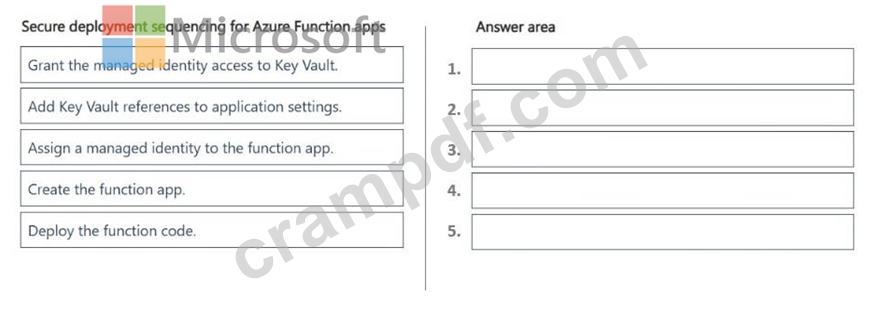
Answer:
Explanation: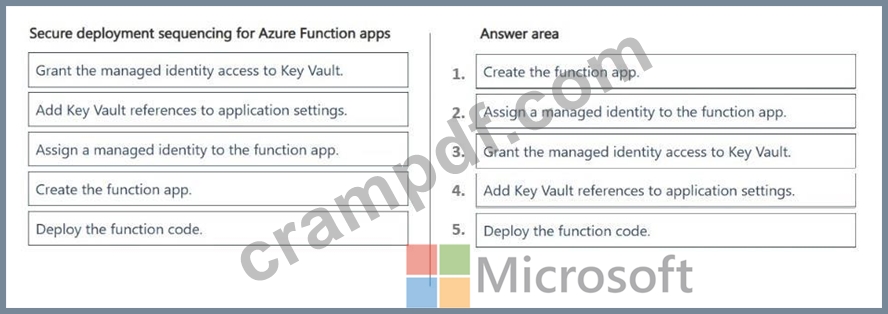
Explanation:
Step 1: Create the function app
You must first provision the underlying Azure Functions infrastructure before you can bind an identity or configuration settings to it.
Step 2: Assign a managed identity to the function app
Turning on the managed identity (such as a system-assigned identity) creates a distinct security principal in Microsoft Entra ID for the resource.
Step 3: Grant access to Key Vault
Use the managed identity's principal ID to create an access policy or RBAC role assignment in Key Vault, allowing the app to read secrets.
Step 4: Add Key Vault references to application settings.
Configure the Function App's application settings to point to the Key Vault secret URIs (@Microsoft.KeyVault(...)), which can now be securely resolved by the identity.
Step 5: Deploy the function code
Finally, deploy the application code. This ensures that when the code initializes and executes, all environment variables and secrets are already active and accessible, preventing application startup failures.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 16
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure Azure Functions to generate vector embeddings according to planned environment application architecture.
Which trigger type should you use?
Answer: B
Explanation:
The most appropriate trigger type for this architecture is the Azure Cosmos DB Trigger.
This trigger monitors your NoSQL container's underlying change feed. When a document is created or modified, the function fires automatically, processes the data, generates the embedding, and places a message in Azure Service Bus.
Scenario, Planned Application Architecture
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/integrated-embeddings
NEW QUESTION # 17
Drag and Drop Question
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.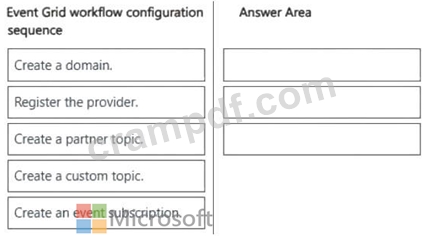
Answer:
Explanation: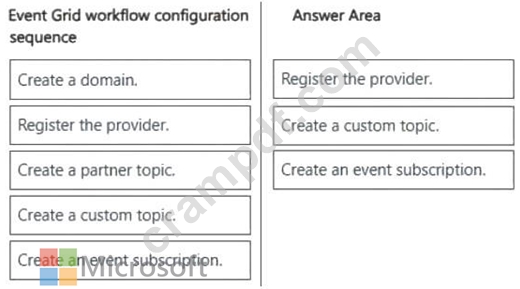
Explanation:
Step 1: Register a provider
Because this is a newly provisioned Azure subscription, you must register the Microsoft.EventGrid resource provider before you can deploy any Event Grid components.
Step 2: Create a custom topic
Since you are routing AI inference events originating from your application, you need to create a custom topic to act as the endpoint where these events are sent.
Step 3: Create an event subscription
You must create an event subscription to define the routing rules. This is where you configure filtering to ensure only high-confidence events are directed to your downstream processor.
Reference:
https://www.c-sharpcorner.com/article/building-event-driven-ai-workflows-with-azure-event-grid-and-net/
NEW QUESTION # 18
......
You can use AI-200 guide materials through a variety of electronic devices. At home, you can use the computer and outside you can also use the phone. Now that more people are using mobile phones to learn our AI-200 study guide, you can also choose the one you like. We have three versions of our AI-200 Exam Braindumps: the PDF, the Software and the APP online. And you can free download the demo s to check it out.
AI-200 Exam Fees: https://www.crampdf.com/AI-200-exam-prep-dumps.html