2026 Latest GuideTorrent AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1kz2IJMEohAsnVE2gpNZ8ViY5W2lJrNfO
Passing an Operationalizing Machine Learning and Generative AI Solutions exam on the first attempt can be stressful, but Microsoft AI-300 exam questions can help manage stress and allow you to perform at your best. We at GuideTorrent give you the techniques and resources to make sure you get the most out of your exam study. We provide preparation material for the Operationalizing Machine Learning and Generative AI Solutions exam that will guide you when you sit to study for it. AI-300 updated questions give you enough confidence to sit for the Microsoft exam.
| Section | Objectives |
|---|---|
| Topic 1: Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Topic 2: Implement secure and scalable AI systems | - Security and governance
|
| Topic 3: Operationalizing machine learning solutions | - Deployment and monitoring
|
| Topic 4: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
Similarly, the GuideTorrent Microsoft AI-300 practice test creates an actual exam scenario on each and every step so that you may be well prepared before your actual Operationalizing Machine Learning and Generative AI Solutions examination time. Hence, it saves you time and money. GuideTorrent provides three months of free updates if you purchase the Microsoft AI-300 Questions and the content of the examination changes after that.
NEW QUESTION # 138
A data science team plans to evaluate multiple hyperparameter values automatically while training a model in Azure Machine Learning.
The tuning process must run multiple training trials without manually modifying the training script for each run.
You need to automate hyperparameter tuning for the training job.
What should you do?
Answer: B
Explanation:
Correct:
* Create a tuning job that runs multiple trials with different parameter values To best automate hyperparameter tuning in Azure Machine Learning, you should create a Sweep Job (in SDK v2) or a HyperDrive experiment (in SDK v1).
This creates a tuning job that automatically launches multiple training trials (child runs) using your single base training script without requiring manual code modifications for each run.
Key Components to Automate the Job
To set up this job successfully using the Azure Machine Learning Python SDK v2, you will define:
Parameterized Training Script: Write your code to accept hyperparameters as command-line arguments (e.g., using Python's argparse), allowing the tuning job to pass different values to each trial.
Search Space: Define the range or specific discrete/continuous choices for the values you want to test (e.g., learning rates, batch sizes).Sampling Algorithm: Choose how Azure ML should navigate your search space. Options include Random sampling, Grid sampling (testing every possible combination), or Bayesian sampling (using previous trial results to pick the next best values).Primary Metric: Specify the performance metric your script logs (like accuracy or loss) so Azure ML knows which target to optimize.
Early Termination Policy: Optional policy (like a Bandit Policy) to automatically cancel poorly performing trials early, saving you compute time and cost.
Incorrect:
* Adjust hyperparameters after model deployment.
* Duplicate the training script for each parameter combination.
* Manually change hyperparameter values between training runs.
* Run a single training job with fixed hyperparameters.
* Select hyperparameters based only on default model settings.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.hyperdrive
NEW QUESTION # 139
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
- Queries that include exact policy identifiers must return matching
documents even when semantic similarity is low.
- Natural-language questions must prioritize semantically relevant
documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.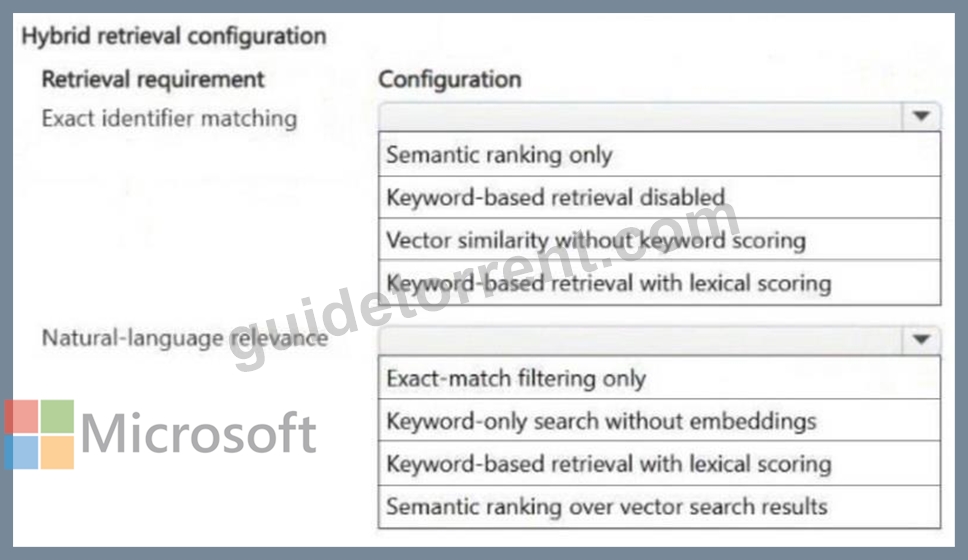
Answer:
Explanation: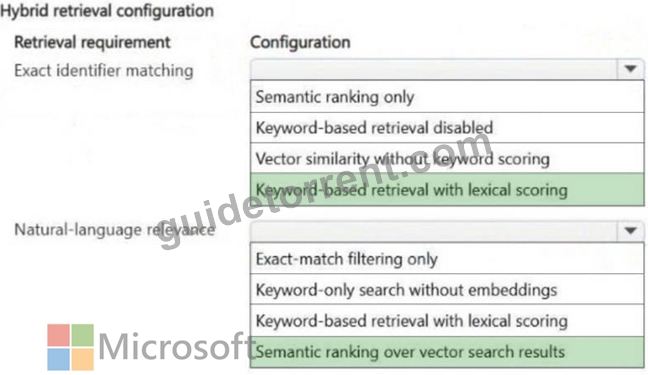
NEW QUESTION # 140
-
You complete the fine-tuning of a generative model in Microsoft Foundry. The fine-tuned model now appears as a new model variant in your development environment.
The deployment process must ensure that proper validation and control is maintained.
You need to promote the fine-tuned model from development to production.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.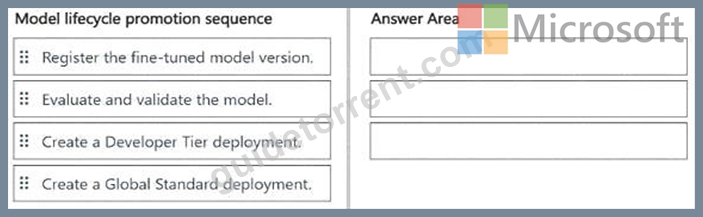
Answer:
Explanation: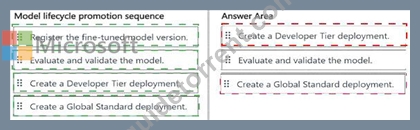
Explanation:
Correct sequence:
* Create a Developer Tier deployment.
* Evaluate and validate the model.
* Create a Global Standard deployment.
The fine-tuned model should first be deployed using the Developer Tier because Microsoft specifically positions this deployment type for fine-tuned model candidate evaluation rather than production use .
Developer Tier deployments provide a cost-efficient environment for testing custom models and do not provide a production SLA.
After deployment, the model should be evaluated and validated . Microsoft Foundry supports running the model through the playground and the Evaluations service to assess the deployed candidate against expected quality, safety, and task-performance criteria. Microsoft explicitly documents that evaluations can be executed against a deployed fine-tuned model candidate and compared with other model versions.
Only after the candidate satisfies the required validation criteria should it be promoted to a Global Standard deployment for production inference. Global Standard is designed for general production workloads and provides substantially more appropriate production characteristics than Developer Tier.
Register the fine-tuned model version is the distractor here. The scenario already states that fine-tuning is complete and the resulting model variant exists in Microsoft Foundry; the required promotion workflow is therefore test deployment # validation # production deployment .
Study Guide Reference: Implement machine learning model lifecycle and operations - fine-tuned model evaluation, controlled promotion, Developer Tier deployments, production deployment, and model lifecycle governance.
NEW QUESTION # 141
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Configure Azure Monitor to collect logs from the workspace. Use the logs to perform prompt evaluation.
Does the solution meet the goal?
Answer: A
Explanation:
Azure Monitor is valuable for production observability , but it is not the appropriate mechanism for the stated development-time requirement: manually inspecting individual prompt-flow executions and comparing prompt variants with their inputs, outputs, token consumption, and latency.
Prompt flow provides purpose-built run outputs and tracing . Microsoft documents that after a flow execution, the Outputs experience exposes detailed flow inputs and outputs. When tracing is enabled, the Trace view provides execution duration and token information and lets the developer expand individual steps to inspect their inputs and execution details.
Prompt flow also directly supports variants and batch/evaluation runs. Multiple variants can be executed and compared, while the run details expose per-test-case inputs, outputs, token counts, duration, and evaluation results. Microsoft explicitly states that multiple runs can be selected to compare their metrics and outputs.
Azure Monitor/Application Insights can collect operational metrics such as token consumption and flow or node latency for deployed applications, but that telemetry is primarily intended for monitoring and troubleshooting rather than the interactive prompt-variant evaluation workflow described here.
Therefore, the proposed solution does not meet the goal .
Study Guide Reference: Implement generative AI quality assurance and observability - prompt evaluation, tracing, debugging, token consumption, latency, and prompt-variant comparison.
NEW QUESTION # 142
Hotspot Question
You download a .csv file from a notebook in an Azure Machine Learning workspace to a data/sample.csv folder on a compute instance. The file contains 10,000 records.
You must generate the summary statistics for the data in the file. The statistics must include the following for each numerical column:
- number of non-empty values
- average value
- standard deviation
- minimum and maximum values
- 25th, 50th, and 75th percentiles
You need to complete the Python code that will generate the summary statistics.
Which code segments should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.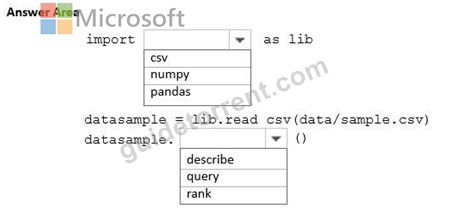
Answer:
Explanation: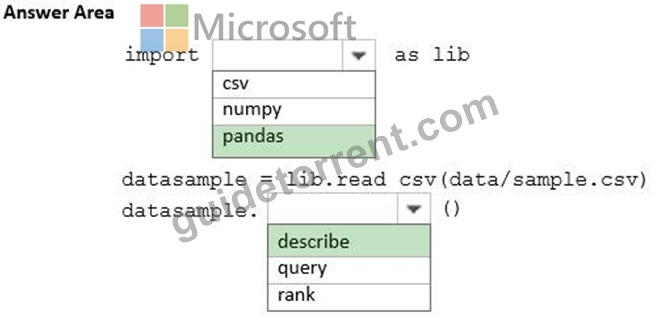
Explanation:
Box 1: pandas
Pandas read_csv() - How to read a csv file in Python
Most of the data is available in a tabular format of CSV files. It is very popular. You can convert them to a pandas DataFrame using the read_csv function. The pandas.read_csv is used to load a CSV file as a pandas dataframe.
Step 1: pandas
import pandas as pd
Step 2: Read the CSV
# Read the csv file
df = pd.read_csv("data1.csv")
Box 2: describe
The pandas.describe function is used to get a descriptive statistics summary of a given dataframe. This includes mean, count, std deviation, percentiles, and min-max values of all the features.
Pandas Describe function on DataFrame
On applying pandas describe function to a dataframe, the result is also returned as a dataframe .
This dataframe will consist of a statistics summary for all the numeric features of the dataframe.
# Create a dataframe
df = pd.DataFrame({
'Subject_1_Marks': [14, 42, 21, 12, 45],
'Subject_2_Marks': [32, 43, 23, 50, 21],
'Subject_3_Marks': [45.0, 34.0, 23.0, 8.0, 21.0],
'Names': ['Saksham', 'Ayushi', 'Abhishek', 'Saksham', 'Saumya']
}
)
# Apply describe function
df.describe()
Incorrect:
* rank
Reference:
https://www.machinelearningplus.com/pandas/pandas-read_csv-completed/
https://www.machinelearningplus.com/pandas/pandas-describe/
NEW QUESTION # 143
......
Our online test engine and windows software of the AI-300 test answers will let your experience the flexible learning style. Apart from basic knowledge, we have made use of the newest technology to enrich your study of the AI-300 exam study materials. Online learning platform is different from traditional learning methods. One of the great advantages is that you will soon get a feedback after you finish the exercises. So you are able to adjust your learning plan of the AI-300 Guide test flexibly. We hope that our new design can make study more interesting and colorful. You also can send us good suggestions about developing the study material.
Regualer AI-300 Update: https://www.guidetorrent.com/AI-300-pdf-free-download.html
BONUS!!! Download part of GuideTorrent AI-300 dumps for free: https://drive.google.com/open?id=1kz2IJMEohAsnVE2gpNZ8ViY5W2lJrNfO