Databricks Certified-Data-Engineer-Professional Training Kit, Certified-Data-Engineer-Professional Reliable Exam Sample

There is no shortcut to Databricks Certified-Data-Engineer-Professional exam questions success except hard work. You cannot expect your dream of earning the Databricks Certified Data Engineer Professional CERTIFICATION EXAM come true without using updated study material Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions. Success in the Certified-Data-Engineer-Professional exam adds more value to your resume and helps you land the best jobs in the industry.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
|
| Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
>> Databricks Certified-Data-Engineer-Professional Training Kit <<
Newest Certified-Data-Engineer-Professional Training Kit & Passing Certified-Data-Engineer-Professional Exam is No More a Challenging Task
In order to pass Databricks Certification Certified-Data-Engineer-Professional Exam disposably, you must have a good preparation and a complete knowledge structure. Actual4test can provide you the resources to meet your need.
Databricks Certified Data Engineer Professional Sample Questions (Q110-Q115):
NEW QUESTION # 110
Which statement describes Delta Lake Auto Compaction?
- A. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- D. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- E. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 111
A table is registered with the following code:
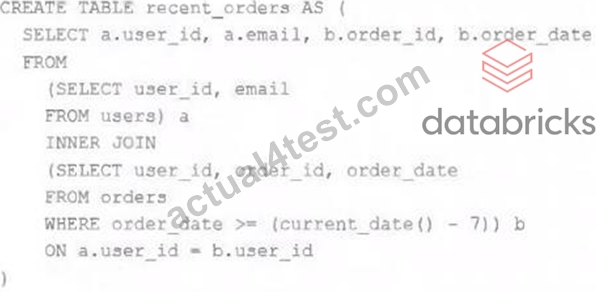
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
- A. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
- E. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
Answer: B
Explanation:
Table is created and data of join will be stored on DBFS and it will be returned on query time.
NEW QUESTION # 112
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
- B. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- C. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- D. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
Answer: B
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
NEW QUESTION # 113
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team. The analytics team wants to use the table with another tool that requires Apache Iceberg format. What should the data engineer do?
- A. Create an Iceberg copy of the transactions Delta table which can be used by the analytics team.
- B. Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table.
- C. Require the analytics team to use a tool that supports Delta table.
- D. Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table.
Answer: B
Explanation:
Delta Lake introduced Delta Universal Format (Delta UniForm), which allows seamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can be converted into an Iceberg table while maintaining Delta capabilities.
NEW QUESTION # 114
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
- A. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect("valid_customer", "customer_id IS NOT NULL")
.expect("valid_amount", "amount > 0")
) - B. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
.expect_or_drop("valid_amount", "amount > 0")
) - C. @dlt.table
@dlt.expect("valid_customer", "customer_id IS NOT NULL")
@dlt.expect("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - D. @dlt.table
@dlt.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
@dlt.expect_or_drop("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders")
Answer: B
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 115
......
The Databricks PDF Questions format designed by the Actual4test will facilitate its consumers. Its portability helps you carry on with the study anywhere because it functions on all smart devices. You can also make notes or print out the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) pdf questions. The simple, systematic, and user-friendly Interface of the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) PDF dumps format will make your preparation convenient.
Certified-Data-Engineer-Professional Reliable Exam Sample: https://www.actual4test.com/Certified-Data-Engineer-Professional_examcollection.html
- Free PDF 2026 Databricks Professional Certified-Data-Engineer-Professional Training Kit 🎐 Copy URL ☀ www.pdfdumps.com ️☀️ open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🦅Clear Certified-Data-Engineer-Professional Exam
- 100% Pass Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Reliable Training Kit 😑 Enter ➠ www.pdfvce.com 🠰 and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free ⚛Reliable Certified-Data-Engineer-Professional Braindumps Questions
- 2026 Latest Certified-Data-Engineer-Professional – 100% Free Training Kit | Databricks Certified Data Engineer Professional Reliable Exam Sample 💯 Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free immediately on 《 www.prep4away.com 》 🐧Certified-Data-Engineer-Professional Valid Exam Tips
- Certified-Data-Engineer-Professional Test-king File - Certified-Data-Engineer-Professional Practice Materials - Certified-Data-Engineer-Professional Test Questions 🈺 ▛ www.pdfvce.com ▟ is best website to obtain { Certified-Data-Engineer-Professional } for free download 🦓Clear Certified-Data-Engineer-Professional Exam
- 100% Pass Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Reliable Training Kit 🐎 Simply search for ➽ Certified-Data-Engineer-Professional 🢪 for free download on ➥ www.examcollectionpass.com 🡄 🤲Certified-Data-Engineer-Professional Pdf Torrent
- 2026 Certified-Data-Engineer-Professional Training Kit - First-grade Databricks Certified-Data-Engineer-Professional Reliable Exam Sample 100% Pass 💹 Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ▷ www.pdfvce.com ◁ 🦂Practice Certified-Data-Engineer-Professional Exam Pdf
- Real Certified-Data-Engineer-Professional Dumps ⏬ Reliable Certified-Data-Engineer-Professional Braindumps Questions 😈 Certified-Data-Engineer-Professional PDF Question ⏩ Download { Certified-Data-Engineer-Professional } for free by simply searching on 《 www.troytecdumps.com 》 📨Certified-Data-Engineer-Professional Valid Exam Tips
- Real Certified-Data-Engineer-Professional Dumps ✅ Valid Certified-Data-Engineer-Professional Exam Test ⏮ Reliable Certified-Data-Engineer-Professional Braindumps Questions 😭 Simply search for “ Certified-Data-Engineer-Professional ” for free download on ( www.pdfvce.com ) 🤗Testing Certified-Data-Engineer-Professional Center
- 100% Pass Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Reliable Training Kit 👵 Easily obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download through ⏩ www.prepawayexam.com ⏪ 🦇Testing Certified-Data-Engineer-Professional Center
- Dump Certified-Data-Engineer-Professional Torrent 🤓 Certified-Data-Engineer-Professional Latest Exam Online 🚤 Certified-Data-Engineer-Professional Valid Test Testking 😿 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ on ☀ www.pdfvce.com ️☀️ immediately to obtain a free download ✨Certified-Data-Engineer-Professional Exam Learning
- Valid Certified-Data-Engineer-Professional Cram Materials 👶 Valid Certified-Data-Engineer-Professional Exam Test ✏ Certified-Data-Engineer-Professional Valid Test Testking 📳 Search for ✔ Certified-Data-Engineer-Professional ️✔️ on 《 www.prepawayexam.com 》 immediately to obtain a free download 🐭Dump Certified-Data-Engineer-Professional Torrent
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes