BTW, DOWNLOAD part of TestkingPass DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1WLjLEMY426dPmXp7bbr2gEUPygd-05GT
Test engine version is a simulation of real test; you can feel the atmosphere of formal test. You can well know your shortcoming and strength in the course of practicing Microsoft exam dumps. It adjusts you to do the DP-600 Certification Dumps according to the time of formal test. Most IT workers like using it to test DP-600 practice questions and their ability.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Clean, transform, and enrich data | 25-30% | - Clean data
|
| Topic 2: Deploy and maintain a data solution | 10-15% | - Maintain a data solution
|
| Topic 3: Design and manage the data model | 20-25% | - Implement and configure a data model
|
| Topic 4: Load and prepare data | 20-25% | - Create and configure items
|
| Topic 5: Secure and monitor data solutions | 15-20% | - Monitor data solutions
|
>> Latest DP-600 Exam Questions <<
Our company is a multinational company which is famous for the DP-600 training materials in the international market. After nearly ten years' efforts, now our company have become the topnotch one in the field, therefore, if you want to pass the DP-600 Exam as well as getting the related certification at a great ease, I strongly believe that the DP-600 study materials compiled by our company is your solid choice.
NEW QUESTION # 88
You have a Fabric workspace named Workspacel that contains a lakehouse named Lakehousel. Lakehousel contains a table named Tablel. Table 1 contains the following data.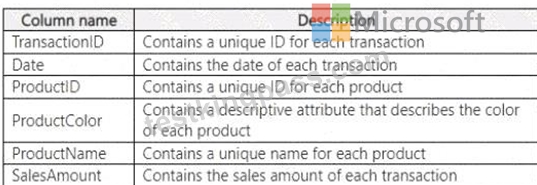
You need to perform the following actions:
* Load the data from Table! into a star schema.
* Create a product dimension table named DimProduct and a fact table named FactSales.
Which three columns should you include in DimProduct?
Answer: C
Explanation:
Step 1 - Understanding star schema design
Fact tables # contain transactional, numeric, and foreign key columns (e.g., TransactionID, Date, SalesAmount, ProductID).
Dimension tables # contain descriptive attributes and business keys (e.g., ProductID, ProductName, ProductColor).
Step 2 - Column classification
TransactionID # Fact (surrogate key for the fact table).
Date # Goes into a Date Dimension (not into DimProduct).
ProductID # Business key # belongs in DimProduct.
ProductColor # Descriptive attribute # belongs in DimProduct.
ProductName # Descriptive attribute # belongs in DimProduct.
SalesAmount # Fact (measure, belongs in FactSales).
Step 3 - Select DimProduct columns
So DimProduct should include:
ProductID
ProductName
ProductColor
That matches option A .
NEW QUESTION # 89
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.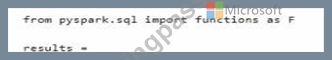
Which code should you run to populate the results DataFrame?




Answer: D
Explanation:
The correct code to populate the results DataFrame with minimal data shuffling is Option A.
Using the broadcast function in PySpark is a way to minimize data movement by broadcasting the smaller DataFrame ( customers) to each node in the cluster.
This is ideal when one DataFrame is much smaller than the other, as in this case with customers.
References = You can refer to the official Apache Spark documentation for more details on joins and the broadcast hint.
NEW QUESTION # 90
You have a Fabric tenant.
You are creating a Fabric Data Factory pipeline.
You have a stored procedure that returns the number of active customers and their average sales for the current month.
You need to add an activity that will execute the stored procedure in a warehouse. The returned values must be available to the downstream activities of the pipeline.
Which type of activity should you add?
Answer: B
Explanation:
Lookup activity reads and returns the content of a configuration file or table. It also returns the result of executing a query or stored procedure. The output can be a singleton value or an array of attributes, which can be consumed in a subsequent copy, transformation, or control flow activities like ForEach activity.
https://learn.microsoft.com/en-us/azure/data-factory/control-flow-lookup-activity
NEW QUESTION # 91
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.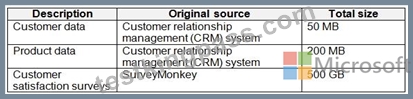
The Product data contains a single table and the following columns.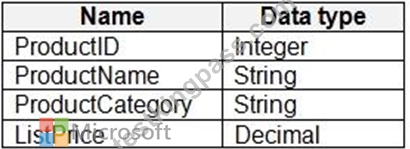
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
What should you recommend using to ingest the customer data into the data store in the AnalyticsPOC workspace?
Answer: C
Explanation:
Even though the text reads "Data will be loaded without transformation in one area of the AnalyticsPOC data store": in general, dataflows are used when data transformations are involved after ingestion. As suggested by user BHARAT, the Copy Activity should be the optimal solution.
NEW QUESTION # 92
You to need assign permissions for the data store in the AnalyticsPOC workspace. The solution must meet the security requirements.
Which additional permissions should you assign when you share the data store? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.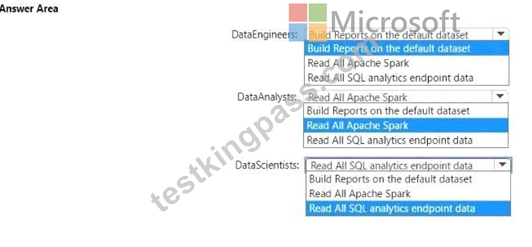
Answer:
Explanation: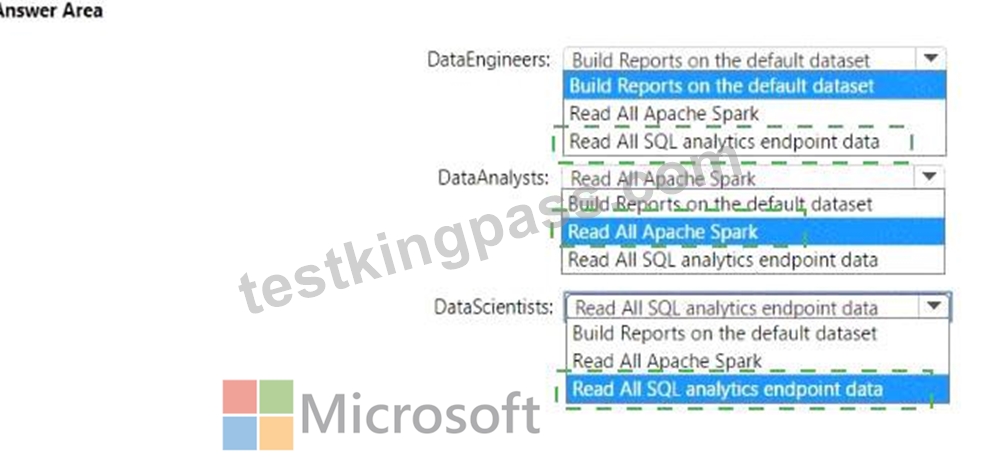
Explanation:
Comprehensive Detailed Explanation
When assigning permissions to roles in a Fabric workspace for analytics workloads, you must align permissions with the responsibilities and tools typically used by each persona:
1. Data Engineers
Their primary tasks include building and transforming data pipelines, as well as making datasets usable by others.
The appropriate permission is Build Reports on the default dataset, because this allows them to create and manage reports using the curated semantic model while preparing data for analysts and scientists.
2. Data Analysts
Analysts work heavily with Apache Spark for exploratory analysis, cleansing, and shaping data.
The correct permission is Read All Apache Spark, as this grants them the ability to query and analyze Spark- based data directly without elevated permissions that are unnecessary for their role.
3. Data Scientists
Data scientists often use SQL analytics endpoints to run queries, train models, and integrate data into machine learning workflows.
The correct permission is Read All SQL analytics endpoint data, since it enables direct programmatic access to the SQL endpoint, which is needed for advanced modeling and experimentation.
Summary of Selections:
DataEngineers # Build Reports on the default dataset
DataAnalysts # Read All Apache Spark
DataScientists # Read All SQL analytics endpoint data
References (Microsoft Fabric - DP-600 exam scope):
Workspace roles and permissions in Microsoft Fabric
SQL analytics endpoint in Fabric
Apache Spark in Microsoft Fabric
NEW QUESTION # 93
......
As for candidates who possessed with a DP-600 professional certification are more competitive. The current word is a stage of science and technology, social media and social networking has already become a popular means of DP-600 exam materials. As a result, more and more people study or prepare for exam through social networking. By this way, our DP-600 learning guide can be your best learn partner. The pass rate of our DP-600 exam questions is high as 99% to 100%, and it is a wise choice to have our DP-600 training guide.
DP-600 Reliable Exam Pattern: https://www.testkingpass.com/DP-600-testking-dumps.html
2026 Latest TestkingPass DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1WLjLEMY426dPmXp7bbr2gEUPygd-05GT