DOWNLOAD the newest ExamsLabs Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10lHOr7HCtP_bV_NUue0nVZTlvJTCeH3B
As we all know, practice makes perfect. It’s also applied into preparing for the exam. Databricks-Generative-AI-Engineer-Associate training materials of us contain both quality and quantity, and you will get enough practice if you choose us. In addition, Databricks-Generative-AI-Engineer-Associate exam cram cover most of the knowledge points for the exam, and you can master the major knowledge points for the exam as well as improve your professional ability in the process of learning. We are pass guarantee and money back guarantee if you fail to pass your exam by using Databricks-Generative-AI-Engineer-Associate Exam Dumps of us. Online and offline service are available by us, if you have any questions, you can consult us.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Real Exam Qty: | 45-60 |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Format: | Multiple choice, Multiple select |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Exam Price: | USD 200 |
| Recommended Training: | Databricks Academy - Generative AI Courses Mosaic AI Documentation |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Generative-AI-Engineer-Associate Certification Exam Cost <<
To make your job easy, ExamsLabs proudly announces that our users can gain a free-of-cost Databricks Databricks-Generative-AI-Engineer-Associate demo of all three available formats for Databricks-Generative-AI-Engineer-Associate Exam Questions. It will allow you to check out the standard of Databricks-Generative-AI-Engineer-Associate Practice Exam material. You will not be disappointed to see the quality of the product.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 24
A Generative AI Engineer is designing a chatbot for a gaming company that aims to engage users on its platform while its users play online video games.
Which metric would help them increase user engagement and retention for their platform?
Answer: B
Explanation:
In the context of designing a chatbot to engage users on a gaming platform, diversity of responses (option B) is a key metric to increase user engagement and retention. Here's why:
Diverse and Engaging Interactions:
A chatbot that provides varied and interesting responses will keep users engaged, especially in an interactive environment like a gaming platform. Gamers typically enjoy dynamic and evolving conversations, and diversity of responses helps prevent monotony, encouraging users to interact more frequently with the bot.
Increasing Retention:
By offering different types of responses to similar queries, the chatbot can create a sense of novelty and excitement, which enhances the user's experience and makes them more likely to return to the platform.
Why Other Options Are Less Effective:
A (Randomness): Random responses can be confusing or irrelevant, leading to frustration and reducing engagement.
C (Lack of Relevance): If responses are not relevant to the user's queries, this will degrade the user experience and lead to disengagement.
D (Repetition of Responses): Repetitive responses can quickly bore users, making the chatbot feel uninteresting and reducing the likelihood of continued interaction.
Thus, diversity of responses (option B) is the most effective way to keep users engaged and retain them on the platform.
NEW QUESTION # 25
Which indicator should be considered to evaluate the safety of the LLM outputs when qualitatively assessing LLM responses for a translation use case?
Answer: D
Explanation:
* Problem Context: When assessing the safety and effectiveness of LLM outputs in a translation use case, it is essential to ensure that the translations accurately and relevantly convey the intended message. The evaluation should focus on how well the LLM understands and processes different languages and contexts.
* Explanation of Options:
* Option A: The ability to generate responses in code- This is not relevant to translation quality or safety.
* Option B: The similarity to the previous language- While ensuring that translations preserve the original's intent is important, this doesn't directly address the overall quality or safety of the translation.
* Option C: The latency of the response and the length of text generated- These operational metrics are less critical in assessing the qualitative aspects of translation safety.
* Option D: The accuracy and relevance of the responses- This is crucial in translation to ensure that the translated content is true to the original in meaning and appropriateness. Accuracy and relevance directly impact the effectiveness and safety of translations, especially in sensitive or nuanced contexts.
Thus,Option Dis the most important indicator when evaluating the safety of LLM outputs in translation, focusing on the core aspects that determine the utility and trustworthiness of translated content.
NEW QUESTION # 26
A small and cost-conscious startup in the cancer research field wants to build a RAG application using Foundation Model APIs.
Which strategy would allow the startup to build a good-quality RAG application while being cost-conscious and able to cater to customer needs?
Answer: D
Explanation:
For a small, cost-conscious startup in the cancer research field, choosing a domain-specific and smaller LLM is the most effective strategy. Here's whyBis the best choice:
* Domain-specific performance: A smaller LLM that has been fine-tuned for the domain of cancer research will outperform a general-purpose LLM for specialized queries. This ensures high-quality responses without needing to rely on a large, expensive LLM.
* Cost-efficiency: Smaller models are cheaper to run, both in terms of compute resources and API usage costs. A domain-specific smaller LLM can deliver good quality responses without the need for the extensive computational power required by larger models.
* Focused knowledge: In a specialized field like cancer research, having an LLM tailored to the subject matter provides better relevance and accuracy for queries, while keeping costs low.Large, general- purpose LLMs may provide irrelevant information, leading to inefficiency and higher costs.
This approach allows the startup to balance quality, cost, and customer satisfaction effectively, making it the most suitable strategy.
NEW QUESTION # 27
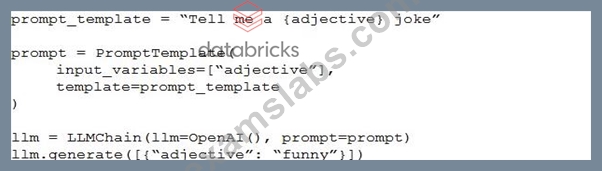
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.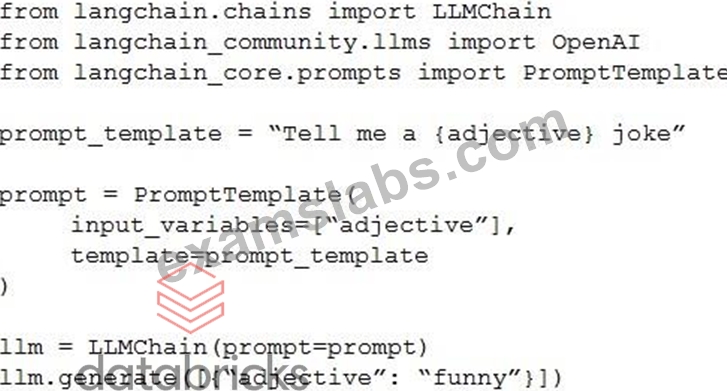
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: C
Explanation:
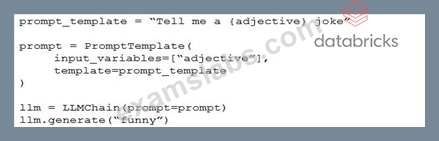
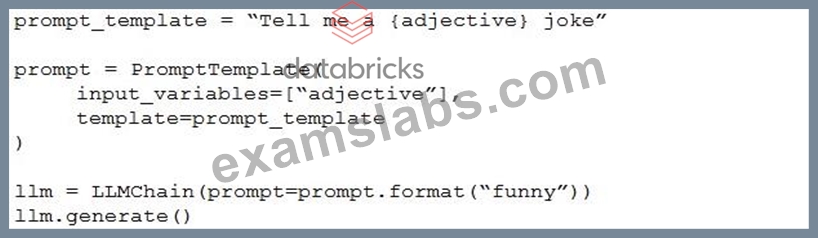
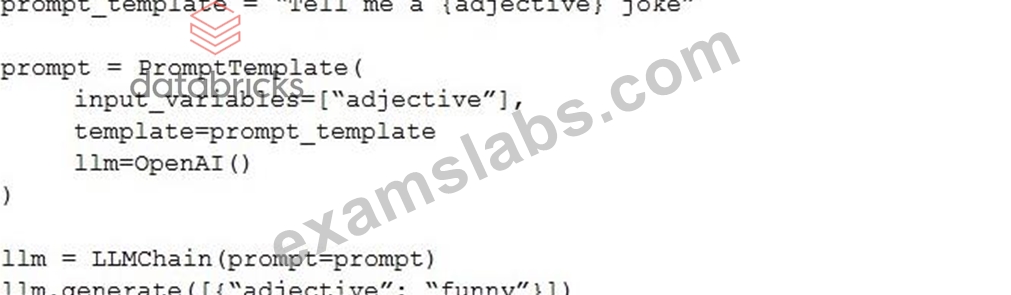
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 28
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
Answer: D
Explanation:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
* Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond
* This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
* Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
* Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond
* This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
* Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
* Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary
* This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
* Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states:"For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses."This matches Option C's approach of finding answers and summarizing them.
* Option D: Input: Customer reviews; Output: Classify review sentiment
* This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context.
It's more suited for feedback analysis than real-time customer service.
* Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
NEW QUESTION # 29
......
Databricks-Generative-AI-Engineer-Associate Well Prep: https://www.examslabs.com/Databricks/Generative-AI-Engineer/best-Databricks-Generative-AI-Engineer-Associate-exam-dumps.html
DOWNLOAD the newest ExamsLabs Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10lHOr7HCtP_bV_NUue0nVZTlvJTCeH3B