DP-700 Valid Exam Materials - Valid Test DP-700 Experience

BONUS!!! Download part of ITCertMagic DP-700 dumps for free: https://drive.google.com/open?id=15LDe6Zzk54yiI3aOsOzDQlYPKFLBATnb

Professional ability is very important both for the students and for the in-service staff because it proves their practical ability in the area they major in. Therefore choosing a certificate exam which boosts great values to attend is extremely important for them and the test Microsoft certification is one of them. Passing the test certification can prove your outstanding major ability in some area and if you want to pass the test smoothly you’d better buy our DP-700 Test Guide. We only use the certificated experts and published authors to compile our study materials and our products boost the practice test software to test the clients’ ability to answer the questions. The clients can firstly be familiar with our products in detail and then make their decisions to buy it or not.

Microsoft DP-700 Exam Syllabus Topics:

SectionWeightObjectives
Topic 1: Monitor and optimize an analytics solution30–35%- Optimize performance
  • 1. Optimize storage efficiency
    • 2. Optimize Lakehouse and data warehouse performance
      • 3. Optimize pipelines and data flows
        • 4. Optimize Spark and query performance
          - Troubleshoot issues
          • 1. Identify and resolve notebook and Spark errors
            • 2. Identify and resolve storage and query errors
              • 3. Identify and resolve Dataflow errors
                • 4. Identify and resolve pipeline errors
                  - Monitor analytics solutions
                  • 1. Monitor semantic model refreshes
                    • 2. Monitor Fabric items and activities
                      • 3. Monitor data ingestion and transformation
                        • 4. Configure alerts and notifications
                          Topic 2: Implement and manage an analytics solution30–35%- Manage data lifecycle and governance
                          • 1. Implement data governance with Microsoft Purview
                            • 2. Implement data retention and archiving
                              • 3. Manage data access and security
                                - Configure workspace settings
                                • 1. Configure OneLake workspace settings
                                  • 2. Configure domain workspace settings
                                    • 3. Configure Spark workspace settings
                                      • 4. Configure Microsoft Fabric workspace settings
                                        • 5. Configure Dataflows Gen2 settings
                                          - Manage data storage
                                          • 1. Choose appropriate data stores
                                            • 2. Implement data mirroring
                                              • 3. Create and manage OneLake shortcuts
                                                Topic 3: Ingest and transform data30–35%- Design and implement data loading patterns
                                                • 1. Prepare data for dimensional models
                                                  • 2. Design full and incremental data loads
                                                    • 3. Design streaming data loading patterns
                                                      - Transform data
                                                      • 1. Transform data using SQL
                                                        • 2. Transform data using PySpark
                                                          • 3. Clean, denormalize, and aggregate data
                                                            • 4. Transform data using KQL
                                                              - Orchestrate data operations
                                                              • 1. Implement schedules and triggers
                                                                • 2. Use parameters and dynamic expressions
                                                                  • 3. Orchestrate with notebooks and pipelines
                                                                    - Ingest data
                                                                    • 1. Ingest data using pipelines
                                                                      • 2. Ingest data using Dataflows Gen2
                                                                        • 3. Ingest data using Eventstreams

                                                                          >> DP-700 Valid Exam Materials <<

                                                                          DP-700 Valid Exam Materials - 100% Valid Questions Pool

                                                                          ITCertMagic Microsoft DP-700 exam braindump has a high hit rate which is 100%. It can guarantee all candidates using our dumps will pass the exam. Of course, it is not indicate that you will succeed without any efforts. What you need to do, you must study all the questions in our ITCertMagic dumps. Only in this way can you easily deal with the examination. How about it feels? When you prepare the exam, ITCertMagic can help you save a lot of time. It is your guarantee to pass DP-700 Certification. Do you want to have the dumps? Hurry up to visit ITCertMagic to purchase DP-700 exam materials. In addition, before you buy it, you can download the free demo which will help you to know more details.

                                                                          Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric Sample Questions (Q25-Q30):

                                                                          NEW QUESTION # 25
                                                                          You have two Fabric workspaces named Workspace1 and Workspace2.
                                                                          You have a Fabric deployment pipeline named deployPipeline1 that deploys items from Workspace1 to Workspace2. DeployPipeline1 contains all the items in Workspace1.
                                                                          You recently modified the items in Workspaces1.
                                                                          The workspaces currently contain the items shown in the following table.
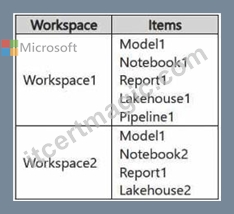
                                                                          Items in Workspace1 that have the same name as items in Workspace2 are currently paired.
                                                                          You need to ensure that the items in Workspace1 overwrite the corresponding items in Workspace2. The solution must minimize effort.
                                                                          What should you do?

                                                                          Answer: B

                                                                          Explanation:
                                                                          When running a deployment pipeline in Fabric, if the items in Workspace1 are paired with the corresponding items in Workspace2 (based on the same name), the deployment pipeline will automatically overwrite the existing items in Workspace2 with the modified items from Workspace1. There's no need to delete, rename, or back up items manually unless you need to keep versions. By simply running deployPipeline1, the pipeline will handle overwriting the existing items in Workspace2 based on the pairing, ensuring the latest version of the items is deployed with minimal effort.


                                                                          NEW QUESTION # 26
                                                                          You need to ensure that WorkspaceA can be configured for source control. Which two actions should you perform?
                                                                          Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.

                                                                          Answer: A,C

                                                                          Explanation:
                                                                          Topic 2, Litware, IncCase Study
                                                                          This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
                                                                          To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
                                                                          At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
                                                                          To start the case study
                                                                          To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
                                                                          Overview
                                                                          Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide.
                                                                          Litware also manages an online advertising business for the authors it represents.
                                                                          Existing Environment. Fabric Environment
                                                                          Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
                                                                          The company has a data engineering team that uses Python for data processing.
                                                                          Existing Environment. Data Processing
                                                                          The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
                                                                          Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse.
                                                                          Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
                                                                          Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
                                                                          Existing Environment. Sales Data
                                                                          Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
                                                                          In the source system, the sales data refreshes every six hours starting at midnight each day.
                                                                          The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
                                                                          Sales Date
                                                                          Author
                                                                          Price
                                                                          Units
                                                                          SKU
                                                                          A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
                                                                          Existing Environment. Security Groups
                                                                          Litware has the following security groups:
                                                                          Sales
                                                                          Fabric Admins
                                                                          Streaming Admins
                                                                          Existing Environment. Performance Issues
                                                                          Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
                                                                          When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
                                                                          The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
                                                                          Requirements. Planned Changes
                                                                          Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
                                                                          Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
                                                                          Requirements. Version Control
                                                                          Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
                                                                          Requirements. Governance Requirements
                                                                          To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
                                                                          Requirements. Data Requirements
                                                                          Litware identifies the following data requirements:
                                                                          Process the SEO data in near-real-time (NRT).
                                                                          Make the book reviews available in the lakehouse without making a copy of the data.
                                                                          When a new book cover image arrives in the Files folder, process the image as soon as possible.


                                                                          NEW QUESTION # 27
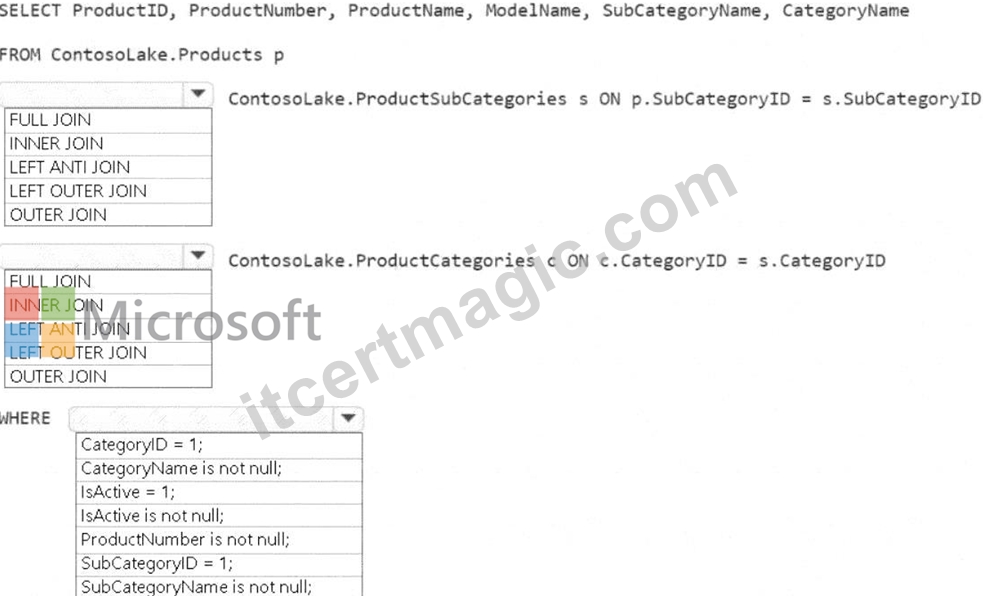
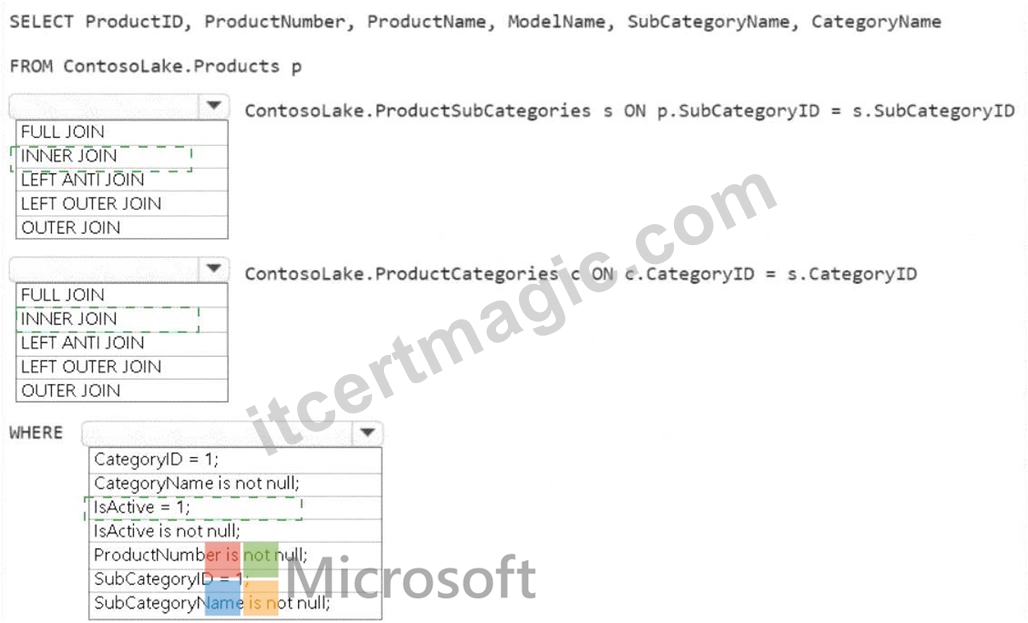
                                                                          You need to create the product dimension.
                                                                          How should you complete the Apache Spark SQL code? To answer, select the appropriate options in the answer area.
                                                                          NOTE: Each correct selection is worth one point.
                                                                          Answer:

                                                                          Explanation:
                                                                          Explanation:
                                                                          A screenshot of a computer Description automatically generated
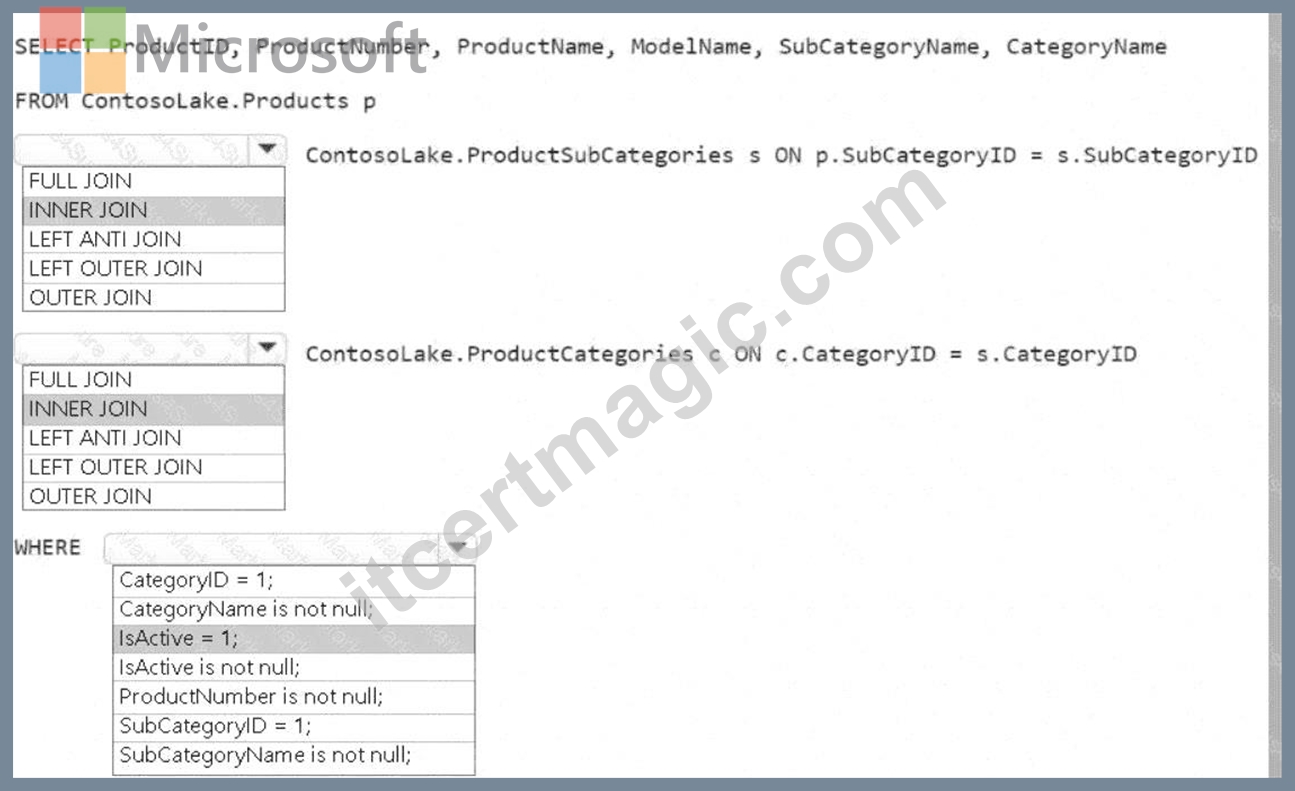
                                                                          Join between Products and ProductSubCategories:
                                                                          Use an INNER JOIN.
                                                                          The goal is to include only products that are assigned to a subcategory. An INNER JOIN ensures that only matching records (i.e., products with a valid subcategory) are included.
                                                                          Join between ProductSubCategories and ProductCategories:
                                                                          Use an INNER JOIN.
                                                                          Similar to the above logic, we want to include only subcategories assigned to a valid product category. An INNER JOIN ensures this condition is met.
                                                                          WHERE Clause
                                                                          Condition: IsActive = 1
                                                                          Only active products (where IsActive equals 1) should be included in the gold layer. This filters out inactive products.


                                                                          NEW QUESTION # 28
                                                                          You have a Fabric workspace that contains a data pipeline named Pipeline1 and a notebook named Notebook1. Pipeline1 contains an activity that is used to run Notebook1. Pipeline! is scheduled to run every
                                                                          10 minutes.
                                                                          You receive an alert that Pipeline! failed during the notebook execution activity.
                                                                          You need to identify in which cell the failure occurred.
                                                                          What should you do from Monitor in the Fabric admin center?

                                                                          Answer: C


                                                                          NEW QUESTION # 29
                                                                          Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
                                                                          After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
                                                                          You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
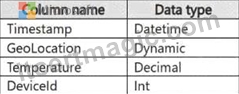
                                                                          Reference contains reference data in the following format.
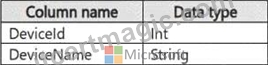
                                                                          Both tables contain millions of rows.
                                                                          You have the following KQL queryset.
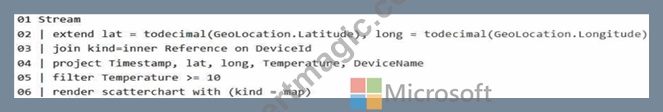
                                                                          You need to reduce how long it takes to run the KQL queryset.
                                                                          Solution: You add the make_list() function to the output columns.
                                                                          Does this meet the goal?

                                                                          Answer: B

                                                                          Explanation:
                                                                          Adding an aggregation like make_list() would require additional processing and memory, which could make the query slower.


                                                                          NEW QUESTION # 30
                                                                          ......

                                                                          ITCertMagic is a website engaged in the providing customer DP-700 VCE Dumps and makes sure every candidates passing actual test easily and quickly. We have a team of IT workers who have rich experience in the study of Microsoft dumps torrent and they check the updating of Microsoft top questions everyday to ensure the accuracy of exam collection.

                                                                          Valid Test DP-700 Experience: https://www.itcertmagic.com/Microsoft/real-DP-700-exam-prep-dumps.html

                                                                          BTW, DOWNLOAD part of ITCertMagic DP-700 dumps from Cloud Storage: https://drive.google.com/open?id=15LDe6Zzk54yiI3aOsOzDQlYPKFLBATnb