Databricks-Machine-Learning-Professional시험유형, Databricks-Machine-Learning-Professional최고품질덤프공부자료

ITDumpsKR Databricks-Machine-Learning-Professional 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1e6sqCN5rVK8bi-ofdVNau_LAgdgFxFKf
ITDumpsKR의 Databricks Databricks-Machine-Learning-Professional덤프를 공부하면 100% Databricks Databricks-Machine-Learning-Professional 시험패스를 보장해드립니다. 만약 Databricks Databricks-Machine-Learning-Professional 덤프자료를 구매하여 공부한후 시험에 탈락할시 불합격성적표와 주문번호를 메일로 보내오시면 덤프비용을 바로 환불해드립니다. 저희 ITDumpsKR Databricks Databricks-Machine-Learning-Professional덤프로 자격증부자되세요.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
>> Databricks-Machine-Learning-Professional시험유형 <<
Databricks-Machine-Learning-Professional시험유형 덤프에는 ExamName} 시험문제의 모든 유형이 포함
ITDumpsKR 의 엘리트는 다년간 IT업계에 종사한 노하우로 높은 적중율을 자랑하는 Databricks Databricks-Machine-Learning-Professional덤프를 연구제작하였습니다. 한국어 온라인서비스가 가능하기에 Databricks Databricks-Machine-Learning-Professional덤프에 관하여 궁금한 점이 있으신 분은 구매전 문의하시면 됩니다. Databricks Databricks-Machine-Learning-Professional덤프로 시험에서 좋은 성적 받고 자격증 취득하시길 바랍니다.
Databricks Databricks-Machine-Learning-Professional 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| 주제 2 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| 주제 3 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| 주제 4 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| 주제 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| 주제 6 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| 주제 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| 주제 8 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
최신 ML Data Scientist Databricks-Machine-Learning-Professional 무료샘플문제 (Q83-Q88):
질문 # 83
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. The pipeline needs to automatically refresh its model each time it runs. The project is attached to the existing model model_name in the MLflow Model Registry.
They are using the following code block as part of their solution:
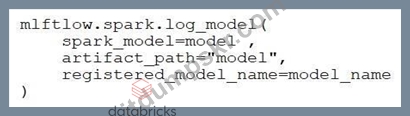
Which statement describes the impact of the registered_model_name=model_name parameter and argument given that model_name already exists in the MLflow Model Registry?
- A. It identifies the name of the logged model in the MLflow Experiment.
- B. It registers the new version of the model_name model in the MLflow Model Registry.
- C. It avoids the need to specify the model name in the subsequent required call to mflow.register_model.
- D. It registers a new model called model_name in the MLflow Model Registry.
정답:B
설명:
When using registered_model_name=model_name in mlflow.spark.log_model(), MLflow automatically registers the logged model under the specified model name. If that model name already exists in the MLflow Model Registry, MLflow creates a new version of that existing registered model rather than a new model entry. This enables automatic versioning and continuous model refresh with each pipeline run.
질문 # 84
A Machine Learning Engineer has automated a model retraining job in Databricks. Each scheduled run trains multiple candidate models with new sales data and logs all runs with MLflow.
The goal is to select and register the best-performing model at the end of each cycle to ensure optimal forecast accuracy. Which approach will meet this goal?
- A. Register the first model that has an evaluation metric better than the previously deployed model.
- B. Register the model with the lowest training loss regardless of validation metrics.
- C. Register the best model based on the primary evaluation metric.
- D. Register all models from the run since all of them are trained on newer data and hence will be more accurate.
정답:C
설명:
Selecting and registering the model that performs best on the primary evaluation metric ensures that only the highest-quality model is promoted at each retraining cycle. This approach aligns with MLOps best practices by basing promotion decisions on objective performance criteria rather than training order or assumptions about data freshness.
질문 # 85
What is the main purpose of the Databricks Feature Store?
- A. Storing trained models
- B. Centralizing reusable ML features
- C. Replacing Spark ML pipelines
- D. Storing raw data
정답:B
설명:
Feature Store allows teams to:
share features
avoid training/serving skew
maintain feature lineage.
질문 # 86
Why are Delta tables often used to store machine learning features?
- A. They support schema enforcement and time travel
- B. They allow faster GPU training
- C. They reduce model size
- D. They replace Spark DataFrames
정답:A
설명:
Delta Lake provides:
ACID transactions
time travel
schema enforcement
These are essential for reproducible ML pipelines.
질문 # 87
A Machine Learning Engineer has a computer vision model in Databricks Model Serving that obscures sensitive data from images. Internal teams use the model throughout the work week when they request access to new files. Recently model users complained that the model takes much longer in the morning. This coincides with when people arrive at work and request files for the day. When the engineer reviews the endpoint health metrics, they see P50 model latency peaks around 9AM at 20 seconds. Request rate also peaks at 9AM at 15 requests/second. The GPU utilization is over 60%, GPU memory usage over 50%, and provisioned concurrency at 4 throughout the day. What can the engineer do to reduce user wait time when request rate peaks at 9AM each morning?
- A. The endpoint is constrained by its ability to handle simultaneous requests. Define a rate_1imit on the endpoint to spread out the requests over the course of the day.
- B. The endpoint is constrained by its ability to handle simultaneous requests. Scale the endpoint horizontally by editing the endpoint workload_size from "Small" to "Medium" to increase the model concurrency.
- C. The endpoint is constrained by the GPU. Scale the endpoint vertically by changing the endpoint workload_type from "GPU_SMALL" to "GPU_MEDIUM".
- D. The endpoint is constrained by its ability to handle simultaneous requests. Enable "scale_to_zero" on the endpoint to spin up additional endpoints quickly to handle the requests.
정답:B
설명:
The symptoms indicate a concurrency bottleneck during the 9AM traffic spike: request rate increases sharply, latency jumps, and the endpoint is already running at a fixed provisioned concurrency of 4. Increasing workload_size scales the endpoint horizontally to handle more concurrent requests, reducing queueing and bringing down user-perceived wait time during peak demand.
질문 # 88
......
Databricks-Machine-Learning-Professional최고품질 덤프공부자료: https://www.itdumpskr.com/Databricks-Machine-Learning-Professional-exam.html
- 높은 적중율을 자랑하는 Databricks-Machine-Learning-Professional시험유형 덤프 🐱 “ www.dumptop.com ”을 통해 쉽게⏩ Databricks-Machine-Learning-Professional ⏪무료 다운로드 받기Databricks-Machine-Learning-Professional퍼펙트 최신 덤프모음집
- Databricks-Machine-Learning-Professional최신 업데이트 인증덤프자료 ☣ Databricks-Machine-Learning-Professional최신 업데이트 덤프자료 🏝 Databricks-Machine-Learning-Professional퍼펙트 최신 덤프모음집 🌞 「 www.itdumpskr.com 」에서▶ Databricks-Machine-Learning-Professional ◀를 검색하고 무료로 다운로드하세요Databricks-Machine-Learning-Professional시험대비 최신 덤프문제
- Databricks-Machine-Learning-Professional 100%시험패스 공부자료 🏌 Databricks-Machine-Learning-Professional최신 업데이트 시험덤프 😬 Databricks-Machine-Learning-Professional최신 업데이트 인증덤프자료 🐫 무료로 다운로드하려면( www.dumptop.com )로 이동하여【 Databricks-Machine-Learning-Professional 】를 검색하십시오Databricks-Machine-Learning-Professional자격증공부
- Databricks-Machine-Learning-Professional시험유형 인증시험자료 🥵 검색만 하면✔ www.itdumpskr.com ️✔️에서➥ Databricks-Machine-Learning-Professional 🡄무료 다운로드Databricks-Machine-Learning-Professional덤프문제
- 시험준비에 가장 좋은 Databricks-Machine-Learning-Professional시험유형 덤프데모 다운로드 🎸 무료로 다운로드하려면➥ www.koreadumps.com 🡄로 이동하여「 Databricks-Machine-Learning-Professional 」를 검색하십시오Databricks-Machine-Learning-Professional자격증공부
- Databricks-Machine-Learning-Professional퍼펙트 인증공부 🟡 Databricks-Machine-Learning-Professional최신 업데이트 인증덤프자료 😎 Databricks-Machine-Learning-Professional시험대비 최신 공부자료 💸 무료 다운로드를 위해[ Databricks-Machine-Learning-Professional ]를 검색하려면✔ www.itdumpskr.com ️✔️을(를) 입력하십시오Databricks-Machine-Learning-Professional완벽한 시험기출자료
- Databricks-Machine-Learning-Professional퍼펙트 덤프 최신버전 🏑 Databricks-Machine-Learning-Professional덤프문제 🍩 Databricks-Machine-Learning-Professional시험대비 최신 덤프문제 🤰 ✔ www.exampassdump.com ️✔️에서➥ Databricks-Machine-Learning-Professional 🡄를 검색하고 무료 다운로드 받기Databricks-Machine-Learning-Professional퍼펙트 덤프 최신버전
- Databricks-Machine-Learning-Professional시험유형 인증시험자료 🤝 무료로 쉽게 다운로드하려면☀ www.itdumpskr.com ️☀️에서▷ Databricks-Machine-Learning-Professional ◁를 검색하세요Databricks-Machine-Learning-Professional최고품질 덤프데모
- 시험준비에 가장 좋은 Databricks-Machine-Learning-Professional시험유형 덤프데모 다운로드 🅿 무료 다운로드를 위해▛ Databricks-Machine-Learning-Professional ▟를 검색하려면➠ www.passtip.net 🠰을(를) 입력하십시오Databricks-Machine-Learning-Professional 100%시험패스 공부자료
- Databricks-Machine-Learning-Professional최신 업데이트 덤프자료 📕 Databricks-Machine-Learning-Professional완벽한 시험기출자료 🧭 Databricks-Machine-Learning-Professional최신 업데이트 시험덤프 🛒 오픈 웹 사이트▷ www.itdumpskr.com ◁검색[ Databricks-Machine-Learning-Professional ]무료 다운로드Databricks-Machine-Learning-Professional퍼펙트 최신 덤프모음집
- Databricks-Machine-Learning-Professional덤프문제 ♻ Databricks-Machine-Learning-Professional합격보장 가능 덤프공부 🎲 Databricks-Machine-Learning-Professional시험대비 최신 공부자료 📖 ⇛ www.dumptop.com ⇚의 무료 다운로드➽ Databricks-Machine-Learning-Professional 🢪페이지가 지금 열립니다Databricks-Machine-Learning-Professional 100%시험패스 공부자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
참고: ITDumpsKR에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Machine-Learning-Professional 시험 문제집이 있습니다: https://drive.google.com/open?id=1e6sqCN5rVK8bi-ofdVNau_LAgdgFxFKf