P.S. Free 2026 Linux Foundation KCNA dumps are available on Google Drive shared by LatestCram: https://drive.google.com/open?id=1gOfHc-cXrm7YmL_X7d2LXZJ1_XBTRuuG
The price for KCNA exam materials is reasonable, and no matter you are a student or you are an employee in the company, you can afford the expense. Just think that you just need to spend certain money, you can obtain the certification, it’s quite cost-efficiency. What’s more, KCNA exam braindumps cover most of the knowledge points for the exam, and you can mater the major knowledge points for the exam as well as improve your ability in the process of learning. You can obtain downloading link and password within ten minutes after purchasing KCNA Exam Materials.
Linux Foundation KCNA Exam is intended for individuals who are interested in working with Kubernetes and cloud-native technologies. KCNA exam is designed to validate the knowledge and skills required to work with these technologies, including the ability to implement, manage, and troubleshoot Kubernetes clusters. Kubernetes and Cloud Native Associate certification program is also suitable for IT professionals who are interested in learning more about cloud-native technologies and want to enhance their knowledge.
Linux Foundation KCNA Certification Exam is suitable for individuals with varying levels of experience in the field of cloud-native computing. Whether you are just starting out in your career or have years of experience, KCNA exam will test your knowledge and skills in a comprehensive and rigorous manner. Kubernetes and Cloud Native Associate certification is a valuable asset for individuals who want to demonstrate their expertise in cloud-native computing and advance their careers in this field.
We always strictly claim for our KCNA study materials must be the latest version, to keep our study materials up to date, we constantly review and revise them to be at par with the latest Linux Foundation syllabus for KCNA exam. This feature has been enjoyed by over 80,000 takes whose choose our study materials. The one who choose our study materials that consider our website as the top preparation material seller for KCNA Study Materials, and inevitable to carry all candidates the finest knowledge on exam syllabus contents. Not only that, we will provide you a free update service within one year from the date of purchase, in order to keep up the changes in the exam so that every candidates who purchase our KCNA study materials can pass the exam one time.
Linux Foundation KCNA Exam covers a broad range of topics related to Kubernetes and cloud-native technologies, including the fundamentals of containerization, Kubernetes architecture and components, deployment and scaling of Kubernetes applications, troubleshooting Kubernetes clusters, and managing Kubernetes resources using various tools and APIs. Kubernetes and Cloud Native Associate certification exam is designed to assess an individual's knowledge and expertise in these areas and provides a reliable measure of their competency in managing and deploying cloud-native applications.
NEW QUESTION # 195
What are the two steps performed by the kube-scheduler to select a node to schedule a pod?
Answer: C
Explanation:
The kube-scheduler selects a node in two main phases: filtering and scoring, so C is correct. First, filtering identifies which nodes are feasible for the Pod by applying hard constraints. These include resource availability (CPU/memory requests), node taints/tolerations, node selectors and required affinities, topology constraints, and other scheduling requirements. Nodes that cannot satisfy the Pod's requirements are removed from consideration.
Second, scoring ranks the remaining feasible nodes using priority functions to choose the "best" placement.
Scoring can consider factors like spreading Pods across nodes/zones, packing efficiency, affinity preferences, and other policies configured in the scheduler. The node with the highest score is selected (with tie-breaking), and the scheduler binds the Pod by setting spec.nodeName.
Option B ("filtering and selecting") is close but misses the explicit scoring step that is central to scheduler design. The scheduler does "select" a node, but the canonical two-step wording in Kubernetes scheduling is filtering then scoring. Options A and D are not how scheduler internals are described.
Operationally, understanding filtering vs scoring helps troubleshoot scheduling failures. If a Pod can't be scheduled, it failed in filtering-kubectl describe pod often shows "0/... nodes are available" reasons (insufficient CPU, taints, affinity mismatch). If it schedules but lands in unexpected places, it's often about scoring preferences (affinity weights, topology spread preferences, default scheduler profiles).
So the verified correct answer is C: kube-scheduler uses Filtering and Scoring.
=========
NEW QUESTION # 196
What command to view the kube config?
Answer: C
Explanation:
https://kubernetes.io/docs/reference/generated/kubectl/kubectl-commands#-em-view-em-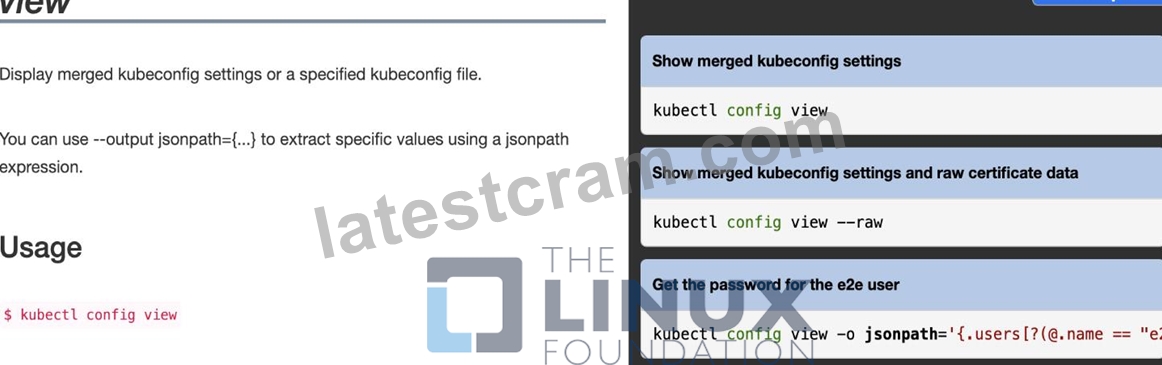
NEW QUESTION # 197
In a Kubernetes cluster, which component is responsible for maintaining the desired state of applications by reconciling resources such as Deployments and ReplicaSets?
Answer: D
Explanation:
The Controller Manager runs controllers that continuously compare the current state of resources with the desired state and take corrective actions to reconcile differences, ensuring applications remain in the intended state.
NEW QUESTION # 198
What is the main purpose of a DaemonSet?
Answer: D
Explanation:
The correct answer is A. A DaemonSet is a workload controller whose job is to ensure that a specific Pod runs on all nodes (or on a selected subset of nodes) in the cluster. This is fundamentally different from Deployments/ReplicaSets, which aim to maintain a certain replica count regardless of node count. With a DaemonSet, the number of Pods is implicitly tied to the number of eligible nodes: add a node, and the DaemonSet automatically schedules a Pod there; remove a node, and its Pod goes away.
DaemonSets are commonly used for node-level services and background agents: log collectors, node monitoring agents, storage daemons, CNI components, or security agents-anything where you want a presence on each node to interact with node resources. This aligns with option D's phrasing ("agent on every node"), but option A is the canonical definition and is slightly broader because it covers "all or certain nodes" (via node selectors/affinity/taints-tolerations) and the fact that the unit is a Pod.
Why the other options are wrong: DaemonSets do not "keep kubelet running" (B); kubelet is a node service managed by the OS. DaemonSets do not use a replicas field to maintain a specific count (C); that's Deployment/ReplicaSet behavior.
Operationally, DaemonSets matter for cluster operations because they provide consistent node coverage and automatically react to node pool scaling. They also require careful scheduling constraints so they land only where intended (e.g., only Linux nodes, only GPU nodes). But the main purpose remains: ensure a copy of a Pod runs on each relevant node-option A.
=========
NEW QUESTION # 199
What is autoscaling?
Answer: D
Explanation:
https://kubernetes.io/blog/2016/07/autoscaling-in-kubernetes/
Autoscaling means automatically scaling up or down in response to real-time usage data.
NEW QUESTION # 200
......
Exam KCNA Tutorials: https://www.latestcram.com/KCNA-exam-cram-questions.html
BONUS!!! Download part of LatestCram KCNA dumps for free: https://drive.google.com/open?id=1gOfHc-cXrm7YmL_X7d2LXZJ1_XBTRuuG