空想可以使人想出很多絕妙的主意,但卻辦不了任何事情。所以當你苦思暮想的如何通過Microsoft的AI-500認證考試時,還不如打開你的電腦,點擊VCESoft,你就會看到你最想要的東西,價格非常優惠,品質可以保證,而且保證你100%通過考試。
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
Microsoft AI-500認證考試在競爭激烈的IT行業中越來越受歡迎,報名參加考試的人越來越多。但是它的難度並沒有減小,依然很難通過考試,畢竟這是個權威的檢驗電腦專業知識和資訊技術能力的考試。一般人為了通過Microsoft AI-500 認證考試都需要花費大量的時間和精力來復習備考。
問題 #53
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.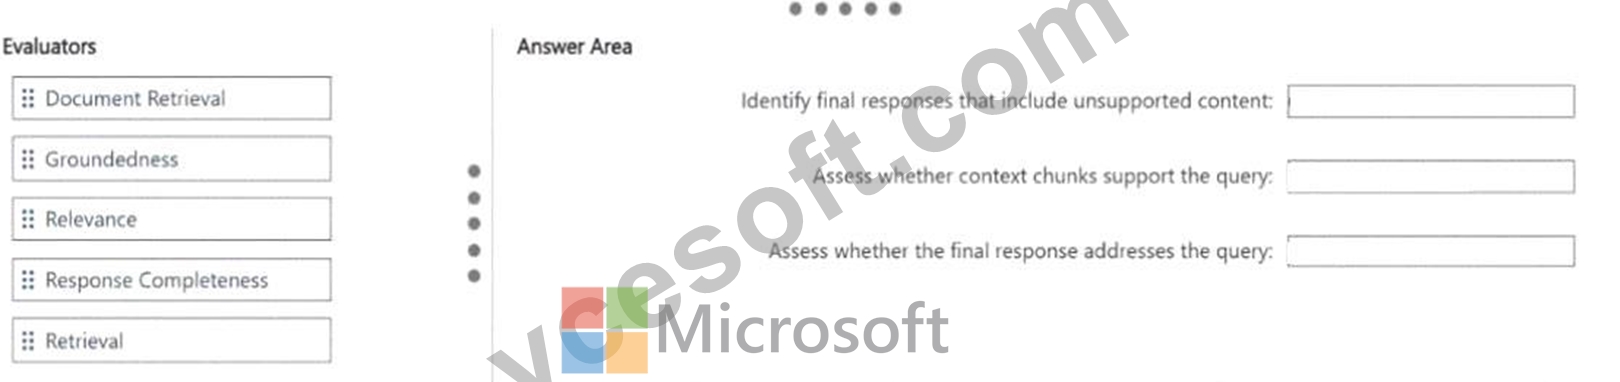
答案:
解題說明: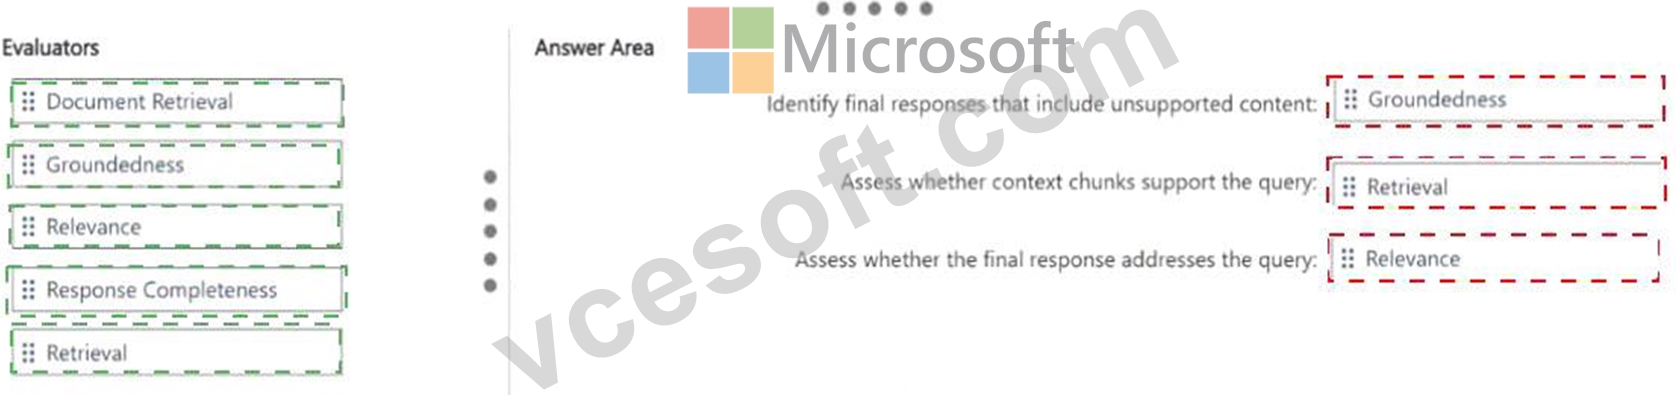
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators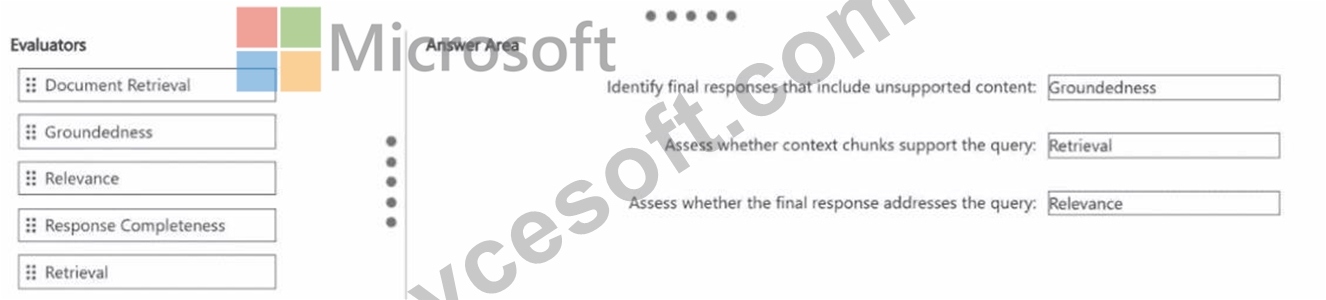
問題 #54
You have an Azure API Management Premium instance that hosts a REST API named inventoryAPl.
You plan to provide Microsoft Foundry agents with the ability to call API operations by using the Model Context Protocol (MCP). You will use API Management as the gateway without a separate MCP backend.
You need to recommend a solution for the MCP deployment that supports the following:
* Microsoft Entra JSON Web Token (JWT) validation
* Azure Monitor diagnostics
* Request quotas
What should you recommend?
答案:C
解題說明:
Azure API Management can expose an existing managed REST API directly as a remote MCP server, turning selected REST operations into MCP tools without requiring a separate MCP backend. The API Management gateway continues to apply its policy engine, so Microsoft Entra JWT validation, quotas/rate limits, and Azure Monitor/Application Insights diagnostics can be enforced at the MCP endpoint. Azure API Center catalogs APIs but does not itself create the MCP runtime endpoint. Azure Functions or Logic Apps could host MCP-compatible code, but both would introduce the separate backend that the question explicitly says to avoid. Because the API already resides in an APIM Premium instance, using APIM ' s native MCP exposure capability is the minimal and policy-rich design. Therefore B is correct. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure API Management - Expose REST API as an MCP server
問題 #55
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
答案:C
解題說明:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
問題 #56
You have a multi-agent solution in a Microsoft Foundry project. The project connects to an Azure Storage account named stgaudit.
You plan to enable a storage-backed tool for the agent The tool will read and write blobs to stgaudit.
You need to create a role assignment for the agent. The solution must follow the principle of least privilege.
Which role should you use?
答案:B
問題 #57
You have a Microsoft Agent Framework workflow processor that receives customer support requests from a queue. Each request is evaluated by three independent Microsoft Foundry agents.
You discover that the current processor dequeues 30 requests at a time and starts all agent runs immediately.
During peak load, as many as 90 agent runs execute simultaneously, and the downstream API receives partial participant messages.
A single agent run completes in five seconds at the 95th percentile (95p), and the target throughput is 120 requests per minute.
You need to change the orchestration to ensure that it meets the throughput target and prevents more than 30 agent runs from executing simultaneously. The solution must produce one consolidated downstream payload for each request.
What should you do?
答案:A
解題說明:
Each customer request requires three independent agent runs. Dequeuing ten requests and launching a concurrent three-agent workflow for each request creates at most 30 simultaneous agent runs, exactly meeting the concurrency ceiling. Because the three agents execute in parallel and one run takes about five seconds at the 95th percentile, ten requests can complete in roughly five seconds, which corresponds to 120 requests per minute. Microsoft Agent Framework ' s ConcurrentBuilder performs a fan-out to independent participants and a fan-in that can produce one consolidated response, solving the downstream partial-message problem.
Sequential workflows would require roughly three agent durations per request and miss the throughput target.
A 90-participant workflow violates the concurrency limit. Therefore C is the only option that satisfies the numerical and orchestration constraints together. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
問題 #58
......
VCESoft是一個你可以完全相信的網站。VCESoft的Microsoft技術專家為了讓大家可以學到更加高效率的資料一直致力於各種AI-500認證考試的研究,從而開發出了更多的考試資料。只要你使用過一次VCESoft的資料,你就肯定還想用第二次。因為VCESoft不但給你提供最好的資料,而且為你提供最優質的服務。如果你對我們的產品有任何意見都可以隨時提出,因為我們不僅以讓廣大考生輕鬆通過AI-500考試為宗旨,更把為大家提供最好的服務作為我們的目標。
AI-500認證考試: https://www.vcesoft.com/AI-500-pdf.html