BTW, DOWNLOAD part of DumpsReview DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1UHISuSY9k2PVW_rS0HdRwVM3undDK7RV
DP-100 certification exam opens the doors for starting a bright career. After passing the Designing and Implementing a Data Science Solution on Azure DP-100 test you will easily apply for well-paid jobs in top companies all over the world. DP-100 exam offers multiple advantages including, high salaries, promotions, enhancing resumes, and skills improvement. Once you pass the DP-100 Exam, you can avail all these benefits. If you want to pass the Microsoft DP-100 certification exam, you must find the best resource to prepare for the DP-100 test.
| Section | Objectives |
|---|---|
| Topic 1: Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Topic 2: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
| Topic 3: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 4: Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
| Topic 5: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
Everything needs a right way. The good method can bring the result with half the effort, the same different exam also needs the good test method. Our DP-100 study questions in every year are summarized based on the test purpose, every answer is a template, there are subjective and objective exams of two parts, we have in the corresponding modules for different topic of deliberate practice. To this end, our DP-100 Training Materials in the qualification exam summarize some problem- solving skills, and induce some generic templates. The user can scout for answer and scout for score based on the answer templates we provide, so the universal template can save a lot of precious time for the user.
NEW QUESTION # 43
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code: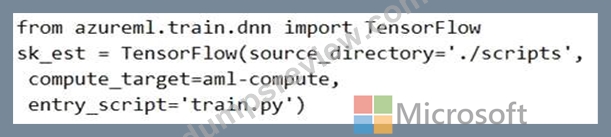
Does the solution meet the goal?
Answer: A
Explanation:
Explanation
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION # 44
You are using the Hyperdrive feature in Azure Machine Learning to train a model.
You configure the Hyperdrive experiment by running the following code: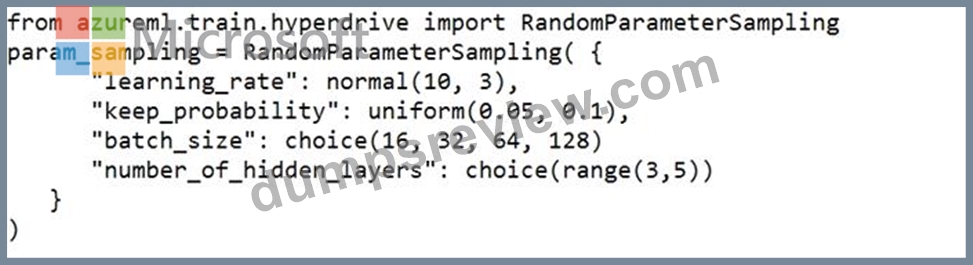
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: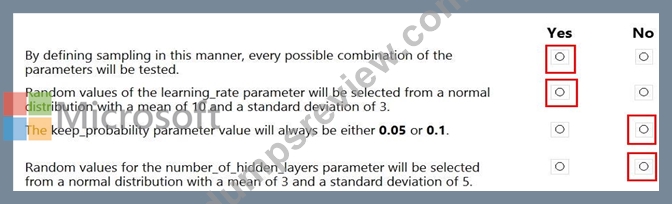
Explanation:
Box 1: Yes
In random sampling, hyperparameter values are randomly selected from the defined search space. Random sampling allows the search space to include both discrete and continuous hyperparameters.
Box 2: Yes
learning_rate has a normal distribution with mean value 10 and a standard deviation of 3.
Box 3: No
keep_probability has a uniform distribution with a minimum value of 0.05 and a maximum value of 0.1.
Box 4: No
number_of_hidden_layers takes on one of the values [3, 4, 5].
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
NEW QUESTION # 45
You previously deployed a model that was trained using a tabular dataset named training-dataset, which is based on a folder of CSV files.
Over time, you have collected the features and predicted labels generated by the model in a folder containing a CSV file for each month. You have created two tabular datasets based on the folder containing the inference data: one named predictions-dataset with a schema that matches the training data exactly, including the predicted label; and another named features-dataset with a schema containing all of the feature columns and a timestamp column based on the filename, which includes the day, month, and year.
You need to create a data drift monitor to identify any changing trends in the feature data since the model was trained. To accomplish this, you must define the required datasets for the data drift monitor.
Which datasets should you use to configure the data drift monitor? To answer, drag the appropriate datasets to the correct data drift monitor options. Each source may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: training-dataset
Baseline dataset - usually the training dataset for a model.
Box 2: predictions-dataset
Target dataset - usually model input data - is compared over time to your baseline dataset. This comparison means that your target dataset must have a timestamp column specified.
The monitor will compare the baseline and target datasets.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-monitor-datasets
NEW QUESTION # 46
You use the designer to create a training pipeline for a classification model. The pipeline uses a dataset that includes the features and labels required for model training.
You create a real-time inference pipeline from the training pipeline. You observe that the schema for the generated web service input is based on the dataset and includes the label column that the model predicts.
Client applications that use the service must not be required to submit this value.
You need to modify the inference pipeline to meet the requirement.
What should you do?
Answer: A
Explanation:
By default, the Web Service Input will expect the same data schema as the module output data which connects to the same downstream port as it. You can remove the target variable column in the inference pipeline using Select Columns in Dataset module. Make sure that the output of Select Columns in Dataset removing target variable column is connected to the same port as the output of the Web Service Intput module.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-designer-automobile-price-deploy
NEW QUESTION # 47
You are determining if two sets of data are significantly different from one another by using Azure Machine Learning Studio.
Estimated values in one set of data may be more than or less than reference values in the other set of data. You must produce a distribution that has a constant. Type I error as a function of the correlation.
You need to produce the distribution.
Which type of distribution should you produce?
Answer: B
NEW QUESTION # 48
......
As one of the leading brand in the market, our DP-100 practice materials can be obtained on our website within five minutes. That is the expression of their efficiency. Their amazing quality can totally catch eyes of exam candidates with passing rate up to 98 to 100 percent. We have free demos for your information and the demos offer details of real exam contents. All contents of DP-100 practice materials contain what need to be mastered.
DP-100 Learning Mode: https://www.dumpsreview.com/DP-100-exam-dumps-review.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by DumpsReview: https://drive.google.com/open?id=1UHISuSY9k2PVW_rS0HdRwVM3undDK7RV