BONUS!!! Download part of PrepAwayETE Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1uND7nhEUzH0OUi3msdILGfZSRZYvuZLN
There are more opportunities for possessing with a certification, and our Professional-Machine-Learning-Engineer study tool is the greatest resource to get a leg up on your competition, and stage yourself for promotion. When it comes to our time-tested Professional-Machine-Learning-Engineer latest practice dumps, for one thing, we have a professional team contains a lot of experts who have devoted themselves to the research and development of our Professional-Machine-Learning-Engineer Exam Guide, thus we feel confident enough under the intensely competitive market. For another thing, conforming to the real exam our Professional-Machine-Learning-Engineer study tool has the ability to catch the core knowledge. So our customers can pass the exam with ease.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Price: | $200 USD (plus tax where applicable) |
| Exam Format: | Multiple choice, Multiple select |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 50-60 |
| Exam Duration: | 120 minutes |
| Passing Score: | Not officially published, approximately 70% |
| Related Certifications: | Google Cloud Professional Data Engineer Google Cloud Professional Cloud Architect |
| Available Languages: | Japanese, English |
| Recommended Training: | Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path Official Exam Guide |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Practice Professional-Machine-Learning-Engineer Questions <<
If you would like to use all kinds of electronic devices to prepare for the Professional-Machine-Learning-Engineer exam, then I am glad to tell you that our online app version of our Professional-Machine-Learning-Engineer study guide is definitely your perfect choice. With the online app version of our Professional-Machine-Learning-Engineer Learning Materials, you can just feel free to practice the questions in our Professional-Machine-Learning-Engineer training dumps no matter you are using your mobile phone, personal computer, or tablet PC.
Google Professional Machine Learning Engineer certification is highly valued in the industry and is recognized as a benchmark of excellence in the field of machine learning. Achieving this certification demonstrates that an individual has the skills and knowledge required to design and implement machine learning solutions at scale using Google Cloud technologies. Google Professional Machine Learning Engineer certification can help individuals advance their careers and open up new opportunities in the field of machine learning.
NEW QUESTION # 339
You work with a team of researchers to develop state-of-the-art algorithms for financial analysis. Your team develops and debugs complex models in TensorFlow. You want to maintain the ease of debugging while also reducing the model training time. How should you set up your training environment?
Answer: A
NEW QUESTION # 340
You are developing an ML model that uses sliced frames from video feed and creates bounding boxes around specific objects. You want to automate the following steps in your training pipeline: ingestion and preprocessing of data in Cloud Storage, followed by training and hyperparameter tuning of the object model using Vertex AI jobs, and finallydeploying the model to an endpoint. You want to orchestrate the entire pipeline with minimal cluster management. What approach should you use?
Answer: D
Explanation:
* Option A is incorrect because using Kubeflow Pipelines on Google Kubernetes Engine is not the most convenient way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines is an open-source platform that allows you to build, run, and manage ML pipelines using containers1. Google Kubernetes Engine is a service that allows you to create and manage clusters of virtual machines that run Kubernetes, an open-source system for orchestrating containerized applications2. However, this option requires more effort and resources than option B, as it involves creating and configuring the clusters, installing and maintaining Kubeflow Pipelines, and writing and running the pipeline code.
* Option B is correct because using Vertex AI Pipelines with TensorFlow Extended (TFX) SDK is the best way to orchestrate the entire pipeline with minimal cluster management. Vertex AI Pipelines is a service that allows you to create and run scalable and portable ML pipelines on Google Cloud3. TensorFlow Extended (TFX) is a framework that provides a set of components and libraries for building production-ready ML pipelines using TensorFlow4. You can use Vertex AI Pipelines with TFX SDK to ingest and preprocess the data in Cloud Storage, train and tune the object model using Vertex AI jobs, and deploy the model to an endpoint, using predefined or custom components. Vertex AI Pipelines handles the underlying infrastructure and orchestration for you, so you don't need to worry about cluster management or scalability.
* Option C is incorrect because using Vertex AI Pipelines with Kubeflow Pipelines SDK is not the most suitable way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines SDK is a library that allows you to build and run ML pipelines using Kubeflow Pipelines5. You can use Vertex AI Pipelines with Kubeflow Pipelines SDK to create and run ML pipelines on Google Cloud, using containers. However, this option is less convenient and consistent than option B, as it requires you to use different APIs and tools for different steps of the pipeline, such as Vertex AI SDK for training and deployment, and Kubeflow Pipelines SDK for ingestion and preprocessing. Moreover, this option does not leverage the benefits of TFX, such as the standard components, the metadata store, or the ML Metadata library.
* Option D is incorrect because using Cloud Composer for the orchestration is not the most efficient way to orchestrate the entire pipeline with minimal cluster management. Cloud Composer is a service that allows you to create and run workflows using Apache Airflow, an open-source platform for
* orchestrating complex tasks. You can use Cloud Composer to orchestrate the entire pipeline, by creating and managing DAGs (directed acyclic graphs) that define the dependencies and order of the tasks.
However, this option is more complex andcostly than option B, as it involves creating and configuring the environments, installing and maintaining Airflow, and writing and running the DAGs.
References:
* Kubeflow Pipelines documentation
* Google Kubernetes Engine documentation
* Vertex AI Pipelines documentation
* TensorFlow Extended documentation
* Kubeflow Pipelines SDK documentation
* [Cloud Composer documentation]
* [Vertex AI documentation]
* [Cloud Storage documentation]
* [TensorFlow documentation]
NEW QUESTION # 341
A regulator requires your bank to provide, for each declined loan application, the specific applicant attributes that most influenced the decision. Your model is a deep neural network deployed to an online endpoint. You need to satisfy this requirement without replacing the model.
What should you do?
Answer: D
Explanation:
Integrated gradients produce local, per-instance attributions that identify which input features drove an individual prediction, which is what the regulator requires. Global importance and surrogate models describe overall or approximate behavior and do not faithfully explain a specific decision.
NEW QUESTION # 342
You need to train a regression model based on a dataset containing 50,000 records that is stored in BigQuery.
The data includes a total of 20 categorical and numerical features with a target variable that can include negative values. You need to minimize effort and training time while maximizing model performance. What approach should you take to train this regression model?
Answer: C
Explanation:
AutoML Tables is a service that allows you to automatically build, analyze, and deploy machine learning models on tabular data. It is suitable for large-scale regression and classification problems, and it supports various optimization objectives, data splitting methods, and hyperparameter tuning algorithms. AutoML Tables can handle both categorical and numerical features, and it can also handle missing values and outliers.
AutoML Tables is a good choice for this problem because it minimizes the effort and training time required to train a regression model, while maximizing the model performance.
RMSLE stands for Root Mean Squared Logarithmic Error, and it is a metric that measures the average difference between the logarithm of the predicted values and the logarithm of the actual values.RMSLE is useful for regression problems where the target variable can include negative values, and where large differences between small values are more important than large differences between large values. For example, RMSLE penalizes underestimating a value of 10 by 2 more than overestimating a value of 1000 by
20. RMSLE is a good optimization objective for this problem because it can handle negative values in the target variable, and it can reduce the impact of outliers and large errors.
For more information about AutoML Tables and RMSLE, see the following references:
* AutoML Tables: end-to-end workflows on AI Platform Pipelines
* Predict workload failures before they happen with AutoML Tables
* How to Calculate RMSE in R
NEW QUESTION # 343
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?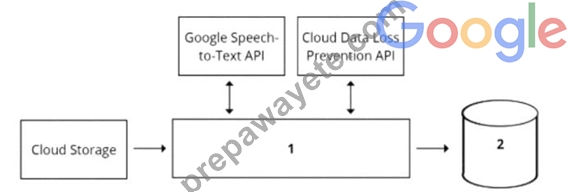
Answer: A
Explanation:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
NEW QUESTION # 344
......
Professional-Machine-Learning-Engineer Valid Real Exam: https://www.prepawayete.com/Google/Professional-Machine-Learning-Engineer-practice-exam-dumps.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PrepAwayETE: https://drive.google.com/open?id=1uND7nhEUzH0OUi3msdILGfZSRZYvuZLN