Do you want to pass Databricks-Certified-Professional-Data-Engineer exam and get the related certification within the minimum time and effort? If you would like to give me a positive answer, you really should keep a close eye on our website since you can find the best Databricks-Certified-Professional-Data-Engineer study material in here--our Databricks-Certified-Professional-Data-Engineer Training Materials. We have helped millions of thousands of candidates to prepare for the Databricks-Certified-Professional-Data-Engineer exam and all of them have got a fruitful outcome, we believe you will be the next winner as long as you join in us!
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Passing Score: | 70% |
| Exam Price: | USD 200 |
| Available Languages: | Korean, Portuguese (Brazil), Japanese, English |
| Exam Duration: | 120 minutes |
| Exam Format: | Multiple Choice |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Real Exam Qty: | 59 |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Reliable Databricks-Certified-Professional-Data-Engineer Exam Braindumps <<
As the authoritative provider of Databricks-Certified-Professional-Data-Engineer guide training, we can guarantee a high pass rate compared with peers, which is also proved by practice. Our good reputation is your motivation to choose our learning materials. We guarantee that if you under the guidance of our Databricks-Certified-Professional-Data-Engineer study tool step by step you will pass the exam without a doubt and get a certificate. Our learning materials are carefully compiled over many years of practical effort and are adaptable to the needs of the exam. We firmly believe that you cannot be an exception. Choosing our Databricks-Certified-Professional-Data-Engineer Exam Questions actually means that you will have more opportunities to be promoted in the near future. If you eventually fail the exam, we will refund the fee by the contract. We are confident that in the future, our Databricks-Certified-Professional-Data-Engineer study tool will be more attractive and the pass rate will be further enhanced.
Databricks Certified Professional Data Engineer certification exam covers a wide range of topics, including data ingestion, data processing, data storage, and data analysis. Candidates are required to demonstrate their ability to design and implement data solutions using Databricks, as well as their understanding of best practices for data engineering. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and takes approximately two hours to complete.
NEW QUESTION # 117
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company.
A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users.
Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
Answer: A
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
:
Databricks Documentation on Secret Management: Secrets
NEW QUESTION # 118
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
Answer: C
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
:
Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta-batch.
html#schema-management
NEW QUESTION # 119
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events . Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region.
The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve.
Answer: C
Explanation:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next-generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization , Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z-ORDER commands) while improving query performance on large tables-particularly for high-ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low- maintenance solution recommended by Databricks.
NEW QUESTION # 120
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: E
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 121
A nightly job ingests data into a Delta Lake table using the following code: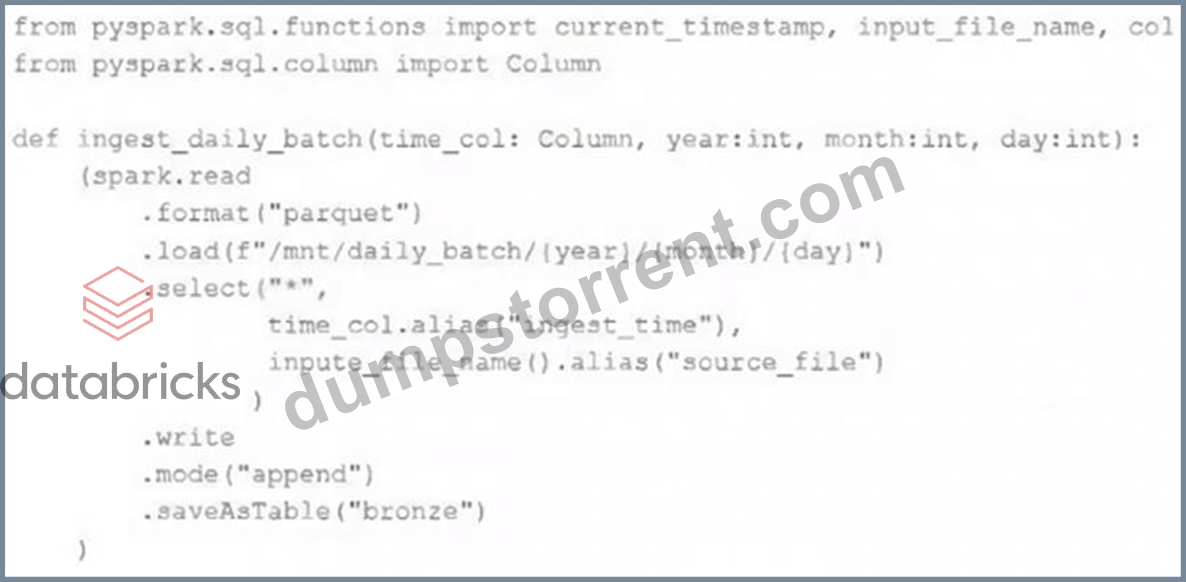
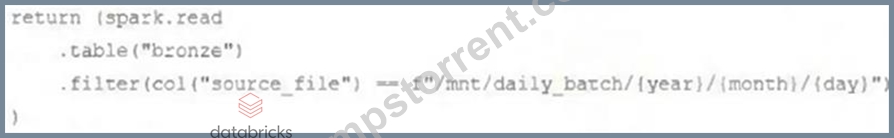
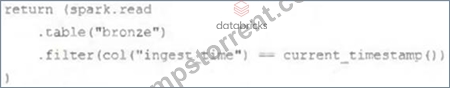
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: A
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 122
......
Databricks-Certified-Professional-Data-Engineer VCE Dumps: https://www.dumpstorrent.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-torrent.html