BTW, DOWNLOAD part of Prep4sureGuide Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1uZiBffDCT2X2P5ebFQ1zk06_DaO_-dxW
our Data-Engineer-Associate exam guide has not equivocal content that may confuse exam candidates. All question points of our Data-Engineer-Associate study quiz can dispel your doubts clearly. Get our Data-Engineer-Associate certification actual exam and just make sure that you fully understand it and study every single question in it by heart. And we believe you will get benefited from it enormously beyond your expectations with the help our Data-Engineer-Associate Learning Materials.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Data Store Management | 26% | - Design and implement data storage solutions
- Optimize storage performance and cost |
| Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
- Ensure reliability and scalability |
| Data Security and Governance | 18% | - Encrypt data at rest and in transit - Implement access control and authentication
|
>> Data-Engineer-Associate Certification Test Answers <<
This Data-Engineer-Associate exam helps you put your career on the right track and you can achieve your career goals in the rapidly evolving field of technology. To gain all these personal and professional benefits you just need to pass the Prepare for your Data-Engineer-Associate exam which is hard to pass. However, with proper Amazon Data-Engineer-Associate Exam Preparation and planning you can achieve this task easily. For quick and complete Data-Engineer-Associate exam preparation you can trust Prep4sureGuide Prepare for your Data-Engineer-Associate Questions.
NEW QUESTION # 54
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?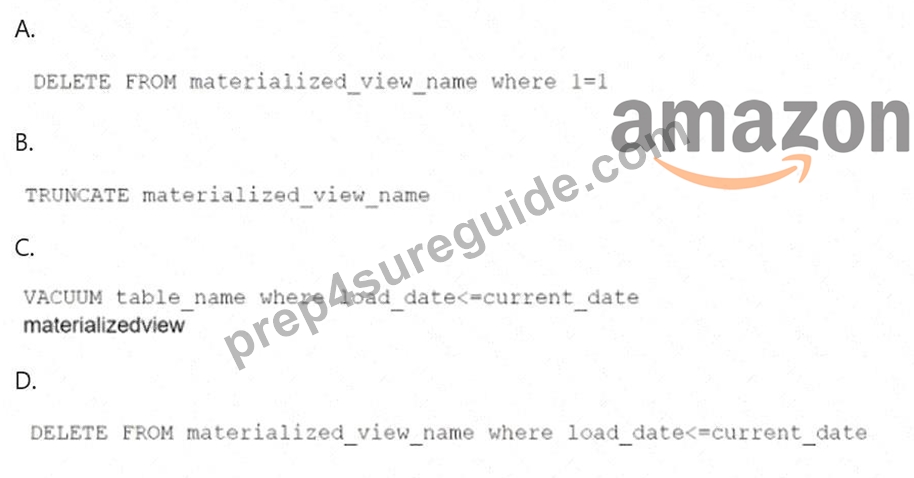
Answer: C
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 55
A company needs a solution to manage costs for an existing Amazon DynamoDB table. The company also needs to control the size of the table. The solution must not disrupt any ongoing read or write operations. The company wants to use a solution that automatically deletes data from the table after 1 month.
Which solution will meet these requirements with the LEAST ongoing maintenance?
Answer: B
Explanation:
The requirement is to manage the size of an Amazon DynamoDB table by automatically deleting data older than 1 month without disrupting ongoing read or write operations. The simplest and most maintenance-free solution is to use DynamoDB Time-to-Live (TTL).
Option A: Use the DynamoDB TTL feature to automatically expire data based on timestamps.
DynamoDB TTL allows you to specify an attribute (e.g., a timestamp) that defines when items in the table should expire. After the expiration time, DynamoDB automatically deletes the items, freeing up storage space and keeping the table size under control without manual intervention or disruptions to ongoing operations.
Other options involve higher maintenance and manual scheduling or scanning operations, which increase complexity unnecessarily compared to the native TTL feature.
Reference:
DynamoDB Time-to-Live (TTL)
NEW QUESTION # 56
A company has a production AWS account that runs company workloads. The company's security team created a security AWS account to store and analyze security logs from the production AWS account. The security logs in the production AWS account are stored in Amazon CloudWatch Logs.
The company needs to use Amazon Kinesis Data Streams to deliver the security logs to the security AWS account.
Which solution will meet these requirements?
Answer: C
Explanation:
Amazon Kinesis Data Streams is a service that enables you to collect, process, and analyze real-time streaming data. You can use Kinesis Data Streams to ingest data from various sources, such as Amazon CloudWatch Logs, and deliver it to different destinations, such as Amazon S3 or Amazon Redshift. To use Kinesis Data Streams to deliver the security logs from the production AWS account to the security AWS account, you need to create a destination data stream in the security AWS account. This data stream will receive the log data from the CloudWatch Logs service in the production AWS account. To enable this cross- account data delivery, you need to create an IAM role and a trust policy in the security AWS account. The IAM role defines the permissions that the CloudWatch Logs service needs to put data into the destination data stream. The trust policy allows the production AWS account to assume the IAM role. Finally, you need to create a subscription filter in the production AWS account. A subscription filter defines the pattern to match log events and the destination to send the matching events. In this case, the destination is the destination data stream in the security AWS account. This solution meets the requirements of using Kinesis Data Streams to deliver the security logs to the security AWS account. The other options are either not possible or not optimal.
You cannot create a destination data stream in the production AWS account, as this would not deliver the data to the security AWS account. You cannot create a subscription filter in the security AWS account, as this would not capture the log events from the production AWS account. References:
* Using Amazon Kinesis Data Streams with Amazon CloudWatch Logs
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 3: Data Ingestion and Transformation, Section 3.3: Amazon Kinesis Data Streams
NEW QUESTION # 57
A media company wants to improve a system that recommends media content to customer based on user behavior and preferences. To improve the recommendation system, the company needs to incorporate insights from third-party datasets into the company's existing analytics platform.
The company wants to minimize the effort and time required to incorporate third-party datasets.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
AWS Data Exchange is a service that makes it easy to find, subscribe to, and use third-party data in the cloud.
It provides a secure and reliable way to access and integrate data from various sources, such as data providers, public datasets, or AWS services. Using AWS Data Exchange, you can browse and subscribe to data products that suit your needs, and then use API calls or the AWS Management Console to export the data to Amazon S3, where you can use it with your existing analytics platform. This solution minimizes the effort and time required to incorporate third-party datasets, as you do not need to set up and manage data pipelines, storage, or access controls. You also benefit from the data quality and freshness provided by the data providers, who can update their data products as frequently as needed12.
The other options are not optimal for the following reasons:
* B. Use API calls to access and integrate third-party datasets from AWS. This option is vague and does not specify which AWS service or feature is used to access and integrate third-party datasets. AWS offers a variety of services and features that can help with data ingestion, processing, and analysis, but not all of them are suitable for the given scenario. For example, AWS Glue is a serverless data integration service that can help you discover, prepare, and combine data from various sources, but it requires you to create and run data extraction, transformation, and loading (ETL) jobs, which can add operational overhead3.
* C. Use Amazon Kinesis Data Streams to access and integrate third-party datasets from AWS CodeCommit repositories. This option is not feasible, as AWS CodeCommit is a source control service that hosts secure Git-based repositories, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams is a service that enables you to capture, process, and analyze data streams in real time, such as clickstream data, application logs, or IoT telemetry. It does not support accessing and integrating data from AWS CodeCommit repositories, which are meant for storing and managing code, not data .
* D. Use Amazon Kinesis Data Streams to access and integrate third-party datasets from Amazon Elastic Container Registry (Amazon ECR). This option is also not feasible, as Amazon ECR is a fully managed container registry service that stores, manages, and deploys container images, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams does not support accessing and integrating data from Amazon ECR, which is meant for storing and managing container images, not data .
:
1: AWS Data Exchange User Guide
2: AWS Data Exchange FAQs
3: AWS Glue Developer Guide
4: AWS CodeCommit User Guide
5: Amazon Kinesis Data Streams Developer Guide
6: Amazon Elastic Container Registry User Guide
7: Build a Continuous Delivery Pipeline for Your Container Images with Amazon ECR as Source
NEW QUESTION # 58
A company uses Amazon S3 buckets, AWS Glue tables, and Amazon Athena as components of a data lake.
Recently, the company expanded its sales range to multiple new states. The company wants to introduce state names as a new partition to the existing S3 bucket, which is currently partitioned by date.
The company needs to ensure that additional partitions will not disrupt daily synchronization between the AWS Glue Data Catalog and the S3 buckets.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Explanation: Scheduling an AWS Glue crawler to periodically update the Data Catalog automates the process of detecting new partitions and updating the catalog, which minimizes manual maintenance and operational overhead.
NEW QUESTION # 59
......
It is well known that the best way to improve your competitive advantages in this modern world is to increase your soft power, such as graduation from a first-tier university, fruitful experience in a well-known international company, or even possession of some globally recognized Data-Engineer-Associate certifications, which can totally help you highlight your resume and get a promotion in your workplace to a large extend. If you are interested our Data-Engineer-Associate Guide Torrent, please contact us immediately, we would show our greatest enthusiasm to help you obtain the certification.
Reliable Data-Engineer-Associate Braindumps Ebook: https://www.prep4sureguide.com/Data-Engineer-Associate-prep4sure-exam-guide.html
DOWNLOAD the newest Prep4sureGuide Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1uZiBffDCT2X2P5ebFQ1zk06_DaO_-dxW