Databricks-Certified-Professional-Data-Engineer Latest Test Format | Databricks-Certified-Professional-Data-Engineer Review Guide
If you are going to take Databricks Databricks-Certified-Professional-Data-Engineer certification exam, it is essential to use Databricks-Certified-Professional-Data-Engineer training materials. If you are looking for reference materials without a clue, stop!If you don't know what materials you should use, you can try DumpsQuestion Databricks Databricks-Certified-Professional-Data-Engineer exam dumps. The hit rate of the dumps is very high, which guarantees you can pass your exam with ease at the first attempt. DumpsQuestion Databricks Databricks-Certified-Professional-Data-Engineer Practice Test dumps can determine accurately the scope of the examination compared with other exam materials, which can help you improve efficiency of study and help you well prepare for Databricks-Certified-Professional-Data-Engineer exam.
| Section | Weight | Objectives |
|---|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. DataFrame operations and transformations
- 2. Spark SQL queries and functions
- 3. Window functions
- Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Performance optimization techniques
- 3. Spark APIs in Python
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
- Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. Time travel and data versioning
- 3. ACID transactions
- Delta Lake operations
- 1. Merge, update, delete operations
- 2. Delta Live Tables
- 3. Schema evolution and enforcement
|
>> Databricks-Certified-Professional-Data-Engineer Latest Test Format <<
Databricks-Certified-Professional-Data-Engineer Review Guide | Latest Databricks-Certified-Professional-Data-Engineer Exam Guide
Nowadays, using computer-aided software to pass the Databricks-Certified-Professional-Data-Engineer exam has become a new trend. Because the new technology enjoys a distinct advantage, that is convenient and comprehensive. In order to follow this trend, our company product such a Databricks-Certified-Professional-Data-Engineer exam questions that can bring you the combination of traditional and novel ways of studying. The passing rate of our study material is up to 99%. If you are not fortune enough to acquire the Databricks-Certified-Professional-Data-Engineer Certification at once, you can unlimitedly use our product at different discounts until you reach your goal and let your dream comes true.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q111-Q116):
NEW QUESTION # 111
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. O Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
- B. O Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
- C. O Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- D. O Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
Answer: D
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration. Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 112
When you drop an external DELTA table using the SQL Command DROP TABLE table_name, how does it impact metadata(delta log, history), and data stored in the storage?
- A. Drops table from metastore and data in storage but keeps metadata(delta log, history)
- B. Drops table from metastore, data but keeps metadata(delta log, history) in storage
- C. Drops table from metastore, but keeps metadata(delta log, history)and data in storage
- D. Drops table from metastore, metadata(delta log, history)but keeps the data in storage
- E. Drops table from metastore, metadata(delta log, history)and data in storage
Answer: C
Explanation:
Explanation
The answer is Drops table from metastore, but keeps metadata and data in storage.
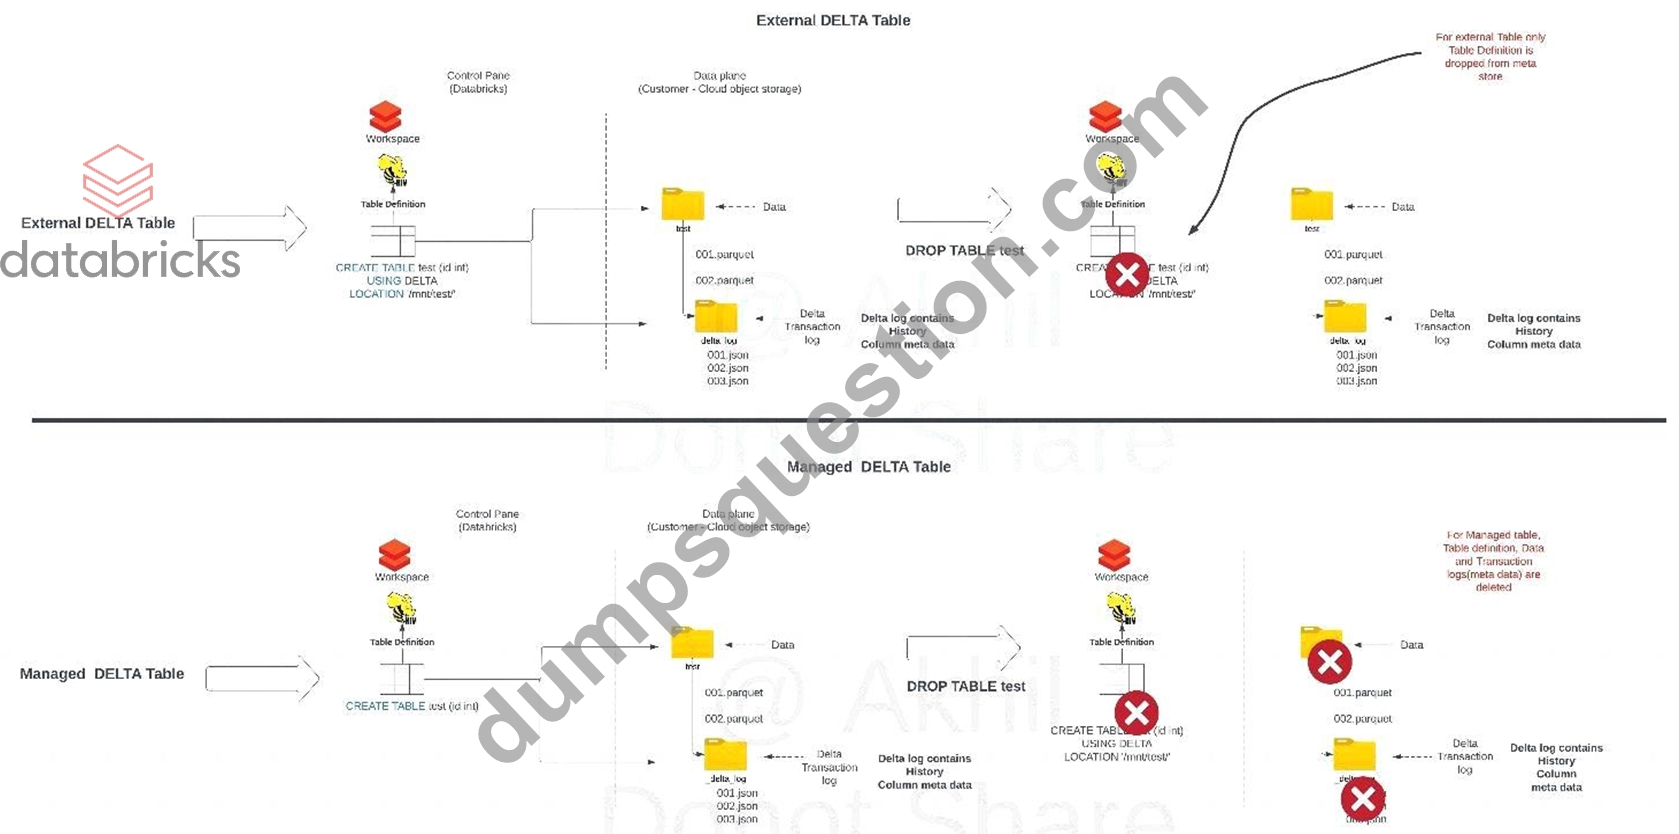
When an external table is dropped, only the table definition is dropped from metastore everything including data and metadata(Delta transaction log, time travel history) remains in the storage. Delta log is considered as part of metadata because if you drop a column in a delta table(managed or external) the column is not physically removed from the parquet files rather it is recorded in the delta log. The delta log becomes a key metadata layer for a Delta table to work.
Please see the below image to compare the external delta table and managed delta table and how they differ in how they are created and what happens if you drop the table.
Diagram Description automatically generated
NEW QUESTION # 113
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
- A. Spark cannot capture the topic partition fields from the kafka source.
- B. New fields not be computed for historic records.
- C. Updating the table schema requires a default value provided for each file added.
- D. Updating the table schema will invalidate the Delta transaction log metadata.
Answer: B
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
References:
* Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta- batch.html#schema-management
NEW QUESTION # 114
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users .
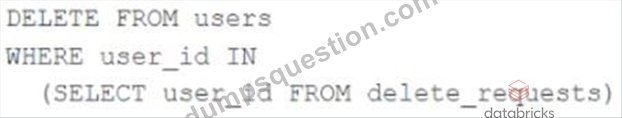
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- B. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- C. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
- D. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- E. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
Answer: C
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under
"Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 115
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement - the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
@dlt.table
@dlt.expect( " invalid_sensor_reading " , " reading > = 120 " )
def quarantine_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " ) - B. @dlt.table
@dlt.expect_or_drop( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
@dlt.table
@dlt.expect( " invalid_sensor_reading " , " reading > = 120 " )
def quarantine_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " ) - C. @dlt.table
@dlt.expect_or_drop( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
@dlt.table
@dlt.expect_or_drop( " invalid_sensor_reading " , " reading > = 120 " ) def quarantine_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " ) - D. @dlt.table
@dlt.expect_or_drop( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
@dlt.table
@dlt.expect( " invalid_sensor_reading " , " reading < 120 " )
def quarantine_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
Answer: A
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect, @dlt.
expect_or_drop, and @dlt.expect_all.
* @dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows . Instead, failing rows can be written to a quarantine table.
* @dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
* Good rows (reading < 120) go to the silver table .
* Bad rows (reading > = 120) go to a quarantine table .
* Bad rows should not be included in silver.
The correct implementation is Option A , where:
* The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
* The quarantine table applies an expectation for reading > = 120, ensuring bad records are captured separately.
Other options are incorrect:
* Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
* Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
Reference: Databricks Documentation - Delta Live Tables (DLT) Expectations: @dlt.expect, @dlt.
expect_or_drop, and Quarantine Tables.
NEW QUESTION # 116
......
In addition, a 24/7 customer assistance is also available at Databricks-Certified-Professional-Data-Engineer to assist you in using the product during any technical hitch. In summary, getting ready for 60 certification test might be challenging, but with the appropriate strategy and our Databricks-Certified-Professional-Data-Engineer Actual Exam questions, you can clear the test in a short time.
Databricks-Certified-Professional-Data-Engineer Review Guide: https://www.dumpsquestion.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-collection.html
- Dumps Databricks-Certified-Professional-Data-Engineer Cost 🕑 Databricks-Certified-Professional-Data-Engineer Exam Sample Questions 😠 New Databricks-Certified-Professional-Data-Engineer Test Answers 🐅 Search on “ www.pass4test.com ” for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ to obtain exam materials for free download ❣Databricks-Certified-Professional-Data-Engineer Brain Dump Free
- Pass Guaranteed Quiz 2026 Marvelous Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Latest Test Format 🥰 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and download it for free on ( www.pdfvce.com ) website 🐁Databricks-Certified-Professional-Data-Engineer Reliable Test Labs
- 100% Pass Quiz 2026 Databricks Updated Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Latest Test Format 👏 Download ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free by simply searching on ➡ www.prepawayete.com ️⬅️ 💜Databricks-Certified-Professional-Data-Engineer Brain Dump Free
- Dumps Databricks-Certified-Professional-Data-Engineer Cost 🏞 Reliable Databricks-Certified-Professional-Data-Engineer Braindumps 📤 New Databricks-Certified-Professional-Data-Engineer Test Forum ➡ Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and obtain a free download on ➡ www.pdfvce.com ️⬅️ 🏬Dumps Databricks-Certified-Professional-Data-Engineer Cost
- Databricks-Certified-Professional-Data-Engineer Reliable Test Labs 🦮 Passing Databricks-Certified-Professional-Data-Engineer Score 🚉 Databricks-Certified-Professional-Data-Engineer Free Exam Dumps ⛪ Easily obtain free download of ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ by searching on ( www.troytecdumps.com ) 🆘Databricks-Certified-Professional-Data-Engineer Brain Dump Free
- 100% Pass Quiz 2026 Databricks Updated Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Latest Test Format 🥮 Download 【 Databricks-Certified-Professional-Data-Engineer 】 for free by simply entering “ www.pdfvce.com ” website 🕛Databricks-Certified-Professional-Data-Engineer Brain Dump Free
- Databricks Databricks-Certified-Professional-Data-Engineer Latest Test Format: Databricks Certified Professional Data Engineer Exam - www.troytecdumps.com One of 10 Leading Planform 💢 “ www.troytecdumps.com ” is best website to obtain 「 Databricks-Certified-Professional-Data-Engineer 」 for free download 😜Databricks-Certified-Professional-Data-Engineer Free Braindumps
- 2026 100% Pass-Rate Databricks-Certified-Professional-Data-Engineer Latest Test Format Help You Pass Databricks-Certified-Professional-Data-Engineer Easily 🧿 Immediately open 《 www.pdfvce.com 》 and search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to obtain a free download 🍑Databricks-Certified-Professional-Data-Engineer Braindump Free
- Get Latest Databricks Databricks-Certified-Professional-Data-Engineer Practice Test To Pass Exam 🚏 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 and download it for free on ▷ www.dumpsmaterials.com ◁ website 📎Databricks-Certified-Professional-Data-Engineer Free Braindumps
- New Databricks-Certified-Professional-Data-Engineer Test Question 🆎 Databricks-Certified-Professional-Data-Engineer Exam Sample Questions 🌰 Databricks-Certified-Professional-Data-Engineer Brain Dump Free ⏮ Download 「 Databricks-Certified-Professional-Data-Engineer 」 for free by simply searching on ☀ www.pdfvce.com ️☀️ 🎄Updated Databricks-Certified-Professional-Data-Engineer Dumps
- Dumps Databricks-Certified-Professional-Data-Engineer Cost 🥎 Reliable Databricks-Certified-Professional-Data-Engineer Braindumps 🐝 Databricks-Certified-Professional-Data-Engineer Test Pass4sure 🐳 Download 【 Databricks-Certified-Professional-Data-Engineer 】 for free by simply entering [ www.pdfdumps.com ] website 👽Databricks-Certified-Professional-Data-Engineer Exam Sample Questions
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes