In order to remain competitive in the market, our company has been keeping researching and developing of the new AI-200 exam questions. We are focused on offering the most comprehensive AI-200 study materials which cover all official tests. Now, we have launched some popular AI-200 training prep to meet your demands. And you will find the quality of the AI-200 learning quiz is the first-class and it is very convenient to download it.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
>> Exam AI-200 Cram Questions <<
Perhaps it was because of the work that there was not enough time to learn, or because the lack of the right method of learning led to a lot of time still failing to pass the AI-200 examination. Whether you are the first or the second or even more taking Microsoft examination, our AI-200 Exam Prep not only can help you to save much time and energy but also can help you pass the exam. In the other words, passing the exam once will no longer be a dream.
NEW QUESTION # 141
You are developing an AI-powered API that retrieves connection strings and API keys from Azure Key Vault.
You must configure a solution that provides the following security functionality:
* The API must authenticate to Key Vault without storing credentials in any application configuration files
* The identity used by the API must have only the minimum permissions necessary to read secrets.
* The configuration must minimize the blast radius if an identity or credential is compromised.
You need to implement a secure access strategy for the API.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
Detailed Explanation: The API should use a system-assigned managed identity so no application credential is stored or rotated by the development team. That identity should receive only the permission needed to read secret values: Key Vault Secrets User at the vault scope is materially narrower than Key Vault Administrator at subscription scope. Storing a secret value in App Configuration would violate the requirement to protect secrets and increases exposure. The corrected pair therefore implements both credential-free authentication and least-privilege authorization with a limited blast radius.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Azure Key Vault RBAC guide | Managed identities for Azure resources
NEW QUESTION # 142
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
* embedding (pgvector)
* department
* created_at
The application must return the top five most similar documents for a given query embedding only from the finance department. You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.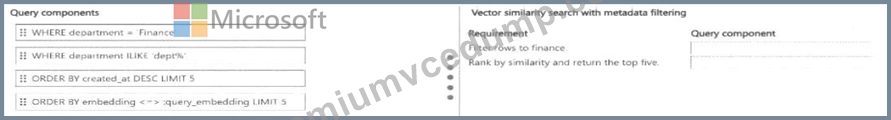
Answer:
Explanation: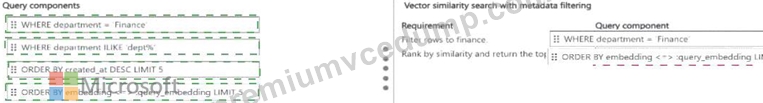
Explanation: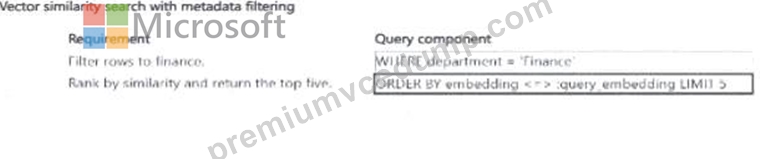
Verified Answer: Filter: `WHERE department = ' finance ' `. Rank/top five: `ORDER BY embedding < = > query_embedding LIMIT 5`.
Detailed Explanation: The metadata predicate must restrict the candidate rows to the Finance department, so the `WHERE department = ' finance ' ` component supplies the required filter. The pgvector cosine-distance operator ` < = > ` orders rows by vector distance to the supplied query embedding, and `LIMIT 5` keeps only the five nearest matches. Ordering by creation date would rank recency rather than semantic similarity, and a wildcard department filter would not satisfy the Finance-only requirement.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 143
You are configuring sampling for a distributed application that sends traces to Azure Monitor. The solution must:
* Preserve upstream sampling decisions across distributed traces
* Capture all spans during local testing.
* Sample 10 percent of traces in production.
You need to apply the appropriate sampling configuration for each requirement.
What should you do? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once or not at all. You may need to move the split bar Between panes or scroll to view content.
NOTE: Each correct selection is worth one point.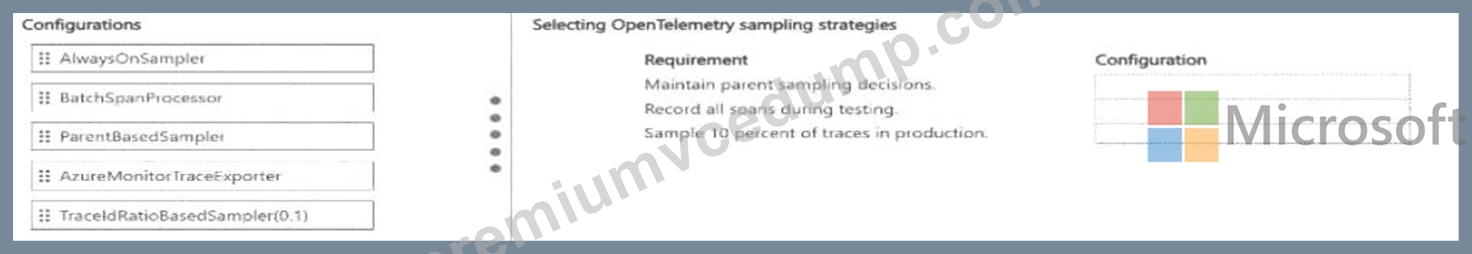
Answer:
Explanation: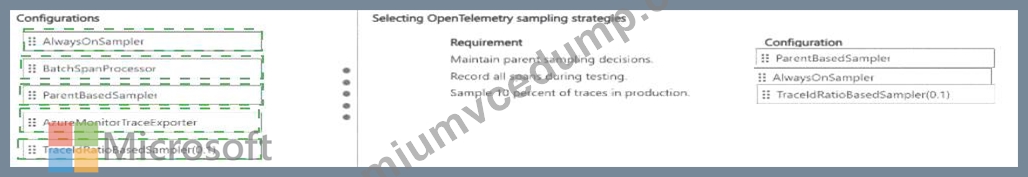
Explanation: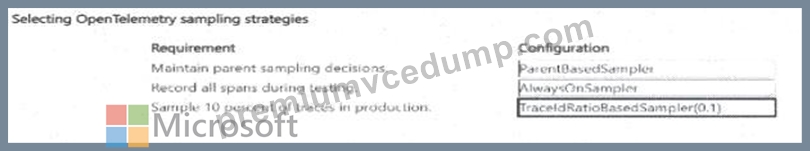
Verified answer: Preserve parent sampling decisions: ParentBasedSampler. Capture all spans locally:
AlwaysOnSampler. Sample 10% in production: TraceIdRatioBasedSampler(0.1).
Detailed Explanation: Parent-based sampling propagates the sampling decision from the upstream parent, preventing broken sampling decisions across a distributed trace. AlwaysOnSampler records every span, which is suitable for local test environments where complete trace visibility is more important than telemetry volume. TraceIdRatioBasedSampler with 0.1 selects approximately ten percent of traces based on trace identifiers, providing deterministic fixed-ratio sampling for production. A batch span processor and an exporter control processing/export, not the sampling decision itself.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | OpenTelemetry sampling in Azure Monitor | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 144
You optimize an AI inference API that uses Redis caching.
You must reduce the risk of serving outdated data while minimizing cache management overhead.
You need to implement the caching strategy that satisfies the requirements.
What should you do?
Answer: C
Explanation:
Trigger invalidation when source data changes is the best action.
Data Freshness: This is a proactive cache-aside or write-through approach. By explicitly deleting or updating the specific Redis key when the underlying database or model data changes, you completely eliminate the risk of serving stale data.
Low Overhead: It keeps cache management overhead minimal because invalidation logic is execution-dependent (event-driven). Instead of constantly updating expirations or relying on heavy computing logic, you only trigger an action when a write/change event occurs.
Incorrect:
[not B]
Set eviction policy to allkeys-lru:
This policy is a memory management feature, not a data-freshness strategy. It only deletes the Least Recently Used (LRU) keys when your Redis instance runs out of RAM. If memory usage is stable, outdated data will sit in the cache forever, posing a major risk of serving stale inferences.
[not D]
Reset expiration on each read (Sliding TTL):
This actively increases the risk of serving outdated data. If a specific AI response is highly popular and read continuously, its expiration window will extend indefinitely. The data remains stuck in the cache even if the source data undergoes critical updates.
Reference:
https://oneuptime.com/blog/post/2026-01-30-llm-caching-strategies/view
NEW QUESTION # 145
You are designing an Azure Function app that processes large image uploads submitted by users through an HTTP endpoint.
The solution must:
- Prevent client timeouts by decoupling image processing from the
initial upload request.
- Support automatic retry behavior for failed processing attempts.
- Scale the background processing independently of the rate of incoming HTTP uploads.
You need to design a scalable and reliable asynchronous processing solution.
Which two actions should you implement? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
To build a scalable and reliable asynchronous solution that meets the requirements, you should use an HTTP-triggered function to save images to Azure Blob Storage and enqueue a message, then use a Queue-triggered function to process the image.
1. Decouple via Queue Messaging
HTTP Function: Receives the initial user upload, saves the large image file directly to Azure Blob Storage, and writes a small metadata message (e.g., the blob URI) into an Azure Storage Queue or Azure Service Bus Queue.
Instant Response: The HTTP function immediately returns a 202 Accepted status to the client along with a status-tracking URL. This completely eliminates client timeout issues by shifting heavy work to the background.
2. Leverage Built-In Queue Triggers
Queue-Triggered Function: A second, separate Azure Function is configured to trigger whenever a new message lands in the queue. It downloads the image from Blob Storage and performs the processing.
Automatic Retries: Azure Queue storage and Service Bus triggers feature native retry behavior. If the processing function fails or crashes, the message is automatically returned to the queue to be retried. Persistent failures are automatically moved to a Poison Queue (Dead Letter Queue) after a configured number of attempts (default is 5).
Independent Scaling: Under the Azure Consumption or Premium plan, the Queue-triggered function scales its instances up or down based on the queue length (the backlog of images to process). This scales independently of the HTTP-triggered function, which scales purely based on incoming request volume.
Reference:
https://oneuptime.com/blog/post/2026-02-16-azure-functions-python-http-triggers-blob-storage/view
NEW QUESTION # 146
......
You can avoid this mess by selecting a trusted brand such as Exams. To buy real AI-200 Exam Dumps. The credible platform offers a product that is accessible in 3 formats: Microsoft AI-200 Dumps PDF, desktop practice exam software, and a web-based practice test. Any applicant of the AI-200 examination can choose from these preferable formats.
AI-200 Test Dumps Demo: https://www.premiumvcedump.com/Microsoft/valid-AI-200-premium-vce-exam-dumps.html