P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by PrepAwayETE: https://drive.google.com/open?id=1lqp3hZdIGzZwcIU0pzAsRsleWOFhYfA2
With the help of our Databricks-Certified-Data-Analyst-Associate training guide, your dream won’t be delayed anymore. Because, we have the merits of intelligent application and high-effectiveness to help our clients study more leisurely on our Databricks-Certified-Data-Analyst-Associate practice questions. If you prepare with our Data Analyst actual exam for 20 to 30 hours, the exam will become a piece of cake in front of you. And the pass rate of our Databricks-Certified-Data-Analyst-Associate learning guide is high as 98% to 100%, you will be satisfied with it if you buy it.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Securing Data | 8% | - Data governance policies - Secure storage and compliance - Access control and permissions |
| Topic 2: Data Modeling with Databricks SQL | 5% | - Schema design principles - Delta table structure - Performance-oriented modeling |
| Topic 3: Managing Data | 8% | - Unity Catalog usage - Data cleaning and preparation - Dataset versioning and management - Discovering and registering datasets |
| Topic 4: Understanding of Databricks Data Intelligence Platform | 11% | - Core architecture and components - Workspace navigation and interface - Lakehouse platform fundamentals |
| Topic 5: Executing Queries using Databricks SQL and Databricks SQL Warehouses | 20% | - Creating and managing views - Joining and combining datasets - Warehouse configuration and performance - Aggregations and grouping - ANSI SQL syntax and functions |
| Topic 6: Creating Dashboards and Visualizations in Databricks | 16% | - Scheduling and sharing dashboards - Visualization types and best practices - Dashboard creation and layout - Filtering and interactivity |
| Topic 7: Importing Data | 5% | - UI-based data ingestion - S3 and cloud storage integration - Delta Sharing - API and Auto Loader - Databricks Marketplace |
| Topic 8: Developing, Sharing, and Maintaining AI/BI Genie Spaces | 12% | - Access control and sharing - Maintenance and improvement - Genie space setup and configuration - Natural language query setup |
| Topic 9: Analyzing Queries | 15% | - Performance optimization - Query history and auditing - Execution plans and analysis - Liquid clustering and indexing |
>> Databricks Databricks-Certified-Data-Analyst-Associate Discount <<
Once you have practiced on our Databricks Certified Data Analyst Associate Exam test questions, the system will automatically memorize and analyze all your practice. You must finish the model test in limited time. There have a timer on the right of the interface. Once you begin to do the exercises of the Databricks-Certified-Data-Analyst-Associate test guide, the timer will start to work and count down. If you don’t finish doing the exercises, all your exercises of the Databricks-Certified-Data-Analyst-Associate Exam Questions will be delivered automatically. Then the system will generate a report according to your performance. You will clearly know where you are good at or not. Then you can make your own learning plans based on the report of the Databricks-Certified-Data-Analyst-Associate test guide. Also, you will do more practices that you are not good at until you completely have no problem.
NEW QUESTION # 42
A data analyst needs to share a Databricks SQL dashboard with stakeholders that are not permitted to have accounts in the Databricks deployment. The stakeholders need to be notified every time the dashboard is refreshed.
Which approach can the data analyst use to accomplish this task with minimal effort/
Answer: B
Explanation:
To share a Databricks SQL dashboard with stakeholders who do not have accounts in the Databricks deployment and ensure they are notified upon each refresh, the data analyst can add the stakeholders' email addresses to the dashboard's refresh schedule subscribers list. This approach allows the stakeholders to receive email notifications containing the latest dashboard updates without requiring them to have direct access to the Databricks workspace. This method is efficient and minimizes effort, as it automates the notification process and ensures stakeholders remain informed of the most recent data insights.
NEW QUESTION # 43
A data analyst at an e-commerce company needs to process daily sales data. The data consists of approximately 50,000 records stored in a single CSV file, totaling about 20 MB. The analyst needs to perform aggregations and generate a summary report.
Which approach could the data analyst use in this situation?
Answer: D
Explanation:
Option B is correct. A 20 MB CSV file with about 50,000 records is small enough for a local pandas workflow. A real-time streaming solution, a distributed Spark cluster, or Hadoop MapReduce would add unnecessary complexity for a small single-file batch analysis. Databricks documentation explains that pandas is available in Databricks Runtime and can be used for data analysis, while pandas API on Spark is useful when pandas-style workloads need to scale beyond smaller datasets. Databricks also notes that pandas does not scale out to big data, which is exactly why Spark or pandas API on Spark is used for larger workloads, not for a small 20 MB file.
NEW QUESTION # 44
After running DESCRIBE EXTENDED accounts.customers;, the following was returned: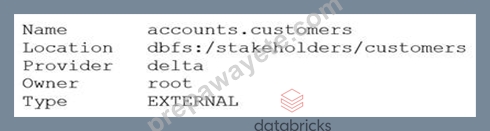
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
Answer: A
Explanation:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. Reference: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
NEW QUESTION # 45
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
Answer: E
Explanation:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.]table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. Reference: Databricks - DROP TABLE
NEW QUESTION # 46
A data analyst is working in an organization that utilizes a multi-hop, medallion architecture. They have been tasked with creating a new Gold table from an existing Silver table.
Which query is performing a hop from a Silver table to a Gold table?


Answer: A
Explanation:
Option C is the correct answer because it creates a new aggregated table, store_sales, from the existing cleaned
/refined table cleaned_transactions. In a medallion architecture, a table such as cleaned_transactions represents a Silver-layer table because it contains cleaned or validated transaction-level data. The query then creates store_sales by grouping by store_id and calculating SUM(sales), which is an aggregation suitable for analytics and reporting. That is exactly the Silver-to-Gold hop.
Option A creates cleaned_transactions from transactions, so it is moving toward a cleaned Silver table, not creating a Gold table. Option B creates transactions from raw_transactions, which is closer to a raw-to-Bronze or Bronze preparation step. Option D filters rows from transactions into cleaned_transactions, which is also a cleaning/validation step associated with Silver, not Gold.
Exact extract from official Databricks documentation: Databricks describes medallion architecture as improving data through "Bronze # Silver # Gold layer tables." The same official page identifies Silver as
"Data cleaning and validation" and Gold as "Dimensional modeling and aggregation." Databricks also states that the Gold layer "consists of aggregated data tailored for analytics and reporting."
NEW QUESTION # 47
......
For the candidates, getting access to the latest Databricks Databricks-Certified-Data-Analyst-Associate practice test material takes a lot of work. The study materials for the Databricks-Certified-Data-Analyst-Associate test preparation are spread throughout a number of websites and the majority of them aren't updated. However, the applicants only have a short time to prepare for the Databricks Databricks-Certified-Data-Analyst-Associate Exam. They want a platform that offers the latest and real Databricks-Certified-Data-Analyst-Associate exam questions so they can get prepared within a few days.
Databricks-Certified-Data-Analyst-Associate Test Discount Voucher: https://www.prepawayete.com/Databricks/Databricks-Certified-Data-Analyst-Associate-practice-exam-dumps.html
BTW, DOWNLOAD part of PrepAwayETE Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1lqp3hZdIGzZwcIU0pzAsRsleWOFhYfA2