BONUS!!! Download part of Prep4sureExam Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1cR1y8u4K2Qch6C4PtMmg77Kt8zhvCAp7
Databricks Databricks-Generative-AI-Engineer-Associate test braindump will be the right key to your exam success. As long as the road is right, success is near. Don't be over-anxious, wasting time is robbing oneself. Our Databricks Databricks-Generative-AI-Engineer-Associate test braindump will be definitely useful for your test and 100% valid. Money Back Guaranteed!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Pdf Version <<
The Databricks wants to become the first choice for quick and complete Databricks Databricks-Generative-AI-Engineer-Associate exam preparation. To achieve this objective the Databricks has hired a team of experienced and qualified Databricks-Generative-AI-Engineer-Associate Exam trainers. They have years of experience in verifying Databricks Certified Generative AI Engineer Associate exam practice test questions.
NEW QUESTION # 28
A Generative Al Engineer is building a system which will answer questions on latest stock news articles.
Which will NOT help with ensuring the outputs are relevant to financial news?
Answer: B
Explanation:
In the context of ensuring that outputs are relevant to financial news, increasing compute power (option B) does not directly improve the relevance of the LLM-generated outputs. Here's why:
Compute Power and Relevancy:
Increasing compute power can help the model process inputs faster, but it does not inherently improve the relevance of the answers. Relevancy depends on the data sources, the retrieval method, and the filtering mechanisms in place, not on how quickly the model processes the query.
What Actually Helps with Relevance:
Other methods, like content filtering, guardrails, or manual review, can directly impact the relevance of the model's responses by ensuring the model focuses on pertinent financial content. These methods help tailor the LLM's responses to the financial domain and avoid irrelevant or harmful outputs.
Why Other Options Are More Relevant:
A (Comprehensive Guardrail Framework): This will ensure that the model avoids generating content that is irrelevant or inappropriate in the finance sector.
C (Profanity Filter): While not directly related to financial relevancy, ensuring the output is clean and professional is still important in maintaining the quality of responses.
D (Manual Review): Incorporating human oversight to catch and correct issues with the LLM's output ensures the final answers are aligned with financial content expectations.
Thus, increasing compute power does not help with ensuring the outputs are more relevant to financial news, making option B the correct answer.
NEW QUESTION # 29
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: B
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 30
A company has a typical RAG-enabled, customer-facing chatbot on its website.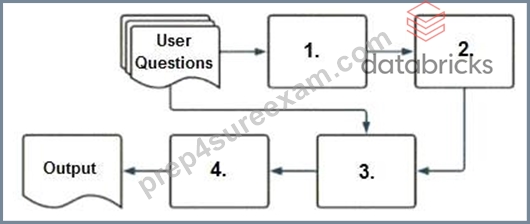
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.
Answer: A
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user ' s question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1) : The first step involves the user ' s question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2) : The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3) : The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4) : Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable :
* B, C, D : These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response- generating LLM , which is option A.
NEW QUESTION # 31
Databricks offers a number of built-in AI judges that provide metrics and rationale for different types of quality issues a Generative AI application may have.
Which of the following pairs of judges both require a ground-truth label in the evaluation dataset field expected_response to execute?
Answer: A
Explanation:
In the Agent Evaluation terminology used by this question, correctness compares the generated response with the expected answer, while context_sufficiency determines whether the retrieved context contains enough information to produce that expected answer. Both therefore depend on ground-truth information supplied through expected_response. Groundedness instead examines whether the response is supported by the retrieved context; it does not inherently need a reference answer. Chunk relevance and relevance to the query assess alignment with the user's request, while guideline adherence evaluates compliance with specified instructions. Databricks explicitly distinguishes the ground-truth-dependent judges in its migration documentation. In MLflow 3, names and schemas have evolved, including expectations.expected_response and explicitly selected scorers, so the question should be interpreted using its stated legacy judge terminology.
Databricks documentation
NEW QUESTION # 32
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Answer: B
Explanation:
* Problem Context: The goal is to monitor the serving endpoint for incoming requests and outgoing responses in a provisioned throughput model serving endpoint within a Retrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
* Explanation of Options:
Option A: Vector Search: This feature is used to perform similarity searches within vector databases. It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
Option D: Inference Tables: This is the correct answer. Inference Tables in Databricks are designed to store the results and metadata of inference runs. This allows the system to log incoming requests and outgoing responses directly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus, Inference Tables are the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
NEW QUESTION # 33
......
The Prep4sureExam is committed to presenting the excellent viable observe cloth to prevail within the Databricks Databricks-Generative-AI-Engineer-Associate examination. With actual PDF questions, customizable exercise checks, and 24/7 guide, customers can be assured that they're getting the fine possible prep cloth. The Databricks-Generative-AI-Engineer-Associate is a fantastic choice for absolutely everyone looking to increase their profession with the Databricks-Generative-AI-Engineer-Associate certification. Purchase Now.
Databricks-Generative-AI-Engineer-Associate Test Lab Questions: https://www.prep4sureexam.com/Databricks-Generative-AI-Engineer-Associate-dumps-torrent.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Prep4sureExam: https://drive.google.com/open?id=1cR1y8u4K2Qch6C4PtMmg77Kt8zhvCAp7