P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Zertpruefung verfügbar: https://drive.google.com/open?id=1eHfUwgb6tBaeuWp_TGPru1muJ9lBKJYM
Die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung ist der erste Schritt zum Berufserfolg fur IT-Fachleute. Durch die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung haben Sie schon den ersten Fuß auf die Spitze Ihrer Karriere gesetzt. Zertpruefung wird Ihnen helfen, die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung zu bestehen.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Passing Score: | Not officially published, approximately 70% |
| Exam Duration: | 120 minutes |
| Related Certifications: | Google Cloud Professional Data Engineer Google Cloud Professional Cloud Architect |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 50-60 |
| Exam Price: | $200 USD (plus tax where applicable) |
| Available Languages: | English, Japanese |
| Exam Format: | Multiple select, Multiple choice |
| Recommended Training: | Official Exam Guide Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer Deutsche Prüfungsfragen <<
Die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bestehen aus Testfragen sowie Antworten, die von den erfahrenen IT-Experten aus Zertpruefung durch ihre Praxis und Erforschungen entworfen werden. Die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung sind zur Zeit die genaueste auf dem Markt. Sie können die Demo auf der Webseite Zertpruefung.de herunterladen. Sie werden Ihr Helfer sein, während Sie sich auf die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung vorbereiten.
Die Google Professional Machine Learning Engineer -Zertifizierung ist in der Branche hoch geschätzt und kann zu hervorragenden Karrieremöglichkeiten für Personen mit Fachkenntnissen in diesem Bereich führen. Diese Zertifizierung ist ein Beweis für die Fähigkeit eines Kandidaten, Modelle für maschinelles Lernen zu entwerfen, zu entwickeln und bereitzustellen, und es kann ein wertvolles Gut für alle sein, die eine Karriere im maschinellen Lernen oder in der Datenwissenschaft suchen. Darüber hinaus zeigt die Zertifizierung das Wissen eines Kandidaten in Google Cloud-Technologien und deren Fähigkeit, sie effektiv zu verwenden, um reale Probleme zu lösen.
151. Frage
As the lead ML Engineer for your company, you are responsible for building ML models to digitize scanned customer forms. You have developed a TensorFlow model that converts the scanned images into text and stores them in Cloud Storage. You need to use your ML model on the aggregated data collected at the end of each day with minimal manual intervention. What should you do?
Antwort: B
Begründung:
Batch prediction is the process of using an ML model to make predictions on a large set of data points. Batch prediction is suitable for scenarios where the predictions are not time-sensitive and can be done in batches, such as digitizing scanned customer forms at the end of each day. Batch prediction can also handle large volumes of data and scale up or down the resources as needed. AI Platform provides a batch prediction service that allows users to submit a job with their TensorFlow model and input data stored in Cloud Storage, and receive the output predictions in Cloud Storage as well. This service requires minimal manual intervention and can be automated with Cloud Scheduler or Cloud Functions. Therefore, using the batch prediction functionality of AI Platform is the best option for this use case.
Reference:
Batch prediction overview
Using batch prediction
152. Frage
You are an ML engineer at a global shoe store. You manage the ML models for the company's website. You are asked to build a model that will recommend new products to the user based on their purchase behavior and similarity with other users. What should you do?
Antwort: B
Begründung:
Collaborative filtering is a technique that recommends items to users based on the ratings of other users. It works by finding users who have similar ratings to the current user and then recommending items that those users have liked.
https://cloud.google.com/architecture/recommendations-using-machine-learning-on-compute-engine#filtering_the_data
153. Frage
You developed a Vertex AI ML pipeline that consists of preprocessing and training steps and each set of steps runs on a separate custom Docker image. Your organization uses GitHub and GitHub Actions as CI/CD to run unit and integration tests. You need to automate the model retraining workflow so that it can be initiated both manually and when a new version of the code is merged in the main branch. You want to minimize the steps required to build the workflow while also allowing for maximum flexibility. How should you configure the CI/CD workflow?
Antwort: A
154. Frage
You have trained a text classification model in TensorFlow using Al Platform. You want to use the trained model for batch predictions on text data stored in BigQuery while minimizing computational overhead. What should you do?
Antwort: B
Begründung:
This answer is correct because it allows you to use the trained TensorFlow model for batch predictions on text data stored in BigQuery without any additional processing or overhead. Al Platform provides a service for running batch prediction jobs that can take input data from BigQuery or Cloud Storage and write the output to BigQuery or Cloud Storage. You can use the SavedModel format to export your TensorFlow model to Cloud Storage and then submit a batch prediction job that points to the model location and the input data location. Al Platform will handle the scaling and distribution of the prediction requests and return the results in the specified output location. References:
* [Al Platform: Batch prediction overview]
* [Al Platform: Exporting a SavedModel for prediction]
155. Frage
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?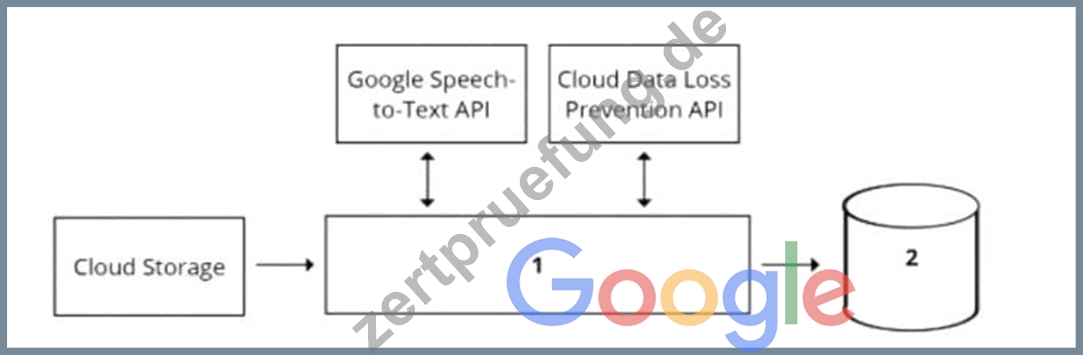
Antwort: A
Begründung:
A data pipeline is a set of steps or processes that move data from one or more sources to one or more destinations, usually for the purpose of analysis, transformation, or storage. A data pipeline can be designed using various components, such as data sources, data processing tools, data storage systems, and data analytics tools1 To design a data pipeline for analyzing customer sentiments in each call, one should consider the following requirements and constraints:
* The call center receives over one million calls daily, and data is stored in Cloud Storage. This implies that the data is large, unstructured, and distributed, and requires a scalable and efficient data processing tool that can handle various types of data formats, such as audio, text, or image.
* The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. This implies that the data is sensitive and subject to data
* privacy and compliance regulations, and requires a secure and reliable data storage system that can enforce data encryption, access control, and regional policies.
* The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. This implies that the data analytics tool is external and independent of the data pipeline, and requires a standard and compatible data interface that can support SQL queries and operations.
One of the best options for selecting components for data processing and for analytics is to use Dataflow for data processing and BigQuery for analytics. Dataflow is a fully managed service for executing Apache Beam pipelines for data processing, such as batch or stream processing, extract-transform-load (ETL), or data integration. BigQuery is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data23 Using Dataflow and BigQuery has several advantages for this use case:
* Dataflow can process large and unstructured data from Cloud Storage in a parallel and distributed manner, and apply various transformations, such as converting audio to text, extracting sentiment scores, or anonymizing PII. Dataflow can also handle both batch and stream processing, which can enable real-time or near-real-time analysis of the call data.
* BigQuery can store and analyze the processed data from Dataflow in a secure and reliable way, and enforce data encryption, access control, and regional policies. BigQuery can also support SQL ANSI-2011 compliant interface, which can enable the data science team to use their third-party tool for visualization and access. BigQuery can also integrate with various Google Cloud services and tools, such as AI Platform, Data Studio, or Looker.
* Dataflow and BigQuery can work seamlessly together, as they are both part of the Google Cloud ecosystem, and support various data formats, such as CSV, JSON, Avro, or Parquet. Dataflow and BigQuery can also leverage the benefits of Google Cloud infrastructure, such as scalability, performance, and cost-effectiveness.
The other options are not as suitable or feasible. Using Pub/Sub for data processing and Datastore for analytics is not ideal, as Pub/Sub is mainly designed for event-driven and asynchronous messaging, not data processing, and Datastore is mainly designed for low-latency and high-throughput key-value operations, not analytics.
Using Cloud Function for data processing and Cloud SQL for analytics is not optimal, as Cloud Function has limitations on the memory, CPU, and execution time, and does not support complex data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data. Using Cloud Composer for data processing and Cloud SQL for analytics is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, not data processing, and Cloud SQL is a relational database service that may not scale well for large-scale data.
References: 1: Data pipeline 2: Dataflow overview 3: BigQuery overview : [Dataflow documentation] :
[BigQuery documentation]
156. Frage
......
Professional-Machine-Learning-Engineer Exam: https://www.zertpruefung.de/Professional-Machine-Learning-Engineer_exam.html
2026 Die neuesten Zertpruefung Professional-Machine-Learning-Engineer PDF-Versionen Prüfungsfragen und Professional-Machine-Learning-Engineer Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1eHfUwgb6tBaeuWp_TGPru1muJ9lBKJYM