NVIDIA NCP-AII Actual Exam - Latest NCP-AII Exam Experience

DOWNLOAD the newest TestValid NCP-AII PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1b_kk60p4KMBNqFepjRejhgGi13_GFfYV
Do you want to get the NCP-AII certification to boost your career? Do you desire to feel competent and confident going into your real NVIDIA AI Infrastructure certification exam? Real NCP-AII Exam Questions are available right here at TestValid, so don't waste your time going elsewhere. By practicing with our Real NCP-AII Exam Questions, which are offered in NCP-AII PDF, web-based practice test, and desktop practice exam software formats, you can crack your NVIDIA AI Infrastructure (NCP-AII) certification test on first attempt and advance in the NVIDIA industry.
NVIDIA NCP-AII Exam Overview:
| Certification Vendor: | NVIDIA |
|---|
| Exam Name: | NVIDIA Certified Professional – AI Infrastructure |
|---|
| Exam Number: | NCP-AII |
|---|
| Exam Format: | Multiple Select, Multiple Choice |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Passing Score: | 700 (scale of 0-1000) |
|---|
| Related Certifications: | NCP-DES
NCP-AI |
|---|
| Available Languages: | English |
|---|
| Exam Duration: | 90 minutes |
|---|
| Exam Price: | $195 USD |
|---|
| Real Exam Qty: | 50 |
|---|
| Sample Questions: | NVIDIA NCP-AII Sample Questions |
|---|
| Exam Way: | Online proctored exam (Pearson VUE) |
|---|
| Pre Condition: | Recommended: hands-on experience with NVIDIA AI infrastructure products; basic knowledge of Linux, networking, and data center operations |
|---|
| Official Syllabus URL: | https://www.nvidia.com/en-us/certifications/ncp-ai-infra/ |
|---|
>> NVIDIA NCP-AII Actual Exam <<
Updated NVIDIA NCP-AII Questions - Fast Track To Get Success
There are quite a few candidates of NCP-AII certification exam have already started his career, and there are many examinees facing other challenges in life, so we provide candidates with the most efficient review method of NCP-AII exam. In order to let you be rest assured to purchase our products, we offer a variety of versions of the samples of NCP-AII Study Materials for your trial. We've helped countless examinees pass NCP-AII exam, so we hope you can realize the benefits of our software that bring to you.
| Topic | Details |
|---|
| Topic 1 | - Physical Layer Management: Covers configuring BlueField network platform devices and setting up Multi-Instance GPU (MIG) partitioning for AI and HPC workloads.
|
| Topic 2 | - Troubleshoot and Optimize: Covers identifying and replacing faulty hardware components such as GPUs, network cards, and power supplies, along with performance optimization for AMD
- Intel servers and storage.
|
| Topic 3 | - Control Plane Installation and Configuration: Covers deploying the software stack including Base Command Manager, OS, Slurm
- Enroot
- Pyxis, NVIDIA GPU and DOCA drivers, container toolkit, and NGC CLI.
|
| Topic 4 | - System and Server Bring-up: Covers end-to-end physical setup of GPU-based AI infrastructure, including BMC
- OOB
- TPM configuration, firmware upgrades, hardware installation, and power and cooling validation to ensure servers are workload-ready.
|
| Topic 5 | - Cluster Test and Verification: Covers full cluster validation through HPL and NCCL benchmarks, NVLink and fabric bandwidth tests, cable and firmware checks, and burn-in testing using HPL, NCCL, and NeMo.
|
NVIDIA AI Infrastructure Sample Questions (Q88-Q93):
NEW QUESTION # 88
You are tasked with installing the NGC CLI on a host that does not have direct internet access. You have downloaded the NGC CLI package to a local repository. Which of the following steps are required to successfully install and configure the NGC CLI in this offline environment?
- A. Configure the NGC CLI to point to your local package repository by setting the environment variable.
- B. Transfer the NGC CLI package to the host and install it using 'pip install .whl'.
- C. Run 'ngc config set' to configure the API key, pointing to a local configuration file.
- D. Manually download and install all dependencies of the NGC CLI package using 'pip install --no-index --find-links=/path/to/dependencies .whl'.
- E. Only copying the whl file is sufficient, NGC CLI dependencies are always local
Answer: A,B,C,D
Explanation:
In an offline environment, you need to install the package locally (A), configure the CLI to know where to find the package (B), manually install dependencies (C), and configure the API key (D). Option E is wrong because dependencies must be handled manually in the offline environment.
NEW QUESTION # 89
You are an infrastructure engineer tasked with validating a new AI training cluster before releasing it to users.
Your team wants to perform a NeMo burn-in to ensure both hardware and software are reliable and ready for production workloads. Which of the following actions are required as part of a proper NeMo burn-in process?
Pick the 2 correct responses below.
- A. Configure a representative NeMo training or pretraining recipe and set up an executor to launch the job across intended nodes and GPUs.
- B. Download a pre-trained NeMo model and use it for a quick accuracy check on a user dataset, then consider the burn-in complete if results are reasonable.
- C. Run the configured NeMo training job repeatedly or for an extended duration, monitoring for errors, stalls, or performance drops across all GPUs and nodes.
- D. Test inference using the NeMo API and approve the environment if the model outputs valid predictions.
Answer: A,C
Explanation:
A proper NeMo burn-in should use a representative training or pretraining workload and run it for a sustained period across the intended GPUs and nodes. The goal is not only to prove that NeMo can import or that a model can return an inference result. The goal is to exercise the full AI infrastructure path: GPUs, CPU memory, CUDA, NCCL, network fabric, storage, container runtime, scheduler integration, and framework stack. Configuring a representative NeMo recipe and executor ensures the job launches with realistic distributed-training behavior and uses the same type of resources expected in production. Running the job repeatedly or for an extended duration helps expose intermittent issues such as NCCL stalls, GPU Xid errors, storage slowdowns, thermal throttling, node instability, or performance regression. A quick accuracy check on a pre-trained model is not a burn-in because it does not adequately stress distributed training. Inference-only testing is also insufficient for validating a training cluster. NeMo burn-in is valuable because it validates both the software framework and the underlying NVIDIA AI infrastructure under realistic workload pressure.
NEW QUESTION # 90
During cluster deployment, the UFM Cable Validation Tool reports "Wrong-neighbor" errors on multiple InfiniBand links. What is the most efficient way to resolve this issue?
- A. Disable FEC on all switches to bypass neighbor validation.
- B. Verify LLDP data against topology files and remediate.
- C. Reboot all leaf switches to force LLDP rediscovery.
- D. Replace all affected cables with higher-grade OM5 fiber optics.
Answer: B
Explanation:
"Wrong-neighbor" errors indicate that the discovered cable peer does not match the expected topology. The efficient resolution is to compare LLDP-discovered neighbor data with the planned topology files, identify the mismatched links, and correct the cabling or topology definition accordingly.
NEW QUESTION # 91
A system administrator needs to install a container toolkit and successfully run the following commands:
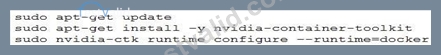
What step should be taken next to finish the installation?
- A. dpkg -i doca-host-repo-ubuntu<version>_am64.deb</version>
- B. apt-get install cuda-drivers
- C. systemctl restart docker
- D. apt-get remove nvidia-container-toolkit for
Answer: C
Explanation:
After configuring the NVIDIA Container Toolkit runtime for Docker with nvidia-ctk runtime configure --runtime=docker, Docker must be restarted so it reloads the updated runtime configuration and can run GPU-enabled containers correctly.
NEW QUESTION # 92
You've installed a server with multiple NVIDIAAIOO GPUs intended for use with Kubernetes and NVIDIA's GPU Operaton After installing the GPU Operator, you notice that the GPUs are not being properly detected and managed by Kubernetes. Which of the following are potential causes and troubleshooting steps you should take?
- A. The GPU Operator's configuration is incorrect, preventing it from properly discovering and managing the GPUs. Check the GPU Operator's logs and configuration files.
- B. The NVIDIA Container Toolkit is not installed on the Kubernetes nodes. Install the toolkit according to NVIDIA's documentation.
- C. The NVIDIA drivers are not properly installed on the host operating system before installing the GPU Operator. Verify the driver installation using 'nvidia-smr.
- D. The Kubernetes nodes are not labeled correctly to indicate the presence of NVIDIA GPUs. Use 'kubectl label node nvidia.com/gpu.present=true'.
- E. The 'nvidia-docker2 runtime is not set as the default runtime in '/etc/docker/daemon.json' . Change the default runtime to 'nvidia' and restart the Docker daemon.
Answer: A,B,C,D
Explanation:
All the options are valid reasons. The NVIDIA driver must be present on the host, the nodes need to be labelled to be recongnized by the Kubernetes, container tookit is required for running GPU enabled container and configuration of GPU operator must be correct.
NEW QUESTION # 93
......
Latest NCP-AII Exam Experience: https://www.testvalid.com/NCP-AII-exam-collection.html
- NCP-AII Certified Questions 📥 NCP-AII Certified Questions 🤸 Practice NCP-AII Tests 💈 Immediately open ☀ www.testkingpass.com ️☀️ and search for ✔ NCP-AII ️✔️ to obtain a free download 🏂NCP-AII Valid Test Pass4sure
- Certification NCP-AII Test Answers 🦃 NCP-AII Exam Vce Free 🐱 NCP-AII Practice Engine 📴 The page for free download of ☀ NCP-AII ️☀️ on ✔ www.pdfvce.com ️✔️ will open immediately 🚓NCP-AII Reliable Test Guide
- NVIDIA - NCP-AII - Fantastic NVIDIA AI Infrastructure Actual Exam 🎓 Search for ⮆ NCP-AII ⮄ and easily obtain a free download on “ www.validtorrent.com ” 🏥Exam NCP-AII Forum
- Valid NCP-AII Exam Syllabus 🃏 Valid NCP-AII Exam Syllabus 🎉 NCP-AII Reliable Test Guide 🕖 Easily obtain 《 NCP-AII 》 for free download through “ www.pdfvce.com ” 🎹NCP-AII Free Download Pdf
- NVIDIA NCP-AII Exam | NCP-AII Actual Exam - Updated Download Latest NCP-AII Exam Experience 🧬 Simply search for “ NCP-AII ” for free download on ⇛ www.dumpsmaterials.com ⇚ 🏵NCP-AII Free Download Pdf
- NCP-AII Reliable Test Guide 🚃 Exam NCP-AII Forum 💭 Exam NCP-AII Forum 🧰 Easily obtain ➡ NCP-AII ️⬅️ for free download through ⮆ www.pdfvce.com ⮄ 💨Vce NCP-AII Test Simulator
- Exam Dumps NCP-AII Collection 🐂 NCP-AII Free Download Pdf 🧨 NCP-AII Reliable Test Guide 📘 Download { NCP-AII } for free by simply entering ➡ www.troytecdumps.com ️⬅️ website 💃Exam NCP-AII Forum
- Reliable NCP-AII Braindumps Questions 🈵 Practice NCP-AII Tests 🦱 Practice NCP-AII Tests 🏴 Search for ▷ NCP-AII ◁ and download it for free on ⏩ www.pdfvce.com ⏪ website ☘NCP-AII Lead2pass
- Latest NCP-AII Cram Materials 🐩 NCP-AII Practice Engine 🐆 NCP-AII Valid Test Pass4sure 🤟 ⇛ www.pass4test.com ⇚ is best website to obtain ▶ NCP-AII ◀ for free download 🆑NCP-AII Reliable Test Guide
- Newest NCP-AII Exam Collection - NCP-AII Practice Torrent - NCP-AII Actual Pdf ⚔ Simply search for ✔ NCP-AII ️✔️ for free download on ⇛ www.pdfvce.com ⇚ 🦡NCP-AII Practice Engine
- NVIDIA NCP-AII Exam | NCP-AII Actual Exam - High Pass Rate Latest NCP-AII Exam Experience 🍑 Search for “ NCP-AII ” and download it for free immediately on 「 www.pass4test.com 」 🖊Reliable NCP-AII Braindumps Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fortunetelleroracle.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest TestValid NCP-AII PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1b_kk60p4KMBNqFepjRejhgGi13_GFfYV