What's more, part of that Actual4Dumps Workday-Pro-Integrations dumps now are free: https://drive.google.com/open?id=1B7Z2DYyFL9O53jdnPOqy-OiETgVtoFcT
Since the childhood, we seem to have been studying and learning seems to take part in different kinds of the purpose of the test, at the same time, we always habitually use a person's score to evaluate his ability. And our Workday-Pro-Integrations real study braindumps can help you get better and better reviews. This is a very intuitive standard, but sometimes it is not enough comprehensive, therefore, we need to know the importance of getting the test Workday-Pro-Integrations Certification, qualification certificate for our future job and development is an important role. Only when we have enough qualifications to prove our ability can we defeat our opponents in the harsh reality. We believe our Workday-Pro-Integrations actual question will help you pass the qualification examination and get your qualification certificate faster and more efficiently.
| Section | Objectives |
|---|---|
| Topic 1: Integration Fundamentals | - Integration architecture concepts in Workday
|
| Topic 2: Enterprise Interface Builder (EIB) | - Outbound integrations
|
| Topic 3: Core Integration Tools | - Workday Studio concepts
|
| Topic 4: Data Transformation | - XSLT and mapping concepts
|
| Topic 5: Operations and Maintenance | - Monitoring integrations
|
>> Workday-Pro-Integrations Reliable Study Notes <<
When you grasp the key points to attend the Workday-Pro-Integrations exam, nothing will be difficult for you anymore. Our professional experts are good at compiling the Workday-Pro-Integrations training guide with the most important information. They have been in this career for over ten years, and they know every detail about the Workday-Pro-Integrations Exam no matter on the content but also on the displays. Believe in our Workday-Pro-Integrations practice braindumps, and your success is 100% guaranteed!
NEW QUESTION # 18
Refer to the following scenario to answer the question below.
You are configuring a Core Connector: Worker integration with the Data Initialization Service (DIS) enabled.
The integration must extract worker contact details and job information, including a calculated field override that determines phone allowance eligibility.
You need to review and correct the security configuration so that all overrides are secured appropriately and data is successfully extracted, resolving any security issues that arise when testing runs of the integration.
While troubleshooting issues with the connector, you are looking for a report which allows you to see how a given item is secured.
What report or task would assist you in this?
Answer: C
Explanation:
When troubleshooting Workday integration security, the key question is often which domain security policies secure a particular field, report, web service, or task. View Security for Securable Item is designed for that purpose. It allows the administrator to inspect how a specific securable item is protected and identify the security domains and permissions involved. Security Analysis for Security Groups focuses on a security group's access, and Security Analysis for Workday Account focuses on what a user account can access.
Maintain Permissions for Security Group is used to manage permissions, not to diagnose how a specific item is secured. Since the requirement is to investigate security for a given item, View Security for Securable Item is the correct diagnostic tool.
NEW QUESTION # 19
You are creating an outbound connector using the Core Connector: Job Postings template. The vendor has provided the following specification for worker subtype values: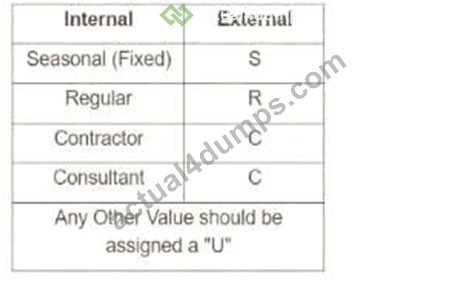
The vendor has also requested that any output file have the following format "CC_Job_Postings_dd-mm-yy_#.
xml". Where the dd is the current day at runtime, mm is the current month at runtime, yy is the last two digits of the current year at runtime, and # is the current value of the sequencer at runtime. What configuration step (s) must you complete to meet the vender requirements?
Answer: B
Explanation:
This question involves configuring an outbound connector using the Core Connector: Job Postings template in Workday Pro Integrations. We need to meet two specific vendor requirements:
* Map worker subtype values according to the provided table (e.g., Seasonal (Fixed) = "S", Regular =
"R", Contractor = "C", Consultant = "C", and any other value = "U").
* Format the output file name as "CC_Job_Postings_dd-mm-yy_#.xml", where:
* "dd" is the current day at runtime,
* "mm" is the current month at runtime,
* "yy" is the last two digits of the current year at runtime,
* "#" is the current value of the sequencer at runtime.
Let's break down the requirements and evaluate each option to determine the correct configuration steps.
Understanding the Requirements
1. Worker Subtype Mapping
The vendor provides a table for worker subtype values:
* Internal Seasonal (Fixed) maps to "S"
* Internal Regular maps to "R"
* Internal Contractor maps to "C"
* Internal Consultant maps to "C"
* Any other value should be assigned "U"
In Workday, worker subtypes are typically part of the worker data, and for integrations, we use integration mappings to transform these values into the format required by the vendor. The integration mapping allows us to define how internal Workday values (e.g., worker subtypes) map to external values (e.g., "S", "R", "C",
"U"). If no specific mapping exists for a value, we need to set a default value of "U" for any unmatched subtypes, as specified.
This mapping is configured in the integration system's "Integration Mapping" or "Field Mapping" settings, depending on the template. For the Core Connector: Job Postings, we typically use the"Integration Mapping" feature to handle data transformations, including setting default values for unmapped data.
2. Output File Name Format
The vendor requires the output file to be named "CC_Job_Postings_dd-mm-yy_#.xml", where:
* "CC_Job_Postings" is a static prefix,
* "dd-mm-yy" represents the current date at runtime (day, month, last two digits of the year),
* "#" is the current value from a sequence generator (sequencer) at runtime.
In Workday, file names for integrations are configured in the "File Utility" or "File Output" settings of the integration. To achieve this format:
* The date portion ("dd-mm-yy") can be dynamically generated using Workday's date functions or runtime variables, often configured in the File Utility's "Filename" field with a "Determine Value at Runtime" setting.
* The sequence number ("#") requires a sequence generator, which is enabled and configured to provide a unique incrementing number for each file. Workday uses the "Sequence Generator" feature for this purpose, typically accessed via the "Create ID Definition / Sequence Generator" task.
The Core Connector: Job Postings template supports these configurations, allowing us to set filename patterns in the integration's setup.
Evaluating Each Option
Let's analyze each option step by step, ensuring alignment with Workday Pro Integrations best practices and the vendor's requirements.
Option A:
* Enable the Sequence Generator Field Attribute* Configure the Sequence Generator* Configure the Worker Sub Type Integration Mapping leaving the default value blank Analysis:
* Sequence Generator Configuration:Enabling the "Sequence Generator Field Attribute" and configuring the sequence generator is partially correct for the file name's "#" (sequencer) requirement.
However, "Sequence Generator Field Attribute" is not a standard term in Workday; it might refer to enabling a sequence generator in a field mapping, but this is unclear and likely incorrect. Sequence generators are typically enabled as an "Integration Service" or configured in the File Utility, not as a field attribute.
* Worker Subtype Mapping:Configuring the worker subtype integration mapping but leaving the default value blank is problematic. The vendor requires any unmapped value to be "U," so leaving it blank would result in missing or null values, failing to meet the requirement.
* Date in Filename:This option doesn't mention configuring the date ("dd-mm-yy") in the filename, which is critical for the "CC_Job_Postings_dd-mm-yy_#.xml" format.
* Conclusion:This option is incomplete and incorrect because it doesn't address the default "U" for unmapped subtypes and lacks date configuration for the filename.
Option B:
* Enable the Integration Mapping Field Attribute* Configure the Worker Sub Type Integration Mapping leaving the default value blank* Configure the Sequence Generator Analysis:
* Sequence Generator Configuration:Configuring the sequence generator addresses the "#" (sequencer) in the filename, which is correct for the file name requirement.
* Worker Subtype Mapping:Similar to Option A, leaving the default value blank for the worker subtype mapping fails to meet the vendor's requirement for "U" as the default for unmapped values.
This would result in errors or null outputs, which is unacceptable.
* Date in Filename:Like Option A, there's no mention of configuring the date ("dd-mm-yy") in the filename, making this incomplete for the full file name format.
* Integration Mapping Field Attribute:This term is ambiguous. Workday uses "Integration Mapping" or "Field Mapping" for data transformations, but "Field Attribute" isn't standard for enabling mappings.
This suggests a misunderstanding of Workday's configuration.
* Conclusion:This option is incomplete and incorrect due to the missing default "U" for worker subtypes and lack of date configuration for the filename.
Option C:
* Enable the Integration Mapping Integration Service* Configure the Worker Sub Type Integration Mapping and include a default value of "U"* Configure the Sequence Generator Analysis:
* Sequence Generator Configuration:Configuring the sequence generator is correct for the "#" (sequencer) in the filename, addressing part of the file name requirement.
* Worker Subtype Mapping:Including a default value of "U" for the worker subtype mapping aligns perfectly with the vendor's requirement for any unmapped value to be "U." This is a strong point.
* Date in Filename:This option doesn't mention configuring the date ("dd-mm-yy") in the filename, which is essential for the "CC_Job_Postings_dd-mm-yy_#.xml" format. Without this, the file name requirement isn't fully met.
* Integration Mapping Integration Service:Enabling the "Integration Mapping Integration Service" is vague. Workday doesn't use this exact term; instead, integration mappings are part of the integration setup, not a separate service. This phrasing suggests confusion or misalignment with Workday terminology.
* Conclusion:This option is partially correct (worker subtype mapping) but incomplete due to the missing date configuration for the filename and unclear terminology.
Option D:
* Enable the Sequence Generator Integration Service* Configure the Sequence Generator* Configure the Worker Sub Type Integration Mapping and include a default value of "U" Analysis:
* Sequence Generator Configuration:Enabling the "Sequence Generator Integration Service" and configuring the sequence generator addresses the "#" (sequencer) in the filename. While "Sequence Generator Integration Service" isn't a standard term, it likely refers to enabling and configuring the sequence generator functionality, which is correct. In Workday, this is done via the "Create ID Definition / Sequence Generator" task and linked in the File Utility.
* Worker Subtype Mapping:Configuring the worker subtype integration mapping with a default value of "U" meets the vendor's requirement for any unmapped value, ensuring "S," "R," "C," or "U" is output as specified in the table. This is accurate and aligns with Workday's integration mapping capabilities.
* Date in Filename:Although not explicitly mentioned in the steps, Workday's Core Connector: Job Postings template and File Utility allow configuring the filename pattern, including dynamic date values ("dd-mm-yy"). The filename "CC_Job_Postings_dd-mm-yy_#.xml" can be set in the File Utility' s "Filename" field with "Determine Value at Runtime," using date functions and the sequence generator. This is a standard practice and implied in the configuration, making this option complete.
* Conclusion:This option fully addresses both requirements: worker subtype mapping with "U" as the default and the file name format using the sequence generator and date. The terminology ("Sequence Generator Integration Service") is slightly non-standard but interpretable as enabling/configuring the sequence generator, which is correct in context.
Final Verification
To confirm, let's summarize the steps for Option D and ensure alignment with Workday Pro Integrations:
* Enable the Sequence Generator Integration Service:This likely means enabling and configuring the sequence generator via the "Create ID Definition / Sequence Generator" task, then linking it to the File Utility for the "#" in the filename.
* Configure the Sequence Generator:Set up the sequence generator to provide incremental numbers, ensuring each file has a unique "#" value.
* Configure the Worker Sub Type Integration Mapping with a default value of "U":Use the integration mapping to map Internal Seasonal (Fixed) to "S," Regular to "R," Contractor to "C," Consultant to "C," and set "U" as the default for any other value. This is done in the integration's mapping configuration.
* Filename Configuration (Implied):In the File Utility, set the filename to "CC_Job_Postings_dd-mm- yy_#.xml," where "dd-mm-yy" uses Workday's date functions (e.g., %d-%m-%y) and "#" links to the sequence generator.
This matches Workday's documentation and practices for the Core Connector: Job Postings template, ensuring both requirements are met.
Why Not the Other Options?
* Options A and B fail because they leave the default worker subtype value blank, not meeting the "U" requirement.
* Option C fails due to missing date configuration for the filename and unclear terminology ("Integration Mapping Integration Service").
* Option D is the only one that fully addresses both the worker subtype mapping (with "U" default) and implies the filename configuration, even if the date setup isn't explicitly listed (it's standard in Workday).
Supporting Documentation
The reasoning is based on Workday Pro Integrations best practices, including:
* Workday Tutorial: Activity Creating Unique Filenames from EIB-Out Integrations- Details on using sequence generators for filenames.
* Workday Tutorial: EIB Features- Explains integration mappings and default values.
* Get_Sequence_Generators Operation Details- Workday API documentation on sequence generators.
* Workday Advanced Studio Tutorial- Covers Core Connector templates and file name configurations.
* r/workday Reddit Post: How to Create a New Sequence Generator for Filename for EIB- Community insights on sequence generators.
NEW QUESTION # 20
Refer to the following XML to answer the question below.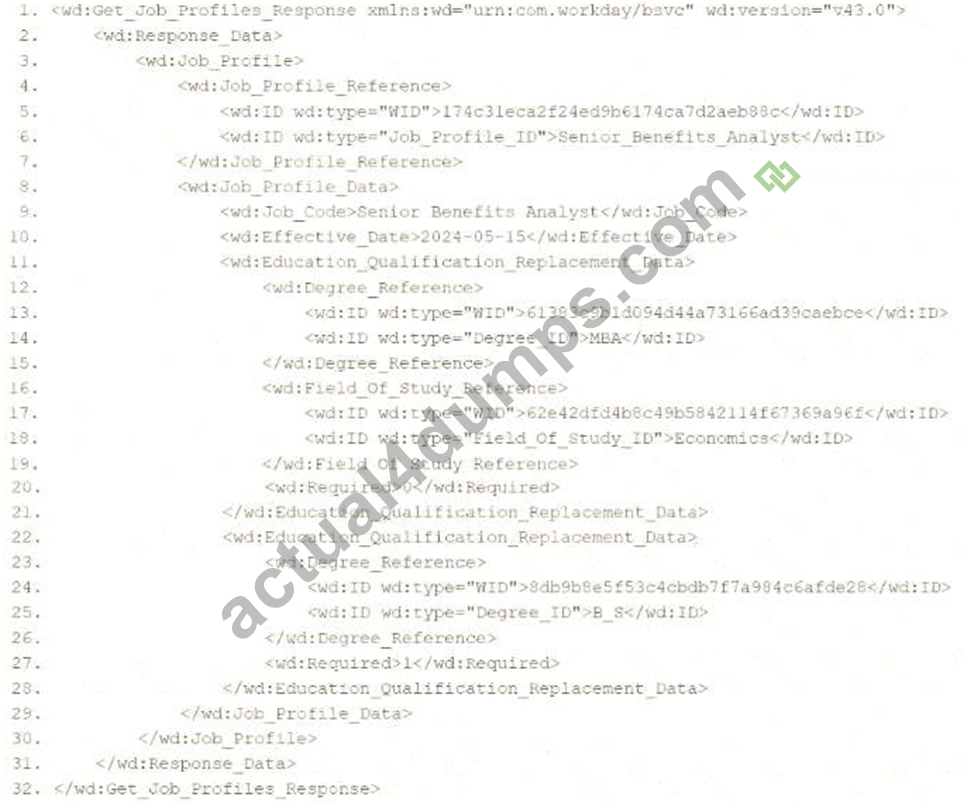
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the < wd:
Get_Job_Profiles_Response > element. This root template then applies a template against < wd:Job_Profile > .
What XPath syntax would be used to select the value of the wd:Job_Code element when the < xsl:value-of > element is placed within the template which matches on < wd:Job_Profile > ?
Answer: D
Explanation:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the < wd:Job_Code
> element. The root template of your XSLT matches on < wd:Get_Job_Profiles_Response > and applies a template to < wd:Job_Profile > . Within this template, you use the < xsl:value-of > element to extract the < wd:Job_Code > value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd= " urn:com.workday/bsvc " and version wd:version= " v43.0 " .
Key elements relevant to the question include:
* The root element is < wd:Get_Job_Profiles_Response > .
* It contains < wd:Response_Data > , which includes < wd:Job_Profile > elements.
* Within < wd:Job_Profile > , there are:
* < wd:Job_Profile_Reference > , which contains < wd:ID > elements (e.g., a Job_Profile_ID).
* < wd:Job_Profile_Data > , which contains < wd:Job_Code > with the value Senior_Benefits_Analyst.
The task is to select the value of < wd:Job_Code > (e.g., " Senior_Benefits_Analyst " ) using XPath within an XSLT template that matches < wd:Job_Profile > . The < xsl:value-of > element outputs the value of the selected node, so you need the correct XPath path from the < wd:Job_Profile > context to < wd:Job_Code > .
Analysis of Options
Let's evaluate each option based on the XML structure and XPath syntax rules:
* Option A: wd:Job_Profile/wd:Job_Profile_Data/wd:Job_Code
* This XPath starts from wd:Job_Profile and navigates to wd:Job_Profile_Data/wd:Job_Code.
However, in the XML, < wd:Job_Profile > is the parent element, and < wd:Job_Profile_Data > is a direct child containing < wd:Job_Code > . The path wd:Job_Profile/wd:Job_Profile_Data/wd:
Job_Code is technically correct in terms of structure, as it follows the hierarchy:
* < wd:Job_Profile > # < wd:Job_Profile_Data > # < wd:Job_Code > .
* However, since the template matches < wd:Job_Profile > , the context node is already < wd:
Job_Profile > . You don't need to include wd:Job_Profile/ at the beginning of the XPath unless navigating from a higher level. Starting directly with wd:Job_Profile_Data/wd:Job_Code (Option C) is more concise and appropriate for the context. This option is technically valid but redundant and less efficient, making it less preferred compared to Option C.
* Option B: wd:Job_Profile_Data[@wd:Job_Code]
* This XPath uses an attribute selector ([@wd:Job_Code]) to filter < wd:Job_Profile_Data > based on an attribute named wd:Job_Code. However, examining the XML, < wd:Job_Profile_Data > does not have a wd:Job_Code attribute-it has a child element < wd:Job_Code > with the value " Senior_Benefits_Analyst. " The [@attribute] syntax is used for attributes, not child elements, so this XPath is incorrect. It would not select the < wd:Job_Code > value and would likely return no results or an error. This option is invalid.
* Option C: wd:Job_Profile_Data/wd:Job_Code
* This XPath starts from wd:Job_Profile_Data (a direct child of < wd:Job_Profile > ) and navigates to wd:Job_Code. Since the template matches < wd:Job_Profile > , the context node is < wd:
Job_Profile > , and wd:Job_Profile_Data/wd:Job_Code correctly points to the < wd:Job_Code > element within < wd:Job_Profile_Data > . This path is:
* Concise and appropriate for the context.
* Directly selects the value " Senior_Benefits_Analyst " when used with < xsl:value-of > .
* Matches the XML structure, as < wd:Job_Profile_Data > contains < wd:Job_Code > as a child.
* This is the most straightforward and correct option for selecting the < wd:Job_Code > value within the < wd:Job_Profile > template.
* Option D: wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ]
* This XPath navigates to < wd:Job_Profile_Reference > (a child of < wd:Job_Profile > ) and then to < wd:ID > with an attribute wd:type= " Job_Profile_ID " . In the XML, < wd:
Job_Profile_Reference > contains:
* < wd:ID wd:type= " WID " > 1740d3eca2f2ed9b6174ca7d2ae88c8c < /wd:ID >
* < wd:ID wd:type= " Job_Profile_ID " > Senior_Benefits_Analyst < /wd:ID >
* The XPath wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ] selects the < wd:ID
> element with wd:type= " Job_Profile_ID " , which has the value " Senior_Benefits_Analyst. " However, this is not the < wd:Job_Code > value-the < wd:Job_Code > is a separate element under < wd:Job_Profile_Data > , not < wd:Job_Profile_Reference > . The question specifically asks for the < wd:Job_Code > value, so this option is incorrect, as it selects a different piece of data (the job profile ID, not the job code).
Why Option C is Correct
Option C, wd:Job_Profile_Data/wd:Job_Code, is the correct XPath syntax because:
* It starts from the context node < wd:Job_Profile > (as the template matches this element) and navigates to < wd:Job_Profile_Data/wd:Job_Code > , which directly selects the < wd:Job_Code > element's value ( " Senior_Benefits_Analyst " ).
* It is concise and aligns with standard XPath navigation in XSLT, avoiding unnecessary redundancy (unlike Option A) or incorrect attribute selectors (unlike Option B).
* It matches the XML structure, where < wd:Job_Profile_Data > is a child of < wd:Job_Profile > and contains < wd:Job_Code > as a child.
* When used with < xsl:value-of select= " wd:Job_Profile_Data/wd:Job_Code " / > in the template, it outputs the job code value, fulfilling the requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
xml
WrapCopy
< xsl:template match= " wd:Job_Profile " >
< xsl:value-of select= " wd:Job_Profile_Data/wd:Job_Code " / >
< /xsl:template >
This would output " Senior_Benefits_Analyst " for the < wd:Job_Code > element in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows < wd:Job_Profile_Data > as the container for job profile details, including < wd:
Job_Code > . The guide emphasizes using relative XPath paths within templates to navigate from the matched element (e.g., < wd:Job_Profile > ) to child elements like < wd:Job_Profile_Data/wd:Job_Code > .
Workday Pro Integrations Study Guide References
* Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath.
* Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including < wd:Job_Profile_Data > and < wd:Job_Code > .
* Section: XPath Syntax - Explains how to navigate XML hierarchies in Workday XSLT, using relative paths like wd:Job_Profile_Data/wd:Job_Code from a < wd:Job_Profile > context.
* Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses.
Option C is the verified answer, as it correctly selects the < wd:Job_Code > value using the appropriate XPath syntax within the < wd:Job_Profile > template context.
NEW QUESTION # 21
Refer to the following XML to answer the question below.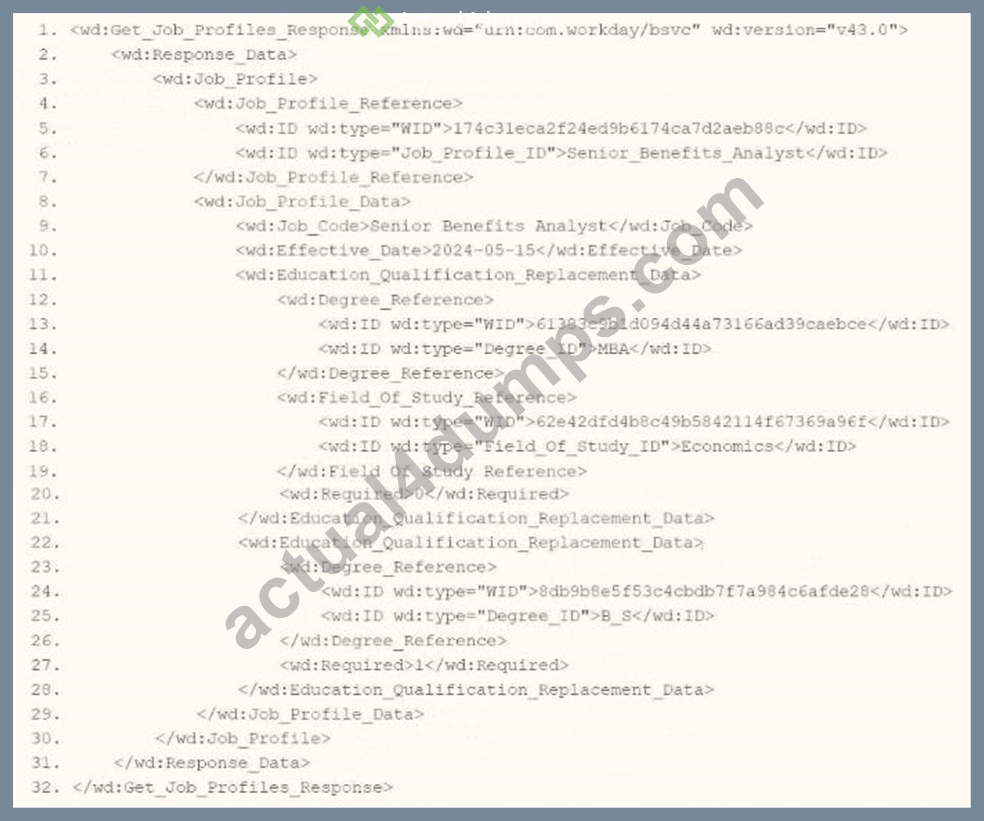
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the <wd:Get_Job_Profiles_Response> element. This root template then applies templates against <wd:Job_Profile>. What XPath syntax would be used to select the value of the ID element which has a wd:type attribute named Job_Profile_ID when the <xsl:value-of> element is placed within the template which matches on <wd:Job_Profile>?
Answer: B
Explanation:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the <wd:ID> element where the wd:type attribute equals "Job_Profile_ID." The root template of your XSLT matches on <wd:Get_Job_Profiles_Response> and applies templates to <wd:Job_Profile>. Within this template, you use the <xsl:value-of> element to extract the value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd="urn:com.workday/bsvc" and version wd:version="v43.0". Key elements relevant to the question include:
The root element is <wd:Get_Job_Profiles_Response>.
It contains <wd:Response_Data>, which includes <wd:Job_Profile> elements.
Within <wd:Job_Profile>, there is <wd:Job_Profile_Reference>, which contains multiple <wd:ID> elements, each with a wd:type attribute:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The task is to select the value of the <wd:ID> element where wd:type="Job_Profile_ID" (e.g., "Senior_Benefits_Analyst") using XPath within an XSLT template that matches <wd:Job_Profile>. The <xsl:value-of> element outputs the value of the selected node, so you need the correct XPath path from the <wd:Job_Profile> context to the specific <wd:ID> element with the wd:type attribute value "Job_Profile_ID." Analysis of Options Let's evaluate each option based on the XML structure and XPath syntax rules:
Option A: wd:Job_Profile_Reference/wd:ID/wd:type='Job_Profile_ID'
This XPath attempts to navigate from wd:Job_Profile_Reference to wd:ID, then to wd:type='Job_Profile_ID'. However, there are several issues:
wd:type='Job_Profile_ID' is not valid XPath syntax. In XPath, to filter based on an attribute value, you use the attribute selector [@attribute='value'], not a direct comparison like wd:type='Job_Profile_ID'.
wd:type is an attribute of <wd:ID>, not a child element or node. This syntax would not select the <wd:ID> element itself but would be interpreted as trying to match a nonexistent child node or property, resulting in an error or no match.
This option is incorrect because it misuses XPath syntax for attribute filtering.
Option B: wd:Job_Profile_Reference/wd:ID/@wd:type='Job_Profile_ID'
This XPath navigates to wd:Job_Profile_Reference/wd:ID and then selects the @wd:type attribute, comparing it to "Job_Profile_ID" with =@wd:type='Job_Profile_ID'. However:
The =@wd:type='Job_Profile_ID' syntax is invalid in XPath. To filter based on an attribute value, you use [@wd:type='Job_Profile_ID'] as a predicate, not an equality comparison in this form.
This XPath would select the wd:type attribute itself (e.g., the string "Job_Profile_ID"), not the value of the <wd:ID> element. Since <xsl:value-of> expects a node or element value, selecting an attribute directly would not yield the desired "Senior_Benefits_Analyst" value.
This option is incorrect due to the invalid syntax and inappropriate selection of the attribute instead of the element value.
Option C: wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']
This XPath navigates from wd:Job_Profile_Reference to wd:ID and uses the predicate [@wd:type='Job_Profile_ID'] to filter for <wd:ID> elements where the wd:type attribute equals "Job_Profile_ID." In the XML, <wd:Job_Profile_Reference> contains:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The predicate [@wd:type='Job_Profile_ID'] selects the second <wd:ID> element, whose value is "Senior_Benefits_Analyst." Since the template matches <wd:Job_Profile>, and <wd:Job_Profile_Reference> is a direct child of <wd:Job_Profile>, this path is correct:
<wd:Job_Profile> → <wd:Job_Profile_Reference> → <wd:ID[@wd:type='Job_Profile_ID']>.
When used with <xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>, it outputs "Senior_Benefits_Analyst," fulfilling the requirement.
This option is correct because it uses proper XPath syntax for attribute-based filtering and selects the desired <wd:ID> value.
Option D: wd:Job_Profile_Reference/wd:ID/[@wd:type='Job_Profile_ID']
This XPath is similar to Option C but includes an extra forward slash before the predicate: wd:ID/[@wd:type='Job_Profile_ID']. In XPath, predicates like [@attribute='value'] are used directly after the node name (e.g., wd:ID[@wd:type='Job_Profile_ID']), not separated by a slash. The extra slash is syntactically incorrect and would result in an error or no match, as it implies navigating to a child node that doesn't exist.
This option is incorrect due to the invalid syntax.
Why Option C is Correct
Option C, wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID'], is the correct XPath syntax because:
It starts from the context node <wd:Job_Profile> (as the template matches this element) and navigates to <wd:Job_Profile_Reference/wd:ID>, using the predicate [@wd:type='Job_Profile_ID'] to filter for the <wd:ID> element with wd:type="Job_Profile_ID".
It correctly selects the value "Senior_Benefits_Analyst," which is the content of the <wd:ID> element where wd:type="Job_Profile_ID".
It uses standard XPath syntax for attribute-based filtering, aligning with Workday's XSLT implementation for web service responses.
When used with <xsl:value-of>, it outputs the required value, fulfilling the question's requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
<xsl:template match="wd:Job_Profile">
<xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>
</xsl:template>
This would output "Senior_Benefits_Analyst" for the <wd:ID> element with wd:type="Job_Profile_ID" in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows <wd:Job_Profile_Reference> containing <wd:ID> elements with wd:type attributes, and the guide emphasizes using predicates like [@wd:type='value'] to filter based on attributes. This is a standard practice for navigating Workday web service responses.
Workday Pro Integrations Study Guide Reference
Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath and attribute predicates.
Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including <wd:Job_Profile_Reference> and <wd:ID> with wd:type attributes.
Section: XPath Syntax - Explains how to use predicates like [@wd:type='Job_Profile_ID'] for attribute-based filtering in Workday XSLT.
Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses, including attribute selection.
Option C is the verified answer, as it correctly selects the <wd:ID> value with wd:type="Job_Profile_ID" using the appropriate XPath syntax within the <wd:Job_Profile> template context.
NEW QUESTION # 22
Refer to the following scenario to answer the question below.
You need to configure a Core Connector: Candidate Outbound integration for your vendor. The connector requires the data initialization service (DIS).
The vendor needs the file to only include candidates that undergo a candidate assessment event in Workday.
How do you accomplish this?
Answer: D
Explanation:
The scenario requires configuring a Core Connector: Candidate Outbound integration with the Data Initialization Service (DIS) to include only candidates who have undergone a candidate assessment event in Workday. Core Connectors are event-driven integrations that rely on business process transactions or specific data changes to trigger data extraction. Let's analyze how to meet this requirement:
Understanding Core Connector and DIS:The Core Connector: Candidate Outbound integration extracts candidate data based on predefined services and events. The Data Initialization Service (DIS) ensures the initial dataset is populated, but ongoing updates depend on configured integration services that define which candidates to include based on specific events or conditions.
Candidate Assessment Event:In Workday, a "candidate assessment event" typically refers to a step in the recruiting business process where a candidate completes an assessment. The requirement to filter for candidates with this event suggests limiting the dataset to those who triggered an assessment-related transaction.
Integration Services:In Core Connectors, integration services determine the scope of data extracted by subscribing to specific business events or conditions. For this scenario, you can configure the integration services to monitor the "Candidate Assessment" event (or a related business process step) and include only candidates who have completed it. This is done by selecting or customizing the appropriate service within the Core Connector configuration to filter the candidate population.
Option Analysis:
A . Configure the integration services to only include candidates with assessments: Correct. This involves adjusting the integration services in the Core Connector to filter candidates based on the assessment event, ensuring only relevant candidates are included in the output file.
B . Set the integration transaction log to subscribe to specific transaction types: Incorrect. The integration transaction log tracks processed transactions for auditing but doesn't control which candidates are included in the output. Subscription to events is handled via integration services, not the log.
C . Make the Candidate Assessment field required in integration field attributes: Incorrect. Integration field attributes define field-level properties (e.g., formatting or mapping), not the population of candidates included. Making a field "required" doesn't filter the dataset.
D . Create an integration map to output values for candidates with assessments: Incorrect. Integration maps transform or map field values (e.g., converting "United States" to "USA") but don't filter the population of candidates included in the extract. Filtering is a service-level configuration.
Implementation:
Edit the Core Connector: Candidate Outbound integration.
In the Integration Services section, select or configure a service tied to the "Candidate Assessment" event (e.g., a business process completion event).
Ensure the service filters the candidate population to those with an assessment event recorded.
Test the integration to verify only candidates with assessments are extracted.
Reference from Workday Pro Integrations Study Guide:
Core Connectors & Document Transformation: Section on "Configuring Integration Services" explains how services define the data scope based on events or conditions.
Integration System Fundamentals
NEW QUESTION # 23
......
As we all know, the latest Workday-Pro-Integrations quiz prep has been widely spread since we entered into a new computer era. The cruelty of the competition reflects that those who are ambitious to keep a foothold in the job market desire to get the Workday-Pro-Integrations certification. It’s worth mentioning that our working staff considered as the world-class workforce, have been persisting in researching Workday-Pro-Integrations test prep for many years. Our Workday-Pro-Integrations Exam Guide engage our working staff in understanding customers’ diverse and evolving expectations and incorporate that understanding into our strategies. Our latest Workday-Pro-Integrations quiz prep aim at assisting you to pass the Workday-Pro-Integrations exam and making you ahead of others. Under the support of our study materials, passing the exam won’t be an unreachable mission.
Workday-Pro-Integrations Valid Study Notes: https://www.actual4dumps.com/Workday-Pro-Integrations-study-material.html
BONUS!!! Download part of Actual4Dumps Workday-Pro-Integrations dumps for free: https://drive.google.com/open?id=1B7Z2DYyFL9O53jdnPOqy-OiETgVtoFcT