By doing this you can stay competitive and updated in the market. There are other several Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam benefits that you can gain after passing the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam. Are you ready to add the Databricks-Certified-Data-Engineer-Professional certification to your resume? Looking for the proven, easiest and quick way to pass the Databricks-Certified-Data-Engineer-Professional Exam? If you are then you do not need to go anywhere. Just download the Databricks-Certified-Data-Engineer-Professional Questions and start Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam preparation today.
| Section | Objectives |
|---|---|
| Topic 1: Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold) - Workspace and cluster architecture - Data governance concepts (Unity Catalog basics) |
| Topic 2: Data Ingestion and Processing | - ETL pipeline design patterns - Structured Streaming fundamentals - Batch and streaming ingestion with Auto Loader |
| Topic 3: Delta Lake and Data Management | - Time travel and versioning - Schema evolution and enforcement - Delta Lake transactions and ACID properties |
| Topic 4: Production Pipelines and Orchestration | - Error handling and recovery strategies - Databricks Workflows - Job scheduling and monitoring |
| Topic 5: Data Modeling and Transformation | - Performance optimization techniques - Spark SQL transformations - Dimensional modeling concepts |
>> Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions Answers <<
When they will be giving their final examination to get Databricks Databricks-Certified-Data-Engineer-Professional certification they don't struggle much and do it easily. The results of the customizable Databricks-Certified-Data-Engineer-Professional exam dumps can then be used to identify areas of strength and weakness and to create a personalized study plan that focuses on improving in the areas that need the most work. Taking Databricks-Certified-Data-Engineer-Professional Practice Tests regularly could help individuals build their confidence, reduce test anxiety, and improve their overall performance.
NEW QUESTION # 83
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table: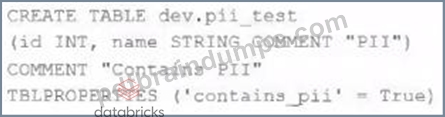
Which command allows manual confirmation that these three requirements have been met?
Answer: D
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 84
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: A
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
NEW QUESTION # 85
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from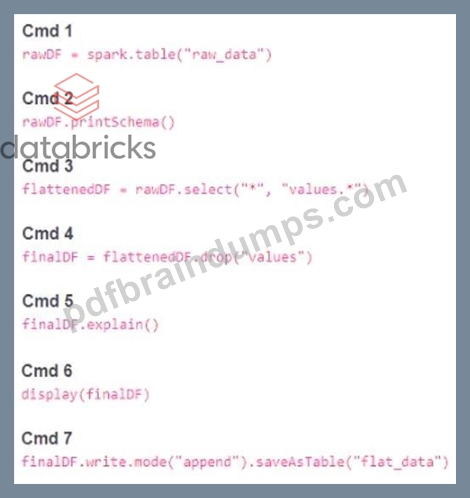
Which command should be removed from the notebook before scheduling it as a job?
Answer: B
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 86
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: B
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 87
A Data engineer wants to run unit's tests using common Python testing frameworks on python functions defined across several Databricks notebooks currently used in production. How can the data engineer run unit tests against function that work with data in production?
Answer: D
Explanation:
The best practice for running unit tests on functions that interact with data is to use a dataset that closely mirrors the production data. This approach allows data engineers to validate the logic of their functions without the risk of affecting the actual production data. It's important to have a representative sample of production data to catch edge cases and ensure the functions will work correctly when used in a production environment.
NEW QUESTION # 88
......
We have applied the latest technologies to the design of our Databricks Databricks-Certified-Data-Engineer-Professional exam prep not only on the content but also on the displays. As a consequence you are able to keep pace with the changeable world and remain your advantages with our Databricks Databricks-Certified-Data-Engineer-Professional training braindumps. Besides, you can consolidate important knowledge for you personally and design customized study schedule or to-do list on a daily basis.
Latest Databricks-Certified-Data-Engineer-Professional Exam Test: https://www.pdfbraindumps.com/Databricks-Certified-Data-Engineer-Professional_valid-braindumps.html