P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by UpdateDumps: https://drive.google.com/open?id=1B0McH9Mh2BI2yPoOMYWnunRIOxb3z4vU
Keeping in view different preparation styles of Amazon Data-Engineer-Associate test applicant UpdateDumps has designed three easy-to-use formats for its product. Each format has a pool of AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) actual questions which have been compiled under the guidance of thousands of professionals worldwide. Questions in this product will appear in the Amazon Data-Engineer-Associate final test.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Implement data quality and validation - Ingest data from various sources
|
| Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Data Operations and Support | 22% | - Automate operational tasks - Monitor and troubleshoot data pipelines
- Backup, restore, and disaster recovery |
| Data Security and Governance | 18% | - Protect sensitive data - Implement access control and authentication
|
>> Data-Engineer-Associate Valid Exam Book <<
We believe that one of the most important things you care about is the quality of our Data-Engineer-Associate exam materials, but we can ensure that the quality of it won’t let you down. Many candidates are interested in our Data-Engineer-Associate exam materials. What you can set your mind at rest is that the Data-Engineer-Associate exam materials are very high quality. Data-Engineer-Associate exam materials draw up team have a strong expert team to constantly provide you with an effective training resource. They continue to use their rich experience and knowledge to study the real exam questions of the past few years, to draw up such an exam materials for you. In other words, you can never worry about the quality of Data-Engineer-Associate Exam Materials, you will not be disappointed.
NEW QUESTION # 13
A company implements a data mesh that has a central governance account. The company needs to catalog all data in the governance account. The governance account uses AWS Lake Formation to centrally share data and grant access permissions.
The company has created a new data product that includes a group of Amazon Redshift Serverless tables. A data engineer needs to share the data product with a marketing team. The marketing team must have access to only a subset of columns. The data engineer needs to share the same data product with a compliance team. The compliance team must have access to a different subset of columns than the marketing team needs access to.
Which combination of steps should the data engineer take to meet these requirements? (Select TWO.)
Answer: C,D
Explanation:
The company is using a data mesh architecture with AWS Lake Formation for governance and needs to share specific subsets of data with different teams (marketing and compliance) using Amazon Redshift Serverless.
Option A: Create views of the tables that need to be shared. Include only the required columns.
Creating views in Amazon Redshift that include only the necessary columns allows for fine-grained access control. This method ensures that each team has access to only the data they are authorized to view.
Option E: Share the Amazon Redshift data share to the Amazon Redshift Serverless workgroup in the marketing team's account.
Amazon Redshift data sharing enables live access to data across Redshift clusters or Serverless workgroups. By sharing data with specific workgroups, you can ensure that the marketing team and compliance team each access the relevant subset of data based on the views created.
Option B (creating a Redshift data share) is close but does not address the fine-grained column-level access.
Option C (creating a managed VPC endpoint) is unnecessary for sharing data with specific teams.
Option D (sharing with the Lake Formation catalog) is incorrect because Redshift data shares do not integrate directly with Lake Formation catalogs; they are specific to Redshift workgroups.
Reference:
Amazon Redshift Data Sharing
AWS Lake Formation Documentation
NEW QUESTION # 14
A company uses Amazon Redshift for its data warehouse. The company must automate refresh schedules for Amazon Redshift materialized views.
Which solution will meet this requirement with the LEAST effort?
Answer: D
Explanation:
The query editor v2 in Amazon Redshift is a web-based tool that allows users to run SQL queries and scripts on Amazon Redshift clusters. The query editor v2 supports creating and managing materialized views, which are precomputed results of a query that can improve the performance of subsequent queries. The query editor v2 also supports scheduling queries to run at specified intervals, which can be used to refresh materialized views automatically. This solution requires the least effort, as it does not involve any additional services, coding, or configuration. The other solutions are more complex and require more operational overhead.
Apache Airflow is an open-source platform for orchestrating workflows, which can be used to refresh materialized views, but it requires setting up and managing an Airflow environment, creating DAGs (directed acyclic graphs) to define the workflows, and integrating with Amazon Redshift. AWS Lambda is a serverless compute service that can run code in response to events, which can be used to refresh materialized views, but it requires creating and deploying Lambda functions, defining UDFs within Amazon Redshift, and triggering the functions using events or schedules. AWS Glue is a fully managed ETL service that can run jobs to transform and load data, which can be used to refresh materialized views, but it requires creating and configuring Glue jobs, defining Glue workflows to orchestrate the jobs, and scheduling the workflows using triggers. References:
* Query editor V2
* Working with materialized views
* Scheduling queries
* [AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]
NEW QUESTION # 15
A data engineer must orchestrate a series of Amazon Athena queries that will run every day. Each query can run for more than 15 minutes.
Which combination of steps will meet these requirements MOST cost-effectively? (Choose two.)
Answer: B,C
Explanation:
Option A and B are the correct answers because they meet the requirements most cost-effectively. Using an AWS Lambda function and the Athena Boto3 client start_query_execution API call to invoke the Athena queries programmatically is a simple and scalable way to orchestrate the queries. Creating an AWS Step Functions workflow and adding two states to check the query status and invoke the next query is a reliable and efficient way to handle the long-running queries.
Option C is incorrect because using an AWS Glue Python shell job to invoke the Athena queries programmatically is more expensive than using a Lambda function, as it requires provisioning and running a Glue job for each query.
Option D is incorrect because using an AWS Glue Python shell script to run a sleep timer that checks every 5 minutes to determine whether the current Athena query has finished running successfully is not a cost- effective or reliable way to orchestrate the queries, as it wastes resources and time.
Option E is incorrect because using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) to orchestrate the Athena queries in AWS Batch is an overkill solution that introduces unnecessary complexity and cost, as it requires setting up and managing an Airflow environment and an AWS Batch compute environment.
References:
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Orchestration, Section 5.2: AWS Lambda, Section 5.3: AWS Step Functions, Pages 125-135
* Building Batch Data Analytics Solutions on AWS, Module 5: Data Orchestration, Lesson 5.1: AWS Lambda, Lesson 5.2: AWS Step Functions, Pages 1-15
* AWS Documentation Overview, AWS Lambda Developer Guide, Working with AWS Lambda Functions, Configuring Function Triggers, Using AWS Lambda with Amazon Athena, Pages 1-4
* AWS Documentation Overview, AWS Step Functions Developer Guide, Getting Started, Tutorial:
Create a Hello World Workflow, Pages 1-8
NEW QUESTION # 16
A company stores data from an application in an Amazon DynamoDB table that operates in provisioned capacity mode. The workloads of the application have predictable throughput load on a regular schedule.
Every Monday, there is an immediate increase in activity early in the morning. The application has very low usage during weekends.
The company must ensure that the application performs consistently during peak usage times.
Which solution will meet these requirements in the MOST cost-effective way?
Answer: A
Explanation:
Amazon DynamoDB is a fully managed NoSQL database service that provides fast and predictable performance with seamless scalability. DynamoDB offers two capacity modes for throughput capacity:
provisioned and on-demand. In provisioned capacity mode, you specify the number of read and write capacity units per second that you expect your application to require. DynamoDB reserves the resources to meet your throughput needs with consistent performance. In on-demand capacity mode, you pay per request and DynamoDB scales the resources up and down automatically based on the actual workload. On-demand capacity mode is suitable for unpredictable workloads that can vary significantly over time1.
The solution that meets the requirements in the most cost-effective way is to use AWS Application Auto Scaling to schedule higher provisioned capacity for peak usage times and lower capacity during off-peak times. This solution has the following advantages:
* It allows you to optimize the cost and performance of your DynamoDB table by adjusting the provisioned capacity according to your predictable workload patterns. You can use scheduled scaling to specify the date and time for the scaling actions, and the new minimum and maximum capacity limits. For example, you can schedule higher capacity for every Monday morning and lower capacity for weekends2.
* It enables you to take advantage of the lower cost per unit of provisioned capacity mode compared to on-demand capacity mode. Provisioned capacity mode charges a flat hourly rate for the capacity you reserve, regardless of how much you use. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on-demand capacity mode1.
* It ensures that your application performs consistently during peak usage times by having enough capacity to handle the increased load. You can also use auto scaling to automatically adjust the provisioned capacity based on the actual utilization of your table, and set a target utilization percentage for your table or global secondary index. This way, you can avoid under-provisioning or over- provisioning your table2.
Option A is incorrect because it suggests increasing the provisioned capacity to the maximum capacity that is currently present during peak load times. This solution has the following disadvantages:
* It wastes money by paying for unused capacity during off-peak times. If you provision the same high capacity for all times, regardless of the actual workload, you are over-provisioning your table and paying for resources that you don't need1.
* It does not account for possible changes in the workload patterns over time. If your peak load times increase or decrease in the future, you may need to manually adjust the provisioned capacity to match the new demand. This adds operational overhead and complexity to your application2.
Option B is incorrect because it suggests dividing the table into two tables and provisioning each table with half of the provisioned capacity of the original table. This solution has the following disadvantages:
* It complicates the data model and the application logic by splitting the data into two separate tables.
You need to ensure that the queries are evenly distributed across both tables, and that the data is consistent and synchronized between them. This adds extra development and maintenance effort to your application3.
* It does not solve the problem of adjusting the provisioned capacity according to the workload patterns.
You still need to manually or automatically scale the capacity of each table based on the actual utilization and demand. This may result in under-provisioning or over-provisioning your tables2.
Option D is incorrect because it suggests changing the capacity mode from provisioned to on-demand. This solution has the following disadvantages:
* It may incur higher costs than provisioned capacity mode for predictable workloads. On-demand capacity mode charges for each read and write request you consume, with no minimum capacity required. For predictable workloads, provisioned capacity mode can be more cost-effective than on- demand capacity mode, as you can reserve the capacity you need at a lower rate1.
* It may not provide consistent performance during peak usage times, as on-demand capacity mode may take some time to scale up the resources to meet the sudden increase in demand. On-demand capacity mode uses adaptive capacity to handle bursts of traffic, but it may not be able to handle very large spikes or sustained high throughput. In such cases, you may experience throttling or increased latency.
References:
* 1: Choosing the right DynamoDB capacity mode - Amazon DynamoDB
* 2: Managing throughput capacity automatically with DynamoDB auto scaling - Amazon DynamoDB
* 3: Best practices for designing and using partition keys effectively - Amazon DynamoDB
* [4]: On-demand mode guidelines - Amazon DynamoDB
* [5]: How to optimize Amazon DynamoDB costs - AWS Database Blog
* [6]: DynamoDB adaptive capacity: How it works and how it helps - AWS Database Blog
* [7]: Amazon DynamoDB pricing - Amazon Web Services (AWS)
NEW QUESTION # 17
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: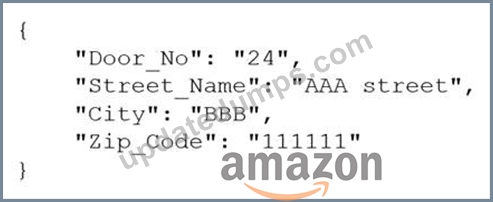
Which solution will meet this requirement with the LEAST coding effort?
Answer: B
Explanation:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns) NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
NEW QUESTION # 18
......
The easy to learn format of these amazing Data-Engineer-Associate exam questions will prove one of the most exciting exam preparation experiences of your life! When you are visiting on our website, you can find that every button is easy to use and has a swift response. And there are three varied versions of our Data-Engineer-Associate learning guide: the PDF, Software and APP online. Every version of our Data-Engineer-Associate simulating exam is auto installed if you buy and study with them. They are perfect in every detail.
Reliable Data-Engineer-Associate Practice Questions: https://www.updatedumps.com/Amazon/Data-Engineer-Associate-updated-exam-dumps.html
DOWNLOAD the newest UpdateDumps Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1B0McH9Mh2BI2yPoOMYWnunRIOxb3z4vU