Now is the ideal time to prepare for and crack the DP-800 exam. To do this, you just need to enroll in the DP-800 examination and start preparation with top-notch and updated Microsoft DP-800 actual exam dumps. All three formats of Developing AI-Enabled Database Solutions DP-800 Practice Test are available with up to three months of free Developing AI-Enabled Database Solutions exam questions updates, free demos, and a satisfaction guarantee. Just pay an affordable price and get DP-800 updated exam dumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and develop database solutions | 35-40% | - Develop database solutions
|
| Topic 2: Secure, optimize, and deploy database solutions | 35-40% | - Secure database solutions
|
| Topic 3: Implement AI capabilities in database solutions | 25-30% | - Integrate AI models and services
|
>> Valid Braindumps Microsoft DP-800 Pdf <<
The Microsoft DP-800 certification differentiates you from other professionals in the market. Success in the Microsoft DP-800 exam shows that you have demonstrated dedication to understanding and advancing in your profession. Cracking the Microsoft DP-800 test gives you an edge which is particularly essential in today’s challenging market of information technology. If you are planning to get through the test, you must study from reliable sources for Developing AI-Enabled Database Solutions DP-800 Exam Preparation. Prep4cram real Microsoft DP-800 exam dumps are enough to clear the DP-800 certification test easily on the first attempt. This is because Prep4cram Microsoft DP-800 PDF Questions and practice test is designed after a lot of research and hard work carried out by experts.
NEW QUESTION # 69
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: A
Explanation:
A). Chunking is the correct answer.
Chunking divides large documents into smaller, semantically meaningful sections that can be independently embedded, indexed, and retrieved in a Retrieval Augmented Generation (RAG) architecture.
The ProcedureDocuments table contains a Content NVARCHAR(MAX) column and an Embedding VECTOR (1536) column. Storing entire documents as individual embedding units can introduce irrelevant contextual information and increase token consumption.
Technical breakdown:
* Document segmentation: Split lengthy medical procedure documents into smaller chunks while preserving their semantic meaning.
* Independent embeddings: Generate a separate vector embedding for each chunk to support more granular semantic similarity searches.
* Improved retrieval relevance: Retrieve only document sections relevant to the user ' s query instead of entire documents.
* Reduced token consumption: Send fewer irrelevant tokens to the LLM, reducing context-processing costs.
* Performance optimization: Smaller retrieved contexts can reduce downstream processing latency.
Appropriate vector indexing and chunk sizing are also necessary for efficient retrieval.
Microsoft ' s RAG guidance specifically confirms that smaller chunks help return relevant content while reducing token usage.
Why the other options are incorrect:
* B. Embeddings: Enable semantic similarity searches but do not independently reduce retrieved text size.
* C. Small language model (SLM): May reduce inference costs but does not directly optimize document retrieval.
* D. JSON content: Provides structured data representation without inherently improving retrieval performance or reducing tokens.
DP-800 Official Study Guide Reference:
Main topic: Implement AI capabilities in database solutions.
Subtopics: Design and implement models and embeddings and Design and implement intelligent search.
Specific examination objectives: Design and implement chunks for embeddings and evaluate performance of vector and hybrid search.
Official reference: Microsoft Learn - RAG Chunking Phase .
NEW QUESTION # 70
You need to design a generative Al solution that uses a Microsoft SOL Server 2025 database named DB1 as a data source. The solution must generate responses that meet the following requirements:
* Ait ' grounded In the latest transactional and reference data stored in D61
* Do NOT require retraining or fine-tuning the language model when the data changes
* Can include citations or references to the source data used in the response Which scenario is the best use case for implementing a Retrieval Augmented Generation (RAG) pattern?
More than one answer choice may achieve the goal. Select the BEST answer
Answer: A
Explanation:
The best use case for RAG is answering user questions based on company-specific knowledge . Microsoft defines RAG as a pattern that augments a language model with a retrieval system that provides grounding data at inference time, which is exactly what you need when responses must be based on the latest transactional and reference data , must avoid retraining/fine-tuning , and should be able to include citations or references to source data.
The other options do not fit as well:
* summarizing free-form user input does not inherently require retrieval from DB1,
* training a custom model contradicts the requirement to avoid retraining/fine-tuning,
* generating marketing slogans is a creative generation task, not a grounding-and-citation scenario. RAG is specifically strong when answers must come from your organization's own changing knowledge.
NEW QUESTION # 71
You have a SQL database in Microsoft Fabric named Sales BD that contains a table named dbo.Products. You need to modify SalesBD to meet the following requirements:
* Create a vector index on the appropriate column.
* Use a supplied natural language query vector.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The first correct selection is embedding because a vector index must be created on the vector column , not on a scalar distance column or a text column such as product_name. Microsoft's CREATE VECTOR INDEX documentation shows that the index is created directly on the vector-valued column, for example ON product_embeddings(embedding).
The second correct selection is VECTOR_SEARCH because the requirement is to use a supplied natural language query vector and search against the indexed embeddings. Microsoft documents that VECTOR_SEARCH is the Transact-SQL function for approximate nearest neighbor vector retrieval and that it applies to SQL database in Microsoft Fabric as well as other supported SQL platforms.
This also matches the shown code pattern:
* declare a vector variable such as @query_vector VECTOR(1536),
* create a vector index on dbo.Products(embedding),
* query with VECTOR_SEARCH(... SIMILAR_TO = @query_vector, METRIC = ' cosine ' , TOP_N =
10).
NEW QUESTION # 72
Drag and Drop Question
You have an Azure SQL database named SalesDB that supports an ecommerce application.
SalesDB contains a table named dbo.Orders that has a clustered index on a column named OrderId.
dbo.Orders receives continuous OLTP inserts and updates during business hours.
Your analytics team runs hourly aggregate queries that scan dbo.Orders to calculate revenue trends for recent dates.
You need to improve the performance of the hourly analytics queries without significantly affecting OLTP throughput. The solution must meet the following requirements:
- Support near-real-time (NRT) analytics on the dbo.Orders table.
- Reduce read time when retrieving analytical data from dbo.Orders.
- Support indexing only rows that match a predicate, such as Active =
1.
Which type of index should you use for each requirement? To answer, drag the appropriate index types to the correct requirements. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: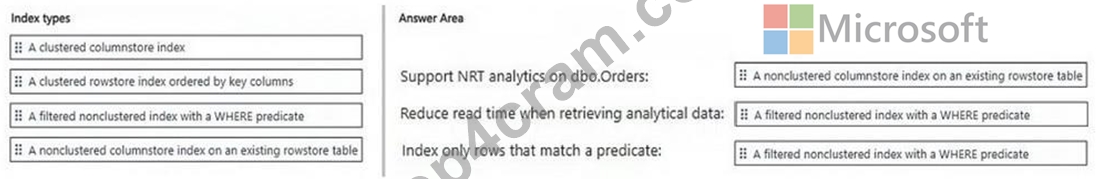
NEW QUESTION # 73
Vou have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL tern named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* The members of SqlUsers can modify the data in SalesDB via SalesApi. # No
* The members of SqlUsers can view the data in SalesDB via SalesApi. # No
* The members of SqlUsers can change the field mappings of SalesApi. # Yes For both viewing and modifying data through SalesApi, the key missing permission is Run Queries and Mutations . Microsoft's Fabric GraphQL documentation states that callers need Execute permissions for the GraphQL API , which correspond to the Run Queries and Mutations option, and with SSO connectivity they also need appropriate permissions on the underlying data source. In the exhibit, SqlUsers has View and Edit GraphQL item selected, but Run Queries and Mutations is not selected, so members cannot query or mutate data through the API.
The third statement is Yes because the group was explicitly granted View and Edit GraphQL item . That permission is the one that allows users to open and modify the GraphQL item itself, including schema-related configuration such as field mappings in the API item. The workspace Viewer role does not by itself grant query execution through the API, but the direct GraphQL item permission shown does allow editing the item.
NEW QUESTION # 74
......
To make your review more comfortable and effective, we made three versions of DP-800 study guide as well as a series of favorable benefits for you. We are concerted company offering tailored services which include not only the newest and various versions of DP-800 Practice Engine, but offer one-year free updates services with patient staff offering help 24/7. It means that as long as our professionals update the DP-800 learning quiz, you will receive it for free.
DP-800 Updated CBT: https://www.prep4cram.com/DP-800_exam-questions.html