Certified-Data-Engineer-Professional Braindumps Pdf | Valid Certified-Data-Engineer-Professional Exam Test

Our most wanted version of the DatabricksExam Questions is our PDF eBook, and it is convenient even students can easily use it. Databricks Certified-Data-Engineer-Professional pdf questions are printable and portable features make it more convenient the use. You can prepare with Certified-Data-Engineer-Professional pdf questions and answers anywhere and anytime. This is the most reliable source of preparation. Our Databricks Certified-Data-Engineer-Professional desktop-based practice software is the most helpful version to prepare for Databricks Certified Data Engineer Professional exam as it simulates the real DatabricksCertified Network Professional Data Center certification exam according to the Databricksrules.
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Develop unit and integration tests for data processing code
- 3. Compare streaming tables and materialized views
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Use control flow operators in pipeline components
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 4: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 5: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
|
| Topic 6: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 7: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 8: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 9: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 10: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
>> Certified-Data-Engineer-Professional Braindumps Pdf <<
Valid Certified-Data-Engineer-Professional Exam Test | Reliable Certified-Data-Engineer-Professional Dumps Ppt
Choosing our Databricks vce dumps means you can closer to success. We have rich experienced in the real questions of Certified-Data-Engineer-Professional actual test. Our Certified-Data-Engineer-Professional vce files are affordable, latest and best quality with detailed answers and explanations, which can overcome the difficulty of real exam. You will save lots of time and money with our Certified-Data-Engineer-Professional Braindumps Torrent.
Databricks Certified Data Engineer Professional Sample Questions (Q172-Q177):
NEW QUESTION # 172
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
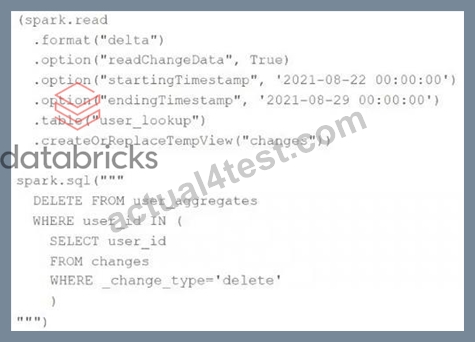
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- B. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- C. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- D. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- E. No; the change data feed only tracks inserts and updates not deleted records.
Answer: B
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 173
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
- A. CAN VIEW
- B. CAN MANAGE
- C. CAN RESTART
- D. CAN ATTACH TO
Answer: A
Explanation:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
NEW QUESTION # 174
A Delta Lake table was created with the below query:
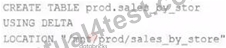
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. A new Delta transaction log Is created for the renamed table.
- B. The table reference in the metastore is updated and no data is changed.
- C. The table reference in the metastore is updated and all data files are moved.
- D. The table name change is recorded in the Delta transaction log.
- E. All related files and metadata are dropped and recreated in a single ACID transaction.
Answer: B
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 175
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
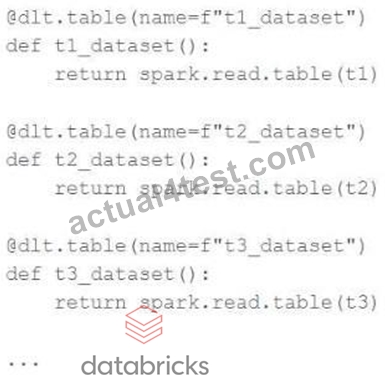
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
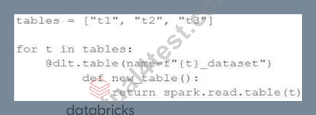
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
- D. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
Answer: C
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 176
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Use apply_changes without CDF and filter rows where _soft_deleted is true.
- B. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- C. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- D. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
Answer: C
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 177
......
All kinds of exams are changing with dynamic society because the requirements are changing all the time. To keep up with the newest regulations of the Databricks Certified Data Engineer Professional exam, our experts keep their eyes focusing on it. Expert team not only provides the high quality for the Certified-Data-Engineer-Professional Quiz guide consulting, also help users solve problems at the same time, leak fill a vacancy, and finally to deepen the user's impression, to solve the problem of Databricks Certified Data Engineer Professional test material and no longer make the same mistake.
Valid Certified-Data-Engineer-Professional Exam Test: https://www.actual4test.com/Certified-Data-Engineer-Professional_examcollection.html
- Achieve Success in Certified-Data-Engineer-Professional Exam with Databricks's Exam Questions and Pass on Your First Try 💮 Search for ▛ Certified-Data-Engineer-Professional ▟ and download exam materials for free through ▷ www.validtorrent.com ◁ 🆕Certified-Data-Engineer-Professional Valid Exam Online
- Certified-Data-Engineer-Professional Valid Test Test ✊ Exam Certified-Data-Engineer-Professional Tutorial 🙎 Certified-Data-Engineer-Professional Reliable Exam Sims 🥳 Open ✔ www.pdfvce.com ️✔️ and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download exam materials for free 🧹Exam Certified-Data-Engineer-Professional Reference
- Certified-Data-Engineer-Professional Test Braindumps: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Pass-Sure Torrent - Certified-Data-Engineer-Professional Ttest Questions 🧹 Enter ✔ www.prepawaypdf.com ️✔️ and search for ( Certified-Data-Engineer-Professional ) to download for free 🐯Exam Certified-Data-Engineer-Professional Reference
- Updates To The Databricks Certified-Data-Engineer-Professional Exam Are Free For 1 year 🚡 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ 🟣Exam Certified-Data-Engineer-Professional Reference
- Certified-Data-Engineer-Professional Latest Test Camp 🙁 Certified-Data-Engineer-Professional Learning Engine 👇 Certified-Data-Engineer-Professional Valid Exam Pass4sure 🙄 Open 「 www.practicevce.com 」 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download exam materials for free 🥞Certified-Data-Engineer-Professional Study Tool
- Certified-Data-Engineer-Professional Latest Dumps Ppt 🐵 Latest Real Certified-Data-Engineer-Professional Exam 🤿 Braindumps Certified-Data-Engineer-Professional Pdf 🥄 Open ➽ www.pdfvce.com 🢪 and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download exam materials for free 🐦Latest Real Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Latest Real Exam 🧓 Certified-Data-Engineer-Professional Valid Exam Online 🤨 Exam Certified-Data-Engineer-Professional Reference 🍦 Simply search for ➤ Certified-Data-Engineer-Professional ⮘ for free download on ( www.exam4labs.com ) 🧦Certified-Data-Engineer-Professional Examinations Actual Questions
- Updates To The Databricks Certified-Data-Engineer-Professional Exam Are Free For 1 year 🛳 Go to website ➡ www.pdfvce.com ️⬅️ open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free ⬆Certified-Data-Engineer-Professional Valid Exam Pass4sure
- Certified-Data-Engineer-Professional Valid Exam Online 🐯 Certified-Data-Engineer-Professional Valid Test Sims 🎄 Certified-Data-Engineer-Professional Exam Fees 🥢 Search for { Certified-Data-Engineer-Professional } and download it for free on ⏩ www.pass4test.com ⏪ website 😝Certified-Data-Engineer-Professional Learning Engine
- Certified-Data-Engineer-Professional Valid Test Test 🚙 Certified-Data-Engineer-Professional Study Tool 🧒 Certified-Data-Engineer-Professional Latest Dumps Ppt ⤵ Search for { Certified-Data-Engineer-Professional } and download it for free on ▶ www.pdfvce.com ◀ website 🕸Certified-Data-Engineer-Professional Study Tool
- 2026 Excellent Certified-Data-Engineer-Professional Braindumps Pdf | 100% Free Valid Certified-Data-Engineer-Professional Exam Test 🥴 Simply search for ( Certified-Data-Engineer-Professional ) for free download on ➡ www.torrentvce.com ️⬅️ 😩Certified-Data-Engineer-Professional Study Guide
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, freestyler.ws, www.stes.tyc.edu.tw, Disposable vapes