Our three kinds of AI-200 real exam includes the new information that you need to know to pass the test. PDF version is full of legible content to read and remember, support customers’ printing request, Software version of AI-200 practice materials supports simulation test system, and several times of setup with no restriction. App online version of AI-200 Learning Engine is suitable to all kinds of digital devices and offline exercise. You will find your favorite one if you have a try!
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
As an enthusiasts in IT industry, are you preparing for the important AI-200 exam? Why not let our ActualTorrent to help you? We provide not only the guarantee for you to Pass AI-200 Exam, but also the relaxing procedure of AI-200 exam preparation and the better after-sale service.
NEW QUESTION # 133
Hotspot Question
You are developing an application that uses a Python API to perform similarity queries against Azure Database for PostgreSQL. The application creates a new database connection for every request.
During peak traffic, the application intermittently fails to open new database sessions. Logs indicate that the maximum number of connections have been reached.
You need to configure the connection pooling strategy to reduce connection setup overhead and maximize reuse for the high-concurrency workload.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.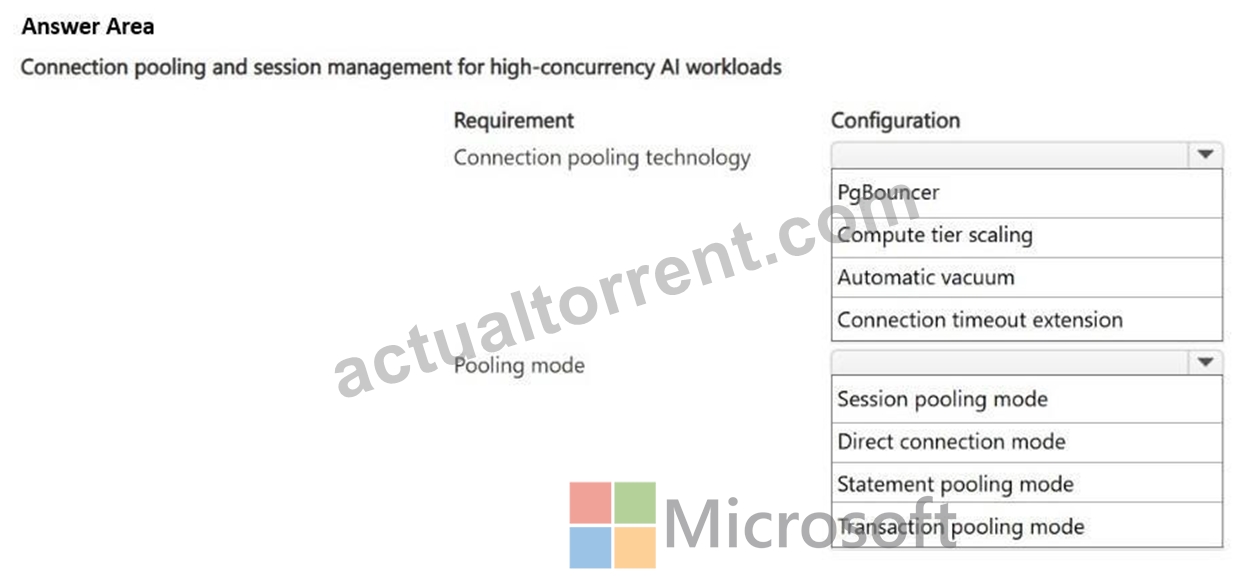
Answer:
Explanation: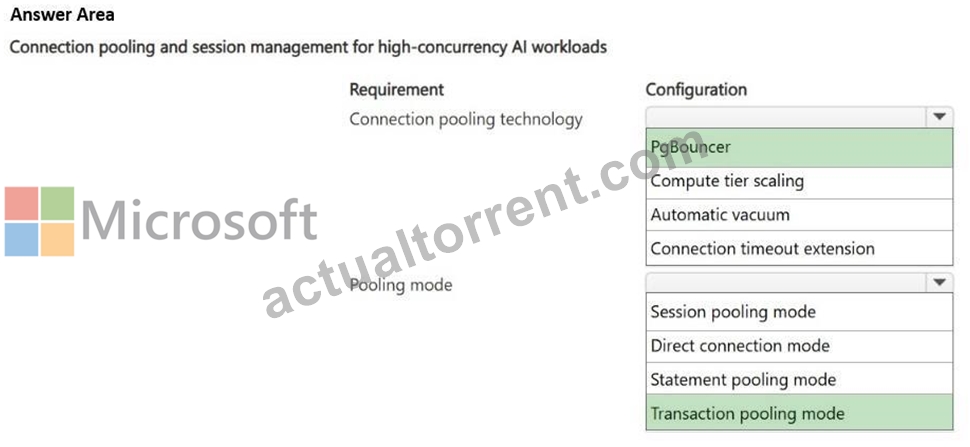
Explanation:
Box 1: PgBouncer
To resolve the connection exhaustion issue, you should use the built-in PgBouncer connection pooler configured in Transaction Pooling mode.
Because PostgreSQL uses a process-per-connection architecture, opening and closing a new session for every API request causes massive CPU/memory overhead and rapidly drains available slots during traffic spikes Box 2: Transaction Pooling mode Reference:
https://learn.microsoft.com/en-us/azure/postgresql/connectivity/concepts-connection-pooling-best-practices
NEW QUESTION # 134
You are developing several microservices to run on Azure Container Apps.
The microservices must allow HTTPS access by using a custom domain.
You need to configure the custom domain in Azure Container Apps.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.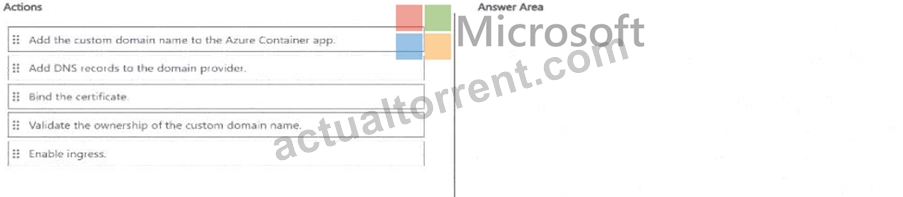
Answer:
Explanation: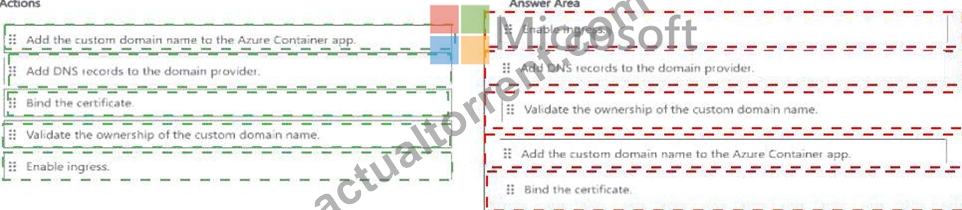
Explanation: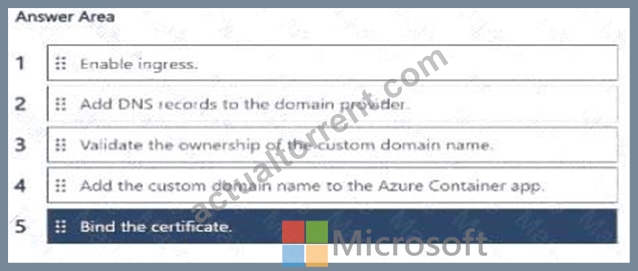
Verified answer: 1) Enable ingress; 2) add the required DNS records; 3) validate ownership of the custom domain; 4) add the custom domain to the Container App; 5) bind the certificate.
Detailed Explanation: A custom HTTPS hostname requires an ingress endpoint, DNS proof that the requester controls the hostname, the hostname association itself, and a TLS certificate bound to that hostname.
DNS records must exist before ownership validation can succeed. Once ownership is validated, the domain can be associated with the Container App and the certificate can be bound to provide HTTPS. Skipping ingress or DNS validation would prevent the hostname from being correctly routed and secured.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Custom domains and certificates in Container Apps
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
NEW QUESTION # 135
Drag and Drop Question
A recommendation system stores 3 million embeddings in Azure Database for PostgreSQL.
During peak hours, P95 similarity-query latency increases, and the cache hit ratio drops significantly.
You suspect that the vector index working set no longer fits in memory, resulting in more disk reads.
You need to scale server resources and validate the outcome.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.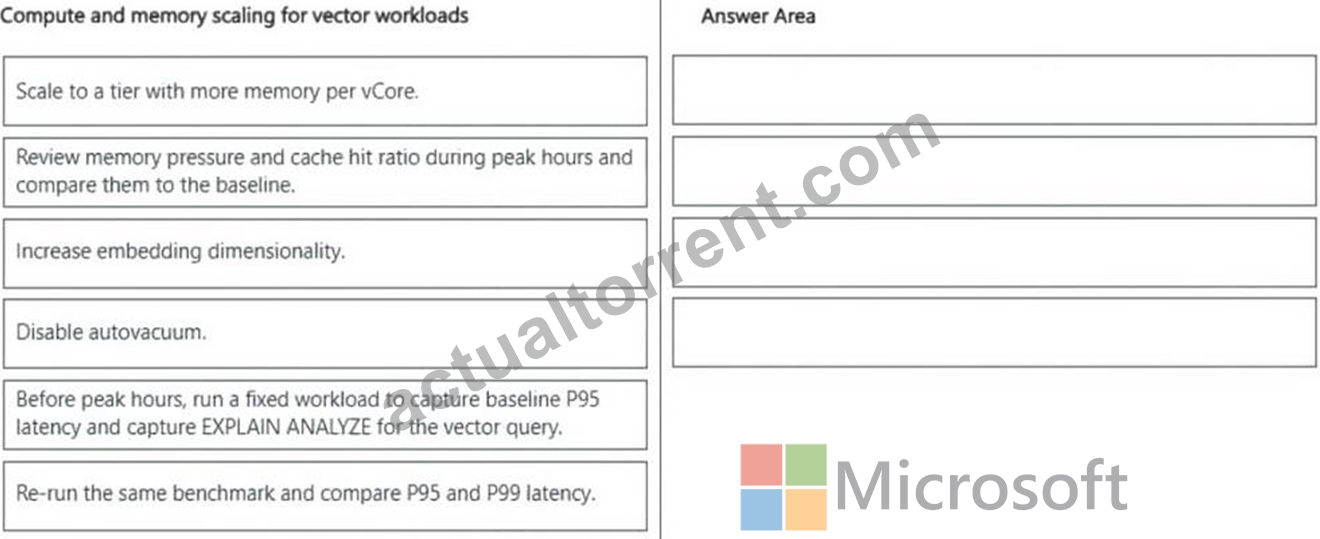
Answer:
Explanation: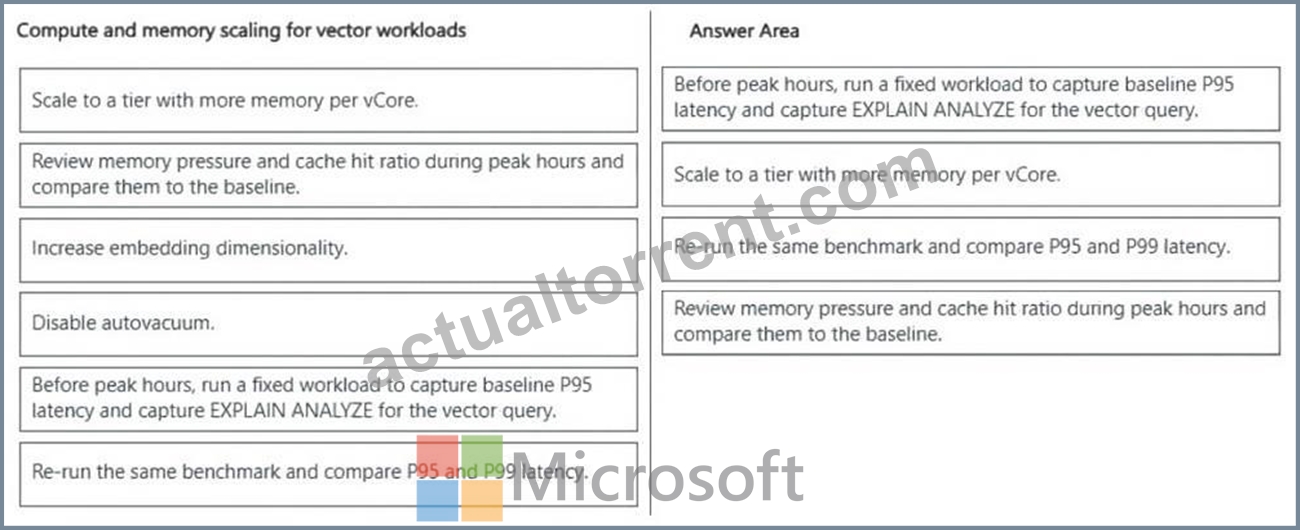
Explanation:
Step 1: Before peak hours, run a fixed workload to capture baseline P95 latency and capture EXPLAIN ANALYZE for the vector query Establishing a baseline is crucial for performance tuning. Running EXPLAIN ANALYZE provides deep insight into whether the query is actually using the vector index (like HNSW or IVFFlat) or falling back to a slow sequential scan.
Step 2: Scale to a tier with more memory per vCore
Since the problem states that the vector index working set no longer fits in memory, scaling to a tier with higher memory (such as Memory-Optimized tiers) directly solves the root cause by allowing the RAM to fully cache the vector index, eliminating slow disk reads.
Step 3: Re-run the same benchmark and compare P95 and P99 latency
To validate the outcome of your scaling operations, you must run the identical benchmark workload and compare high-percentile latencies (P95, P99) against your baseline to prove the bottleneck was resolved.
Step 4: Review memory pressure and cache hit ratio during peak hours and compare them to the baseline This step confirms the success of the resource scaling. A successful remediation will show a significantly increased cache hit ratio and reduced memory pressure/disk I/O compared to the baseline metrics.
Reference:
https://www.pgedge.com/blog/ai-features-in-pgadmin-ai-insights-for-explain-plans
NEW QUESTION # 136
You are developing an AI application. The application configuration will depend on a dynamically retrieved value of a designated key stored in an Azure App Configuration resource.
You must deploy the application to the test, staging, and production environments.
You need to be able to set the value differently in each environment.
Which feature of Azure App Configuration resource should you use?
Answer: C
Explanation:
You should use the Label feature of the Azure App Configuration resource.
In Azure App Configuration, keys can optionally include a label, which acts as a dimension or tag to create distinct variants of the same key. This allows you to store environment-specific values (such as test, staging, and production) under a single key name and load the appropriate configuration dynamically based on the current deployment environment.
References:
https://learn.microsoft.com/en-us/answers/questions/2108879/azure-app-configuration-resource-manager-api-is-de
NEW QUESTION # 137
You are deploying a model in Azure AI Foundry and must ensure the endpoint can handle unpredictable bursts of traffic while keeping cost low during idle periods. Which deployment type should you choose?
Answer: B
Explanation:
Standard pay-as-you-go deployments scale with token-based consumption and don't require reserving fixed throughput, making them cost-efficient for variable or bursty workloads. PTU is better suited for predictable, high-volume, latency-sensitive workloads where reserved capacity is justified.
NEW QUESTION # 138
......
Our customers receive Microsoft AI-200 questions updates for up to 365 days after their purchase. They can also try a free demo for satisfaction before buying our Microsoft AI-200 dumps. And a 24/7 support system assists them whenever they are stuck in any problem or issue. This Microsoft AI-200 Questions is a complete package and a blessing for candidates who want to prepare quickly for the AI-200 exam. Buy It Now!
Sample AI-200 Questions: https://www.actualtorrent.com/AI-200-questions-answers.html