さらに、Pass4Test Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=18_O260moohonbjfw7GHlXpqWges2GG4P
当社DatabricksのウェブサイトPass4Testは非常に安全で定期的なプラットフォームです。 第一に、Databricks-Certified-Professional-Data-Engineer試験トレントの購入プロセス中に会社のウェブサイトのセキュリティを保証します。 第二に、Databricks-Certified-Professional-Data-Engineer模擬テストの購入に関するすべての顧客情報については、専門の担当者が管理し、情報開示は一切行われません。 最後になりましたが、最も重要なのは、Databricks-Certified-Professional-Data-Engineer試験の教材には、98%から100%の高い合格率に基づく高品質のメリットがあります。 Databricks Certified Professional Data Engineer Examデータは他の言葉よりも雄弁です。 Databricks-Certified-Professional-Data-Engineerトレーニング準備に自信を持ってください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Topic 2: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Topic 3: Data Ingestion | 15-20% | - Batch ingestion methods
|
| Topic 4: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 5: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
>> Databricks-Certified-Professional-Data-Engineer基礎問題集 <<
あなたはIT業界の玄人になりたいですか?ここでDatabricks Databricks-Certified-Professional-Data-Engineer認定試験の問題集をお勧めます。Databricks-Certified-Professional-Data-Engineer認定試験の問題集は大勢の人の注目を集め、とても人気がある商品です。Databricks-Certified-Professional-Data-Engineer認定試験の問題集はなぜそんなに人気がありますか?Databricks-Certified-Professional-Data-Engineer認定試験の問題集は最も全面的なIT知識を提供できるからです。では、躊躇しなくて、Databricks Databricks-Certified-Professional-Data-Engineer認定試験の問題集を早く購入しましょう!
質問 # 27
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
正解:E
解説:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
質問 # 28
Which of the following table constraints that can be enforced on Delta lake tables are supported?
正解:E
解説:
Explanation
The answer is Not Null, Check Constraints
https://docs.microsoft.com/en-us/azure/databricks/delta/delta-constraints
* CREATE TABLE events( id LONG,
* date STRING,
* location STRING,
* description STRING
* ) USING DELTA;
ALTER TABLE events CHANGE COLUMN id SET NOT NULL;
ALTER TABLE events ADD CONSTRAINT dateWithinRange CHECK (date > '1900-01-01'); Note: Databricks as of DBR 11.1 added support for Primary Key and Foreign Key when Unity Catalog is enabled but this is for information purposes only these are not actually enforced. You may ask then why are we defining these if they are not enforced, so especially these information constraints are very helpful if you have a BI tool that can benefit from knowing the relationship between the tables, so it will be easy when creating reports/dashboards or understanding the data model when using any Data modeling tool.
Primary and Foreign Key
Graphical user interface, text, application, email Description automatically generated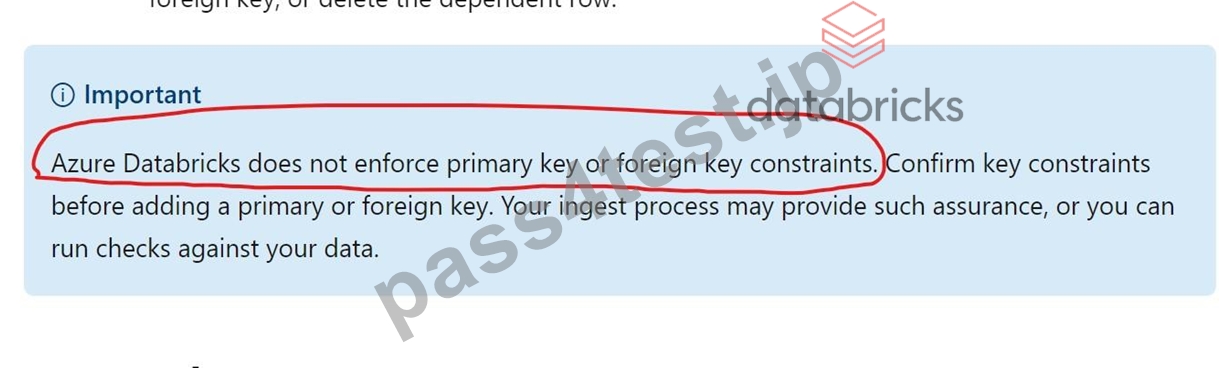
質問 # 29
You are trying to create an object by joining two tables that and it is accessible to data scientist's team, so it does not get dropped if the cluster restarts or if the notebook is detached. What type of object are you trying to create?
正解:B
解説:
Explanation
Answer is View, A view can be used to join multiple tables but also persist into meta stores so others can accesses it
質問 # 30
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
正解:A
解説:
Explanation
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills. Verified References:
[Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Skew" section.
質問 # 31
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
正解:B
解説:
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade-off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Optimize" section. https://docs.databricks.com/en/delta/tune-file-size.html#autotune-table 'Autotune file size based on workload'
質問 # 32
......
なぜ我々のDatabricksのDatabricks-Certified-Professional-Data-Engineerソフトに自信があるかと聞かれたら、まずは我々Pass4Testの豊富な経験があるチームです、次は弊社の商品を利用してDatabricksのDatabricks-Certified-Professional-Data-Engineer試験に合格する多くのお客様です。DatabricksのDatabricks-Certified-Professional-Data-Engineer試験は国際的に認められてあなたはこの認証がほしいですか。弊社のDatabricksのDatabricks-Certified-Professional-Data-Engineer試験のソフトを通して、あなたはリラクスで得られます。
Databricks-Certified-Professional-Data-Engineer受験方法: https://www.pass4test.jp/Databricks-Certified-Professional-Data-Engineer.html
P.S.Pass4TestがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=18_O260moohonbjfw7GHlXpqWges2GG4P