Databricks Certified-Data-Engineer-Professional완벽한덤프 - Certified-Data-Engineer-Professional최신업데이트인증공부자료

KoreaDumps는 고객님께서Databricks Certified-Data-Engineer-Professional첫번째 시험에서 패스할수 있도록 최선을 다하고 있습니다. 만일 어떤 이유로 인해 고객님이Databricks Certified-Data-Engineer-Professional시험에서 실패를 한다면 KoreaDumps는Databricks Certified-Data-Engineer-Professional덤프비용 전액을 환불 해드립니다. 시중에서 가장 최신버전인Databricks Certified-Data-Engineer-Professional덤프로 시험패스 예약하세요.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 6. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
>> Databricks Certified-Data-Engineer-Professional완벽한 덤프 <<
Databricks Certified-Data-Engineer-Professional최신 업데이트 인증공부자료 - Certified-Data-Engineer-Professional최신덤프문제
꿈을 안고 사는 인생이 멋진 인생입니다. 고객님의 최근의 꿈은 승진이나 연봉인상이 아닐가 싶습니다. Databricks인증 Certified-Data-Engineer-Professional시험은 IT인증시험중 가장 인기있는 국제승인 자격증을 취득하는데서의 필수시험과목입니다.그만큼 시험문제가 어려워 시험도전할 용기가 없다구요? 이제 이런 걱정은 버리셔도 됩니다. KoreaDumps의 Databricks인증 Certified-Data-Engineer-Professional덤프는Databricks인증 Certified-Data-Engineer-Professional시험에 대비한 공부자료로서 시험적중율 100%입니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q196-Q201):
질문 # 196
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
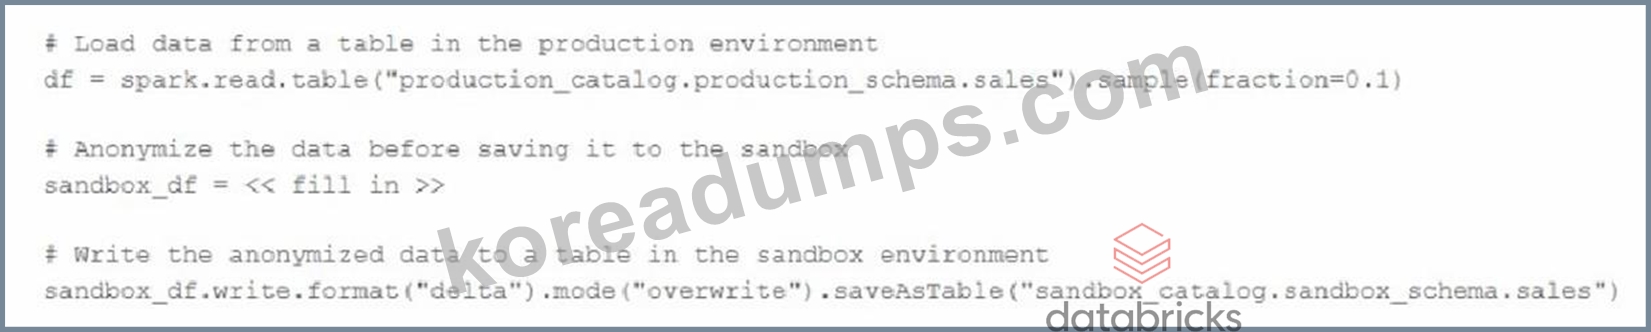
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("user_email", F.sha2 ("user_email"))
- B. df.withColumn ("hashed_email", sha2 ("user_email"))
- C. df.withColumn ("user_emai", F.expr("uuid()"))
- D. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
정답:A
설명:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
질문 # 197
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table")
\
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
- A. The event_date column is outside the table's partitioning and Z-ordering scheme.
- B. The filter is executed only after the full data scan, preventing data skipping.
- C. The Delta table lacks optimization that enables dynamic file pruning.
- D. The filter condition involves a data type excluded from data skipping support.
정답:A
설명:
Delta Lake's data skipping relies on partitioning and clustering (such as Z-ordering) on the filtered columns. If event_date is neither a partition column nor included in the table's clustering strategy, Spark must scan most files because file-level statistics cannot be effectively used to prune irrelevant data.
질문 # 198
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
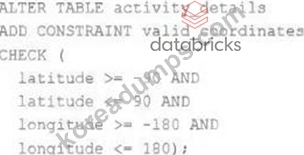
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- B. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- C. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- D. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
- E. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
정답:E
설명:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
질문 # 199
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
- A. Use compute policies to set system properties, environment variables, and Spark configuration parameters.
- B. Add libraries to compute policies
- C. Use secrets in init scripts to store configuration data
- D. Install libraries on DBFS
- E. Create init scripts on DBFS.
정답:A,E
설명:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
질문 # 200
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
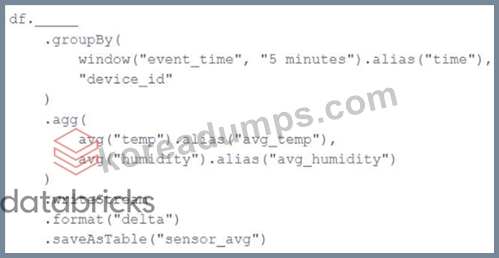
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. slidingWindow("event_time", "10 minutes")
- B. await("event_time + `10 minutes'")
- C. withWatermark("event_time", "10 minutes")
- D. delayWrite("event_time", "10 minutes")
- E. awaitArrival("event_time", "10 minutes")
정답:C
설명:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
질문 # 201
......
한번에Databricks인증Certified-Data-Engineer-Professional시험을 패스하고 싶으시다면 완전 페펙트한 준비가 필요합니다. 완벽한 관연 지식터득은 물론입니다. 우리KoreaDumps의 자료들은 여러분의 이런 시험준비에 많은 도움이 될 것입니다.
Certified-Data-Engineer-Professional최신 업데이트 인증공부자료: https://www.koreadumps.com/Certified-Data-Engineer-Professional_exam-braindumps.html
- 퍼펙트한 Certified-Data-Engineer-Professional완벽한 덤프 최신버전 덤프자료 🚢 { www.pass4test.net }에서▛ Certified-Data-Engineer-Professional ▟를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional퍼펙트 인증공부자료
- 시험패스 가능한 Certified-Data-Engineer-Professional완벽한 덤프 덤프공부문제 ✌ 무료로 다운로드하려면☀ www.itdumpskr.com ️☀️로 이동하여➡ Certified-Data-Engineer-Professional ️⬅️를 검색하십시오Certified-Data-Engineer-Professional최신버전 덤프자료
- 최신버전 Certified-Data-Engineer-Professional완벽한 덤프 완벽한 시험대비 덤프공부 👶 무료 다운로드를 위해 지금➥ www.exampassdump.com 🡄에서▷ Certified-Data-Engineer-Professional ◁검색Certified-Data-Engineer-Professional높은 통과율 인기 시험자료
- Certified-Data-Engineer-Professional시험대비 덤프 최신자료 ⤵ Certified-Data-Engineer-Professional인증시험 덤프공부 🥳 Certified-Data-Engineer-Professional시험대비 공부하기 🎨 ➽ www.itdumpskr.com 🢪웹사이트를 열고「 Certified-Data-Engineer-Professional 」를 검색하여 무료 다운로드Certified-Data-Engineer-Professional퍼펙트 인증공부자료
- Databricks Certified-Data-Engineer-Professional 덤프 🤪 ▶ Certified-Data-Engineer-Professional ◀를 무료로 다운로드하려면[ www.itdumpskr.com ]웹사이트를 입력하세요Certified-Data-Engineer-Professional시험덤프샘플
- 퍼펙트한 Certified-Data-Engineer-Professional완벽한 덤프 최신버전 덤프자료 🌰 무료 다운로드를 위해⏩ Certified-Data-Engineer-Professional ⏪를 검색하려면「 www.itdumpskr.com 」을(를) 입력하십시오Certified-Data-Engineer-Professional높은 통과율 시험대비 공부문제
- 시험패스에 유효한 최신버전 Certified-Data-Engineer-Professional완벽한 덤프 최신 덤프모음집 👨 ➤ Certified-Data-Engineer-Professional ⮘를 무료로 다운로드하려면《 www.itdumpskr.com 》웹사이트를 입력하세요Certified-Data-Engineer-Professional인기시험자료
- Certified-Data-Engineer-Professional시험패스 인증덤프자료 😉 Certified-Data-Engineer-Professional시험대비 덤프 최신자료 📳 Certified-Data-Engineer-Professional적중율 높은 시험대비덤프 📃 ➡ www.itdumpskr.com ️⬅️웹사이트에서➽ Certified-Data-Engineer-Professional 🢪를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional합격보장 가능 시험대비자료
- Certified-Data-Engineer-Professional합격보장 가능 시험대비자료 ❗ Certified-Data-Engineer-Professional덤프최신문제 🚞 Certified-Data-Engineer-Professional시험대비 덤프 최신자료 🌹 ➽ www.dumptop.com 🢪웹사이트에서{ Certified-Data-Engineer-Professional }를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional적중율 높은 시험대비덤프
- Certified-Data-Engineer-Professional완벽한 덤프 덤프문제모음집 😖 무료 다운로드를 위해 지금⇛ www.itdumpskr.com ⇚에서☀ Certified-Data-Engineer-Professional ️☀️검색Certified-Data-Engineer-Professional퍼펙트 덤프 최신 샘플
- 시험준비에 가장 좋은 Certified-Data-Engineer-Professional완벽한 덤프 인증덤프 🚅 ⇛ www.koreadumps.com ⇚은“ Certified-Data-Engineer-Professional ”무료 다운로드를 받을 수 있는 최고의 사이트입니다Certified-Data-Engineer-Professional인증덤프데모문제
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, semasocial.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes